
In a natural language processing (NLP) pipeline, raw text must be processed by a tokenizer before it is fed into a model. What is the definition of a "token" in this pipeline?
Select an answer to reveal the explanation.
Short Explanation
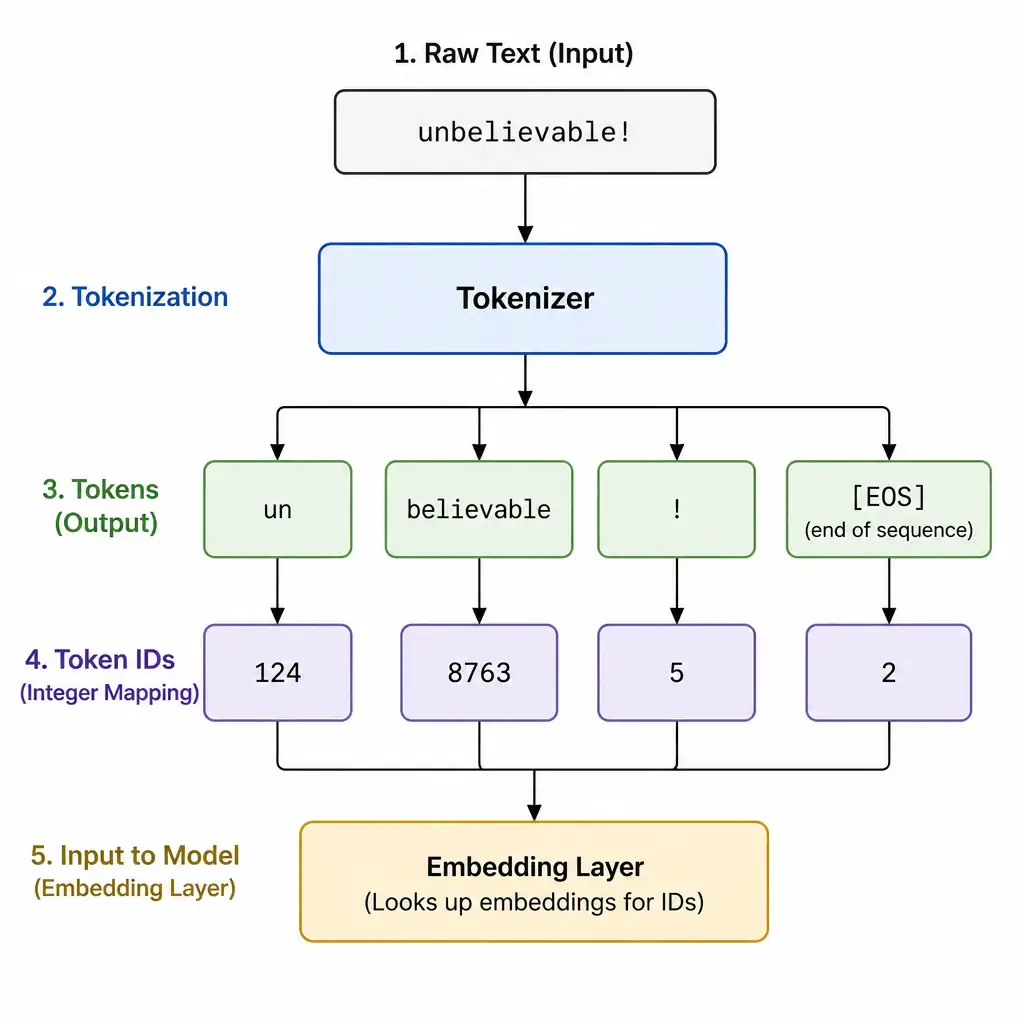
Here's the deal: computers don't read raw text the way you do, so a tokenizer cuts it into standard little pieces called tokens. The token is the fundamental unit of text—words, subwords, or characters—that the model turns into numbers. If you chose the answer calling it a fundamental unit of text, you nailed it.
Full Explanation
In Natural Language Processing (NLP), tokenization is the foundational step of preprocessing text. The token is defined as the atomic unit of text that a machine learning model operates upon. Depending on the tokenization strategy employed, tokens can be defined at different granularities: 1. Word-level tokenization: the text is split by spaces and punctuation, where each word becomes a token. While intuitive, this leads to a large vocabulary size and cannot handle out-of-vocabulary (OOV) words or spelling mistakes well. 2. Character-level tokenization: the text is split into individual letters and punctuation. This results in a very small vocabulary (typically under 100 characters) but makes sequences extremely long and makes it harder for the model to learn word-level semantics. 3. Subword-level tokenization (standard for modern LLMs): methods like Byte-Pair Encoding (BPE) or WordPiece split common words into whole tokens and rare words into smaller subwords (for example, unwanted might become un and wanted). This strikes an ideal balance, keeping the vocabulary manageable while easily handling new or misspelled words. The answer calling a token a fundamental unit of text—such as a word, subword, or character—that serves as the input element for the model is correct. The answer describing a classification label that represents the category of the input document is incorrect because that describes a class label or target variable in classification tasks, not an input unit of text. The answer describing a high-dimensional vector containing the semantic meaning of a word is incorrect because that describes a word embedding or vector representation, which is what a token is converted into after tokenization, but the token itself is the textual unit. The answer describing a specialized metadata symbol used to demarcate the start and end of a paragraph is incorrect because that describes control tokens (like [SEP], [CLS], or `), which are a specific subset of tokens, but the term token refers broadly to any input unit of text.