
When selecting a model for natural language processing tasks like sentiment analysis or named entity recognition, what is the primary architectural advantage of using Google's BERT model?
Select an answer to reveal the explanation.
Short Explanation
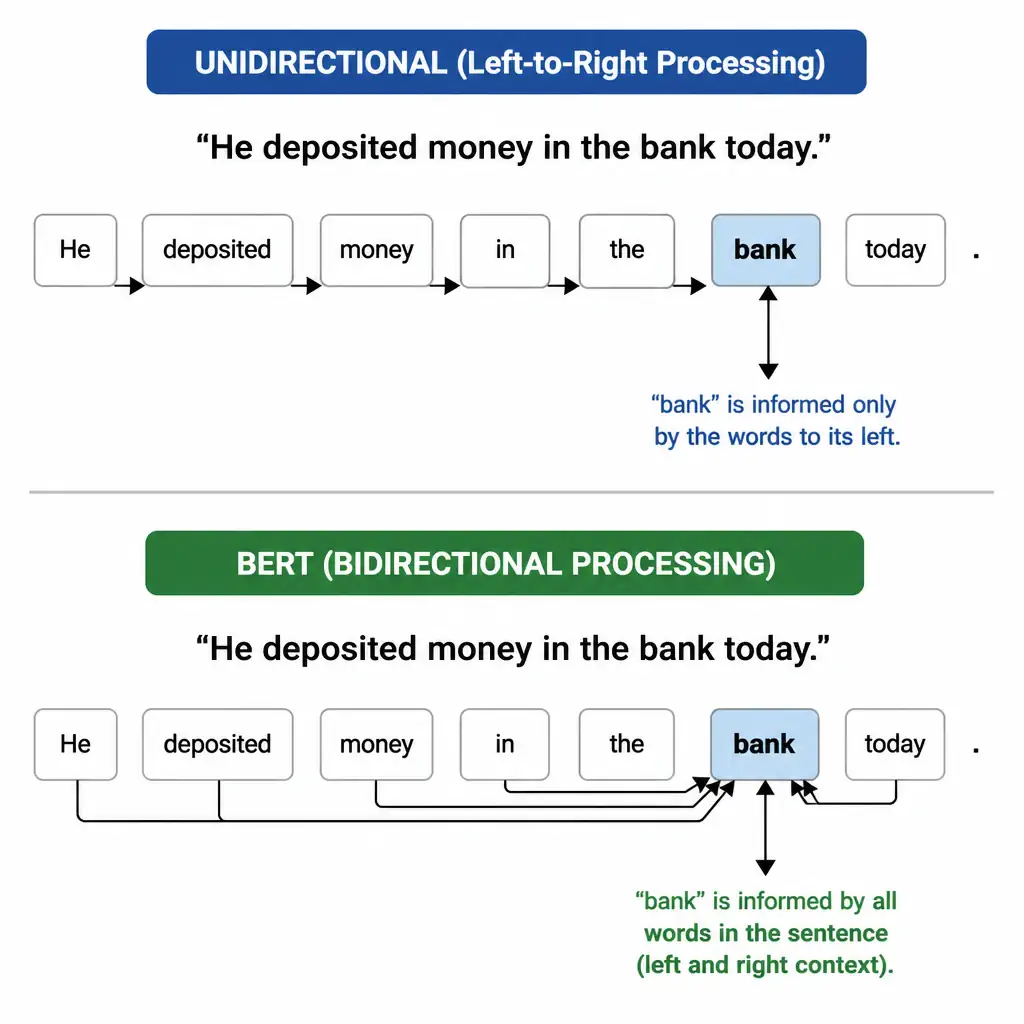
Before BERT, many language models read sentences with tunnel vision, left-to-right or right-to-left, so you couldn't capture full context around a word. BERT uses the Transformer encoder to look at words on both sides of a target word at once, and that bidirectional context is why it's so strong for understanding meaning in NLP tasks.
Full Explanation
BERT (Bidirectional Encoder Representations from Transformers), introduced by Google in 2018, is a milestone architecture in natural language processing. The key innovation of BERT lies in its bidirectional training approach. Traditional language models, such as unidirectional LSTMs or autoregressive models like the GPT series, are trained to predict the next word in a sequence given the previous words left-to-right. This prevents them from looking ahead, which is a major limitation for tasks that require a complete understanding of a sentence's context. BERT solves this by using a Masked Language Model pre-training objective: it randomly masks, typically 15%, of the input tokens and then tries to predict the masked words based on the surrounding context. Because the training objective is prediction of masked tokens rather than next-token prediction, the self-attention mechanism in the Transformer encoder can aggregate context from both the left and right sides of the target token simultaneously across all layers. This yields contextual representations that are highly effective for downstream tasks like question answering, named entity recognition, and sentence classification. The claim that it is computationally lightweight and can be trained from scratch in minutes on standard consumer hardware is incorrect because training BERT from scratch requires immense computational resources, such as hundreds of GPU or TPU hours, and massive datasets. The claim that it is designed as an autoregressive decoder optimized exclusively for text generation is incorrect because BERT is an encoder-only model, not a decoder-only model, and it is optimized for understanding and representation tasks rather than generative text tasks like GPT. The claim that it is significantly smaller and has fewer parameters than traditional RNNs is incorrect because BERT-Base has 110 million parameters and BERT-Large has 340 million, making these models significantly larger and more computationally expensive than traditional RNNs or LSTMs.