
A developer is using the Hugging Face Transformers library to build an email spam classifier. Instead of designing a neural network architecture and training it from scratch, they load a pre-trained model. What is the primary advantage of utilizing a pre-trained model for this classification task?
Select an answer to reveal the explanation.
Short Explanation
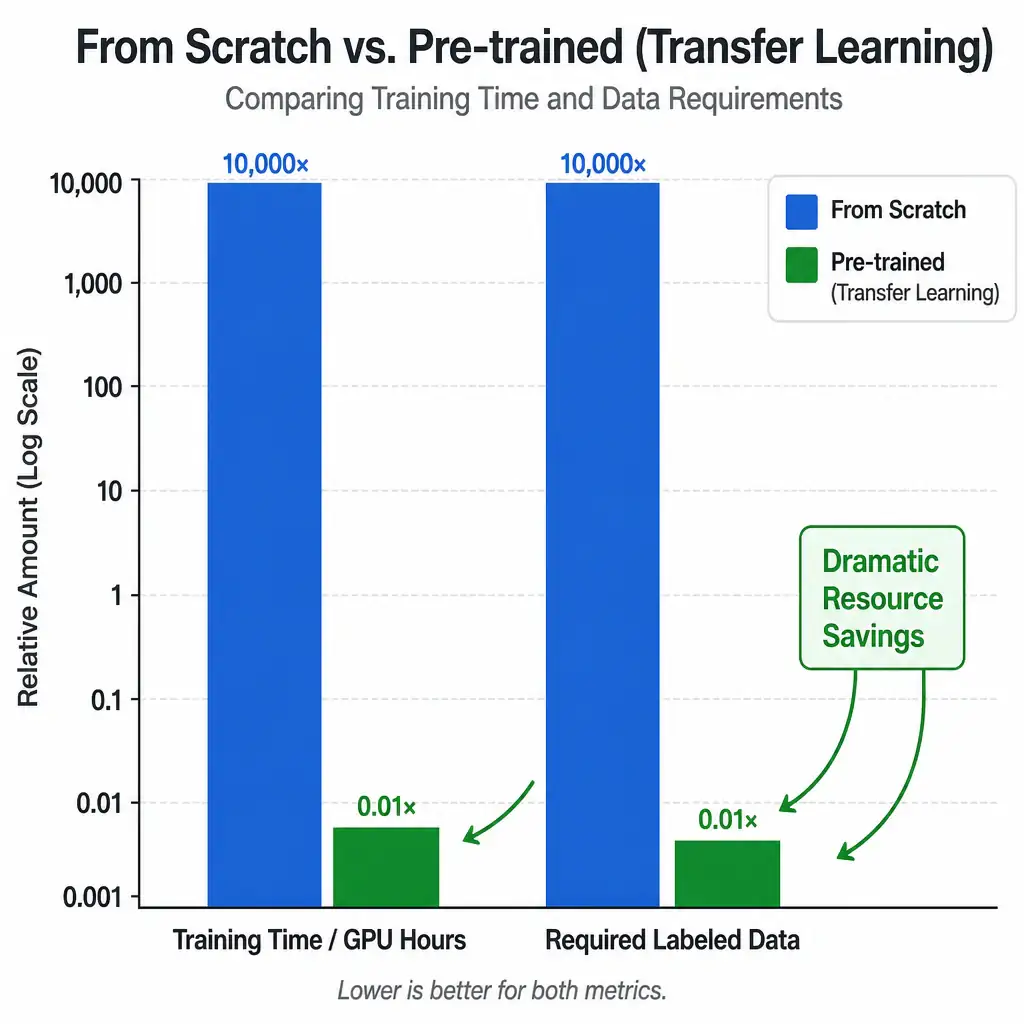
Check this out: you're not starting from zero. A pre-trained model already understands language, so you only need a small set of labeled spam and non-spam emails and far less compute to get strong results.
Full Explanation
Using pre-trained models is the cornerstone of transfer learning in modern machine learning. In natural language processing, pre-trained models such as BERT, RoBERTa, or DistilBERT are trained on massive, multi-gigabyte corpora of unlabeled text. During this pre-training, the model learns the foundational syntax, semantics, and context of language.
When a developer uses a pre-trained model for a specific task like email spam classification, they only need to perform a process called fine-tuning. The advantages include: 1. Data Efficiency: Training a deep learning model from scratch requires vast amounts of labeled data, often millions of samples, to avoid overfitting. A pre-trained model already possesses general language features, so it can achieve state-of-the-art performance with only a few hundred or thousand labeled examples. 2. Computational Savings: Pre-training requires weeks of computation on large-scale GPU clusters. Fine-tuning a pre-trained model takes a fraction of that time, minutes to a few hours on a single GPU, which dramatically lowers cloud compute costs and carbon footprints.
The claim that pre-training makes the model's internal weights and decision-making logic highly interpretable and easy to audit is incorrect because deep learning models, especially large pre-trained transformers, are black boxes with millions or billions of parameters. They are notoriously difficult to interpret compared to simpler models like decision trees or logistic regression.
The claim that pre-training guarantees a 100% accuracy rate, completely eliminating false positives and false negatives on the validation set, is incorrect because pre-trained models are not guaranteed to be perfect or 100% accurate; performance depends heavily on the quality and representation of the fine-tuning data.
The claim that pre-training allows the model to run exclusively on CPU hardware, rendering GPU acceleration completely unnecessary, is incorrect because pre-trained models can run on both CPUs and GPUs. In fact, training or fine-tuning them on a CPU is extremely slow and inefficient, making GPU acceleration highly recommended.