
When evaluating static word embedding techniques for natural language processing, what is the primary difference in how Word2Vec and GloVe (Global Vectors) generate their word representations?
Select an answer to reveal the explanation.
Short Explanation
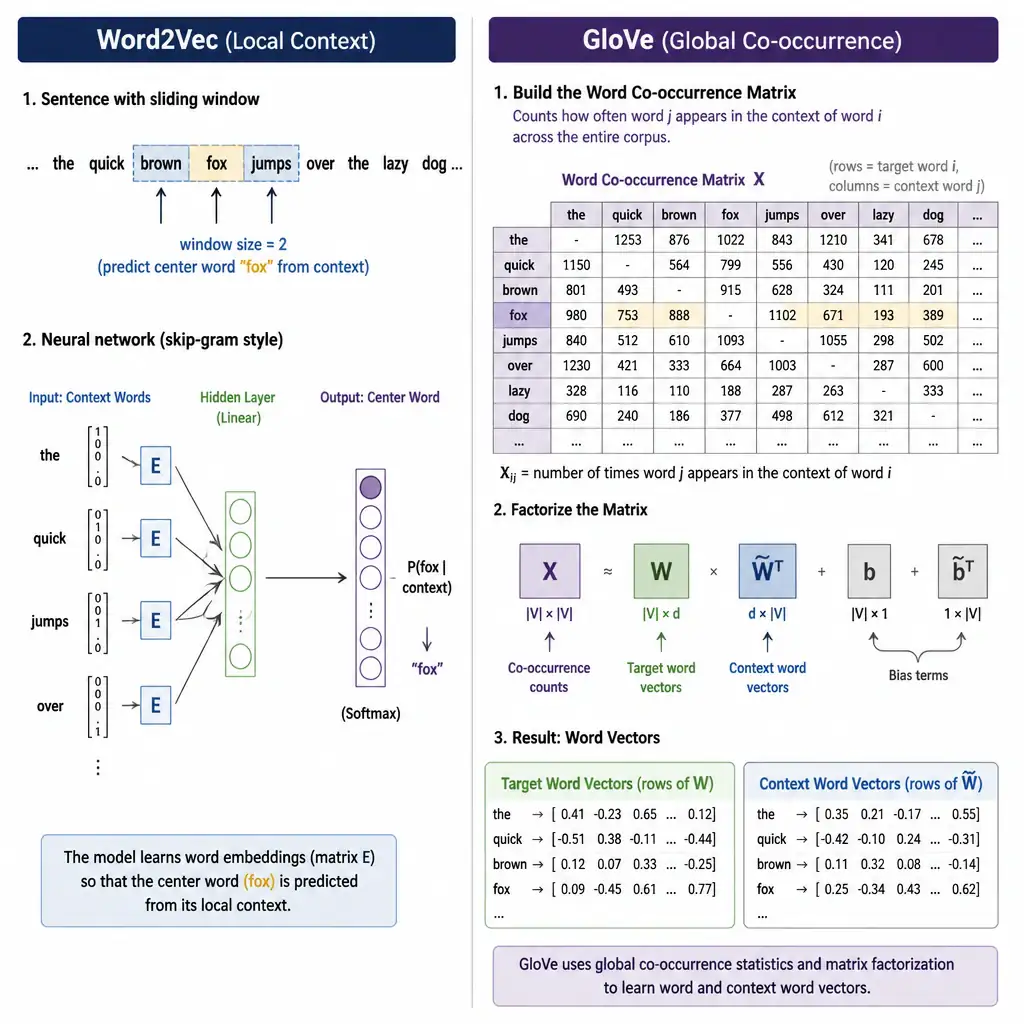
You’ve got to see Word2Vec as the local predictor and GloVe as the global counter. Word2Vec slides a small window through text and predicts nearby words, while GloVe builds the whole corpus’s co-occurrence matrix and factors it. That local predictive versus global count-based split is the key.
Full Explanation
Both Word2Vec and GloVe are static word embedding techniques that represent words as dense vectors in a continuous vector space, capturing semantic and syntactic relationships. However, their optimization objectives and underlying training methodologies differ significantly.
The correct distinction is that Word2Vec learns embeddings by predicting context words using local sliding windows, while GloVe learns by factoring a global word-word co-occurrence matrix.
1. Word2Vec (Predictive Model): Developed by Google, Word2Vec utilizes a local context window approach. It processes text sequentially using one of two architectures: Continuous Bag of Words (CBOW), which predicts a target word given its surrounding context words, and Skip-gram, which predicts surrounding context words given a single target word. The model uses a shallow, two-layer neural network trained via optimization techniques like negative sampling or hierarchical softmax. It adjusts vector weights based on local prediction errors.
2. GloVe (Global Vectors for Word Representation - Count-Based Model): Developed by Stanford, GloVe combines the advantages of global matrix factorization, like Latent Semantic Analysis, and local context window methods. It constructs a global word-word co-occurrence matrix X, where entry Xij represents the number of times word i appears in the context of word j across the entire corpus. The model then minimizes a weighted least-squares objective function to factorize this matrix, directly utilizing the global statistical ratios of word co-occurrences to construct the vector space.
The claim that Word2Vec is used strictly for text classification, whereas GloVe is designed only for regression tasks, is incorrect because both Word2Vec and GloVe generate unsupervised word embeddings that can be used for any downstream task, including both classification and regression.
The claim that Word2Vec is a simple count-based frequency model, while GloVe relies on a deep neural network to predict context, is incorrect because it reverses the definitions: GloVe is the count-based model using global co-occurrences, while Word2Vec is the predictive local window model.
The claim that Word2Vec produces dynamic, context-aware embeddings, while GloVe produces static, context-independent embeddings, is incorrect because both Word2Vec and GloVe generate static embeddings, meaning a word has the same vector representation regardless of its context in a new sentence, unlike modern contextual embeddings like BERT or GPT.