
A software engineer is implementing a Bag-of-Words (BoW) model to represent text documents numerically. How is a single document represented after applying this technique?
Select an answer to reveal the explanation.
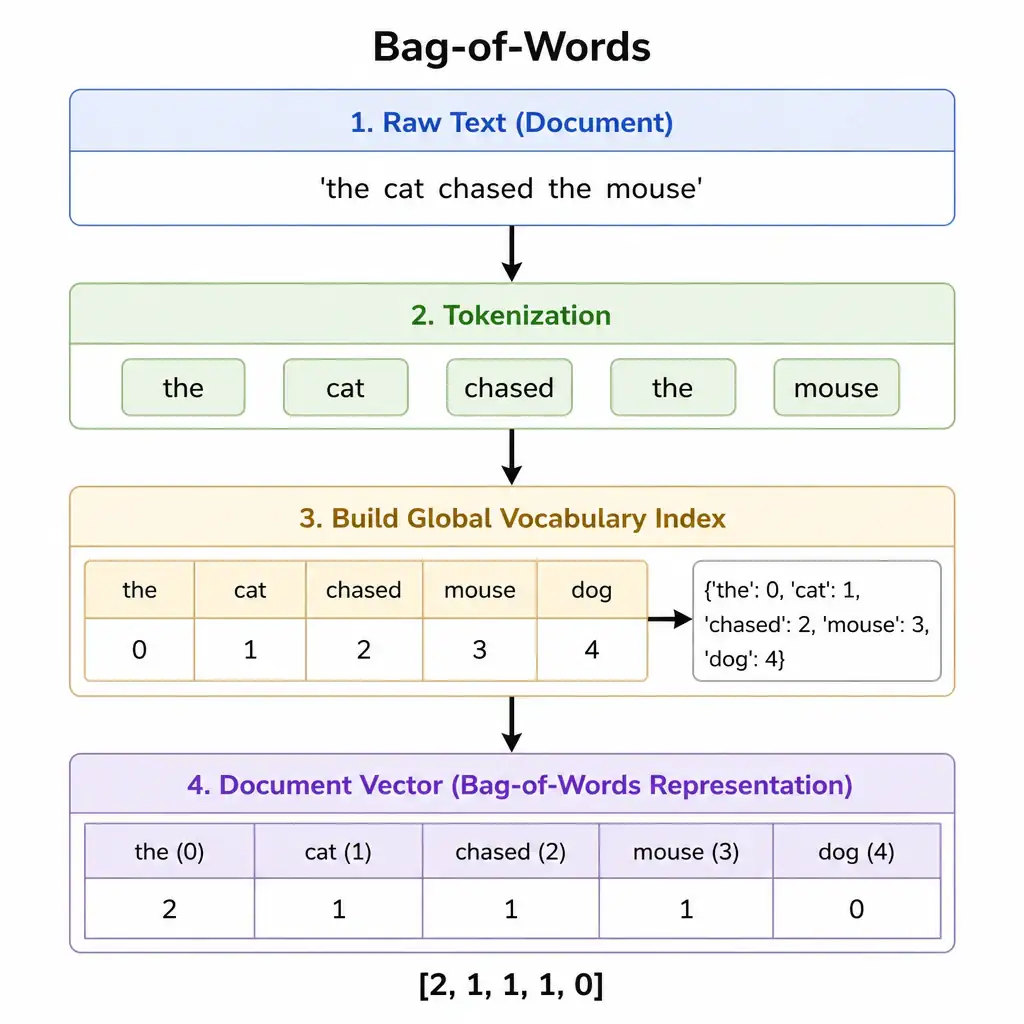
Short Explanation
Bag-of-Words throws all words into a bag, ignores grammar and order, and just counts how often each vocabulary word appears. You end up with a fixed-size vector where each slot is a word and the value is its count. It's not a sentiment score, grammar tree, or dense transformer embedding.
Full Explanation
The Bag-of-Words (BoW) model is one of the simplest and most fundamental techniques used in natural language processing (NLP) to represent text data numerically. Machine learning models require numerical inputs, but raw text is categorical. To bridge this gap, BoW converts a document into a structured vector.
The process begins by establishing a global vocabulary, which is a list of all unique words found across the entire dataset of documents. For a single document, the BoW representation is a vector whose length is equal to the size of this vocabulary. Each position (or index) in the vector corresponds to a specific word in the vocabulary. The value stored at that index is the frequency of that word's occurrence in the document. For instance, if the word 'router' is at index 42 in the vocabulary and appears three times in the document, the vector will have a value of 3 at index 42. Since most documents only contain a small fraction of the total vocabulary, BoW vectors are typically highly sparse, containing mostly zeros.
While computationally simple and effective for basic classification tasks (such as spam filtering), BoW has two major drawbacks. First, it disregards grammar, word order, and syntax (meaning 'not bad' and 'bad, not' produce identical vectors). Second, it does not capture semantic similarity (treating 'huge' and 'large' as completely independent dimensions).
Reviewing the incorrect choices: - The continuous scalar value representing overall semantic sentiment is incorrect because BoW does not produce a scalar sentiment value. - The hierarchical tree structure outlining grammatical relationships and parts of speech is incorrect because it describes a dependency or constituency parse tree, which shows grammatical structures rather than word frequencies. - The low-dimensional dense embedding vector generated by a pre-trained transformer model is incorrect because it refers to dense word or sentence embeddings (such as those from Word2Vec or BERT), which are low-dimensional and continuous, unlike high-dimensional, sparse BoW vectors.