
A developer has selected a pre-trained BERT model for a project. Which set of tasks is this model specifically designed to handle effectively through fine-tuning?
Select an answer to reveal the explanation.
Short Explanation
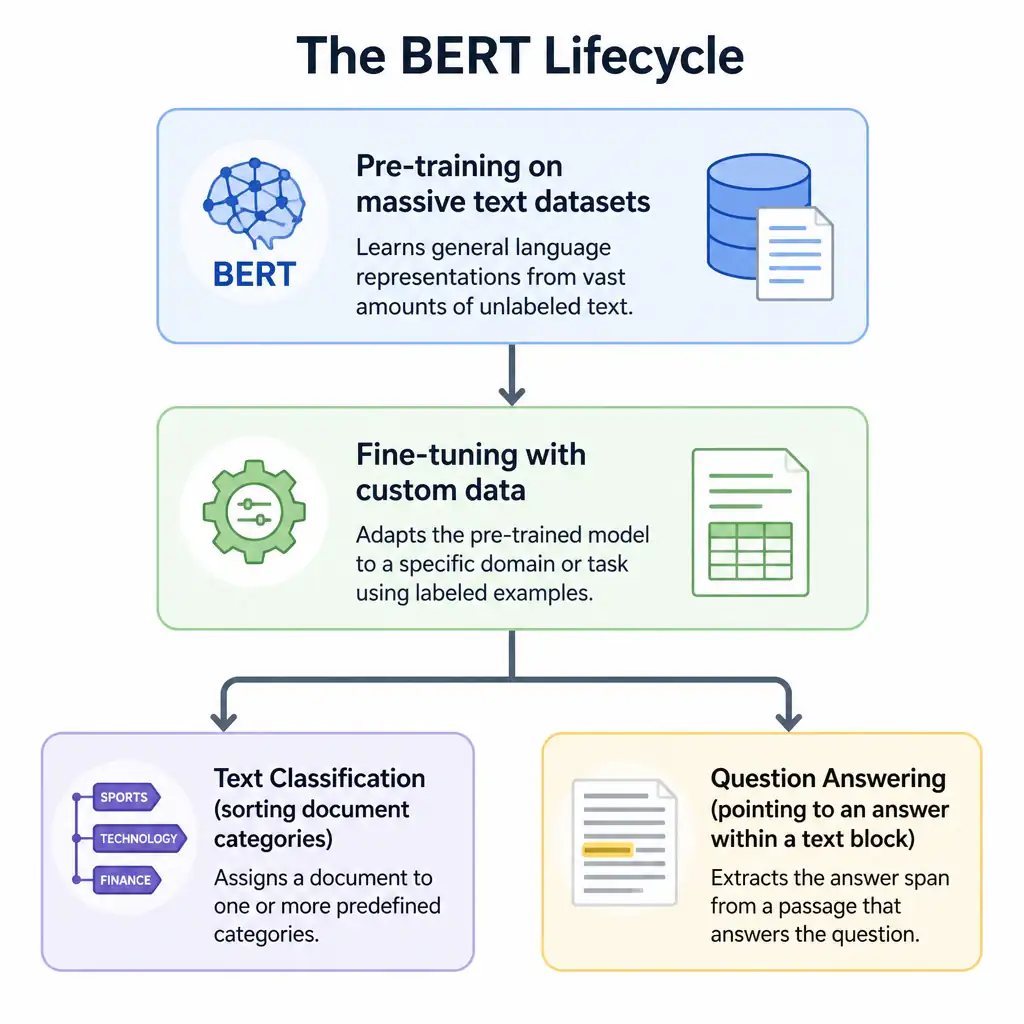
BERT is an absolute beast for understanding natural language, but it's a text model, period. You fine-tune it for text tasks like classification and question answering, not for images, numerical forecasting, or clustering customers.
Full Explanation
BERT (Bidirectional Encoder Representations from Transformers) is a pre-trained language model developed by Google. It is pre-trained on massive text datasets (specifically Wikipedia and BookCorpus) using unsupervised tasks like Masked Language Modeling (MLM) and Next Sentence Prediction (NSP). This pre-training enables the model to acquire a rich, context-aware understanding of human language syntax, grammar, and semantics.
To solve specific real-world problems, developers perform fine-tuning. This involves taking the pre-trained BERT model, adding a relatively simple, task-specific output layer (such as a classification head), and training the entire network on a labeled dataset for a few epochs. Fine-tuning allows the model to adapt its broad linguistic knowledge to targeted tasks with minimal training data and computation. BERT is highly effective for tasks that require deep text comprehension, including text classification (e.g., sentiment analysis, spam detection, topic categorization), question answering (determining where an answer lies within a text passage), named entity recognition (NER), and sentence similarity tasks.
The text classification and question answering set is correct because both tasks rely on deep text comprehension and can be adapted from BERT's pre-trained language understanding through fine-tuning.
The image classification and visual object detection set is incorrect because those are Computer Vision tasks. While Vision Transformers (ViTs) exist, BERT is strictly designed for textual input and cannot process raw images.
The time series forecasting and numerical regression set is incorrect because those tasks involve predicting continuous numerical sequences or values, typically handled by LSTMs, GRUs, or autoregressive statistical models rather than a language model built for text comprehension.
The customer segmentation and unsupervised clustering set is incorrect because customer segmentation is an unsupervised tabular data clustering task (typically solved using algorithms like K-Means or hierarchical clustering), which is completely unrelated to natural language understanding.