
During the initial preprocessing phase of a natural language processing project, a developer performs tokenization. What does this process actually do to the raw input text?
Select an answer to reveal the explanation.
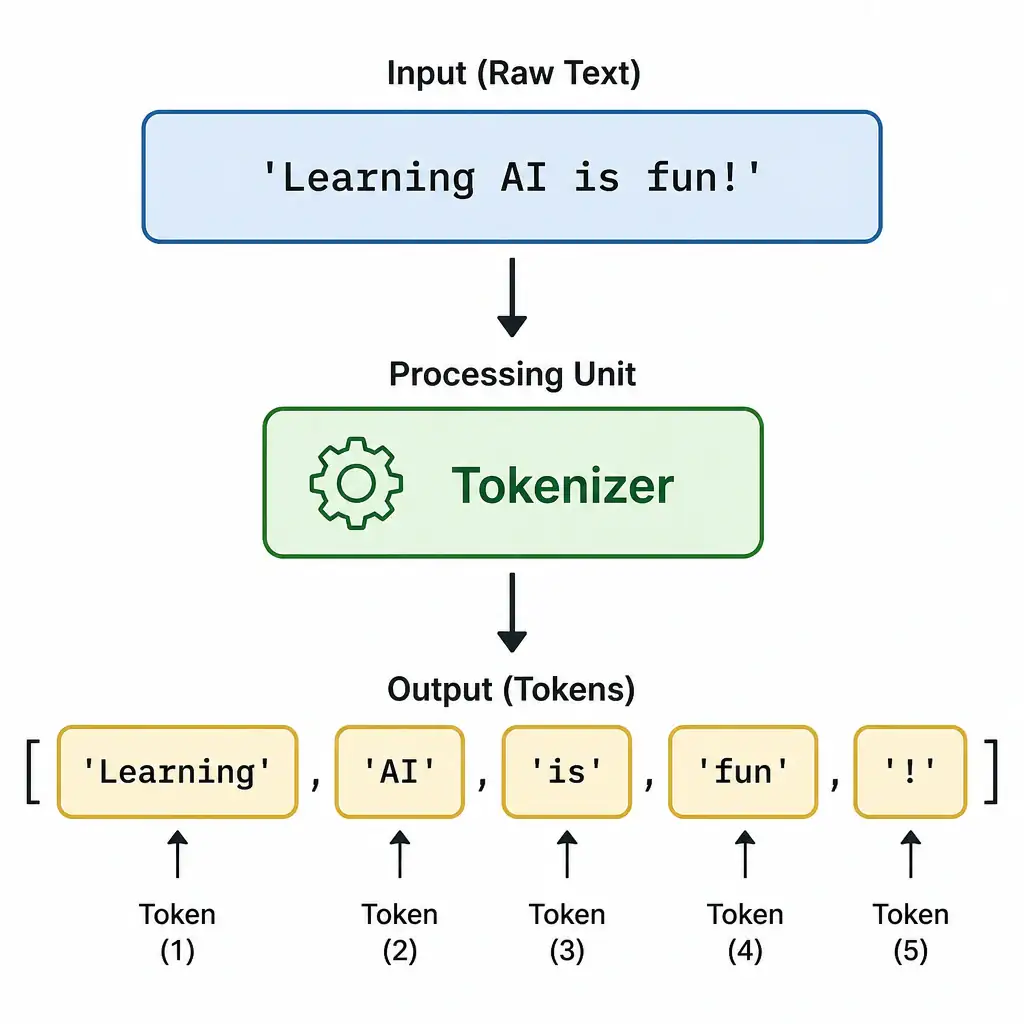
Short Explanation
Before a machine can make sense of a sentence, you have to break it down into bite-sized pieces it can digest. Tokenization slices raw text into words, subwords, or characters, and without it your model won't know where one word ends and the next begins. Don't confuse it with stop-word removal, stemming or lemmatization, or TF-IDF.
Full Explanation
Tokenization is the foundational preprocessing step in natural language processing (NLP). It involves taking a continuous string of raw text and segmenting it into smaller, discrete units called tokens. These tokens serve as the basic building blocks that a machine learning model can analyze. Depending on the chosen tokenizer, text can be split at the word level (e.g., separating by spaces and punctuation), the character level (treating each letter as a token), or the subword level.
Modern language models, such as BERT and GPT, rely heavily on subword tokenization (using algorithms like WordPiece or Byte-Pair Encoding). Subword tokenization splits rare or complex words into smaller, frequently occurring pieces (for example, 'unhelpful' might become 'un', 'help', and 'ful'). This technique is highly effective because it allows the model to handle out-of-vocabulary words and keep its vocabulary size manageable while still capturing morphological meaning. Without tokenization, raw text remains an unstructured sequence of characters, making it impossible for neural networks to assign numerical embeddings to individual linguistic concepts.
Understanding the incorrect descriptions is critical: - The description about removing common, low-value words like articles and prepositions to reduce vocabulary size describes stop-word removal, which is a filtering step that deletes words like 'and', 'the', or 'in' to clean up text, but it is not tokenization. - The description about mapping words to their canonical root or dictionary base form to handle grammatical variations describes lemmatization or stemming, which are normalization techniques that resolve inflected word forms back to their base or root representations. - The description about calculating term frequency-inverse document frequency weights to represent words numerically describes TF-IDF vectorization, which is a mathematical feature extraction method used to represent documents as numerical vectors based on word frequencies across a corpus.