
A data scientist is preprocessing a text corpus using the Natural Language Toolkit (NLTK) in Python. They need to reduce inflected word forms (like "running", "runs", and "ran") to their base dictionary form. Which NLTK module should they import?
Select an answer to reveal the explanation.
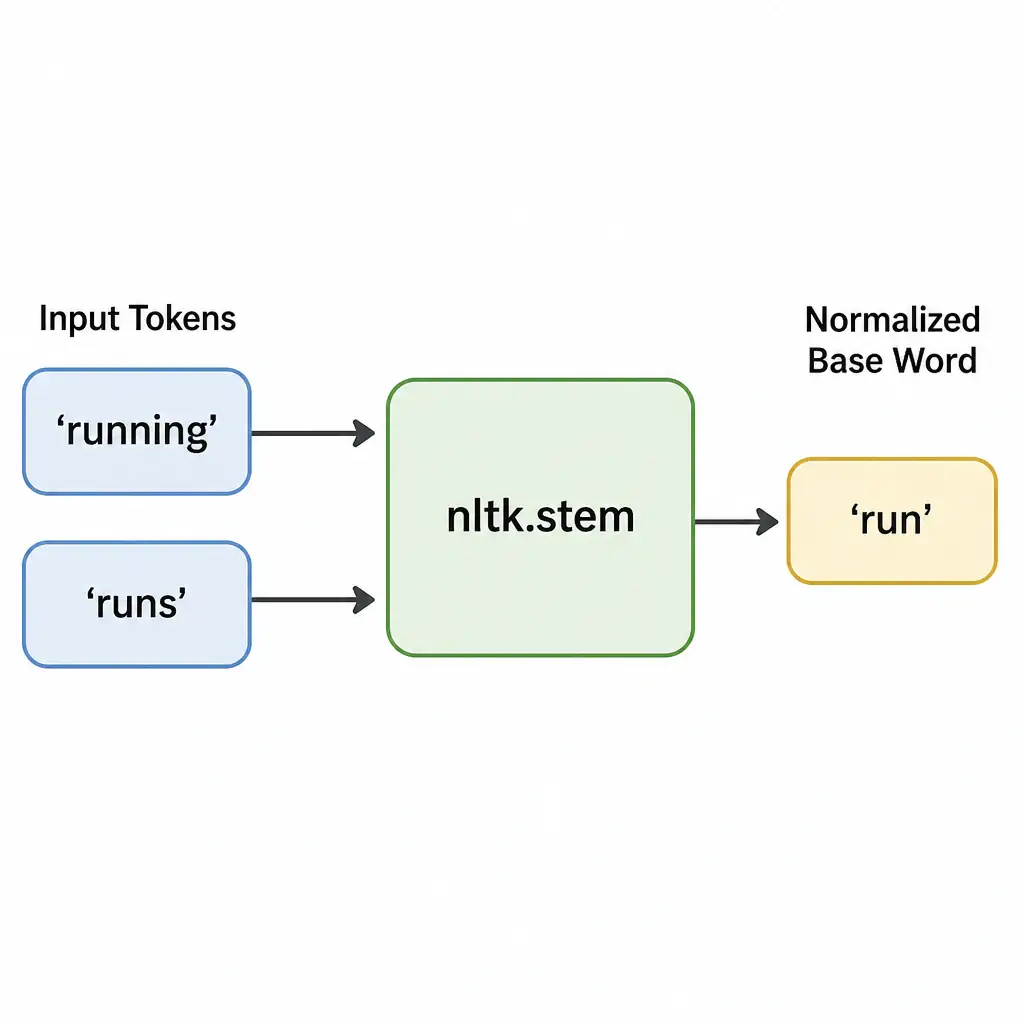
Short Explanation
Think of it like this: if you're searching for 'organize', you also want hits for 'organizes', 'organized', and 'organizing'. You need to strip prefixes and suffixes to get the core root word, and NLTK does that with the stem module. Don't confuse it with tokenizing or POS tagging; getting preprocessing right is half the battle.
Full Explanation
In NLP, inflected forms of words are normalized to a common base form to reduce vocabulary dimensionality and improve matching. This is done via stemming, which removes endings heuristically, or lemmatization, which uses morphological analysis and vocabulary to find the dictionary form, or lemma.
The correct choice is the NLTK module for stemming and lemmatization: nltk.stem. This module contains classes and functions for both stemming, such as PorterStemmer and SnowballStemmer, and lemmatization, such as WordNetLemmatizer.
The nltk.tokenize module is incorrect because it is used to split continuous strings of text into individual units or tokens, such as words, sentences, or characters, not to reduce them to their base form.
The nltk.tag module is incorrect because it is used for Part-of-Speech tagging, which labels words with their grammatical category, such as noun or verb, based on context.
The nltk.corpus module is incorrect because it provides interfaces to read-only corpora and lexical resources, such as the Brown Corpus or WordNet database files, but it does not contain the stemmer or lemmatizer processing classes.