
If you attempt to use a standard feedforward neural network (FNN) to process sequential data, such as natural language text or sensor telemetry over time, which fundamental architectural limitation will you encounter?
Select an answer to reveal the explanation.
Short Explanation
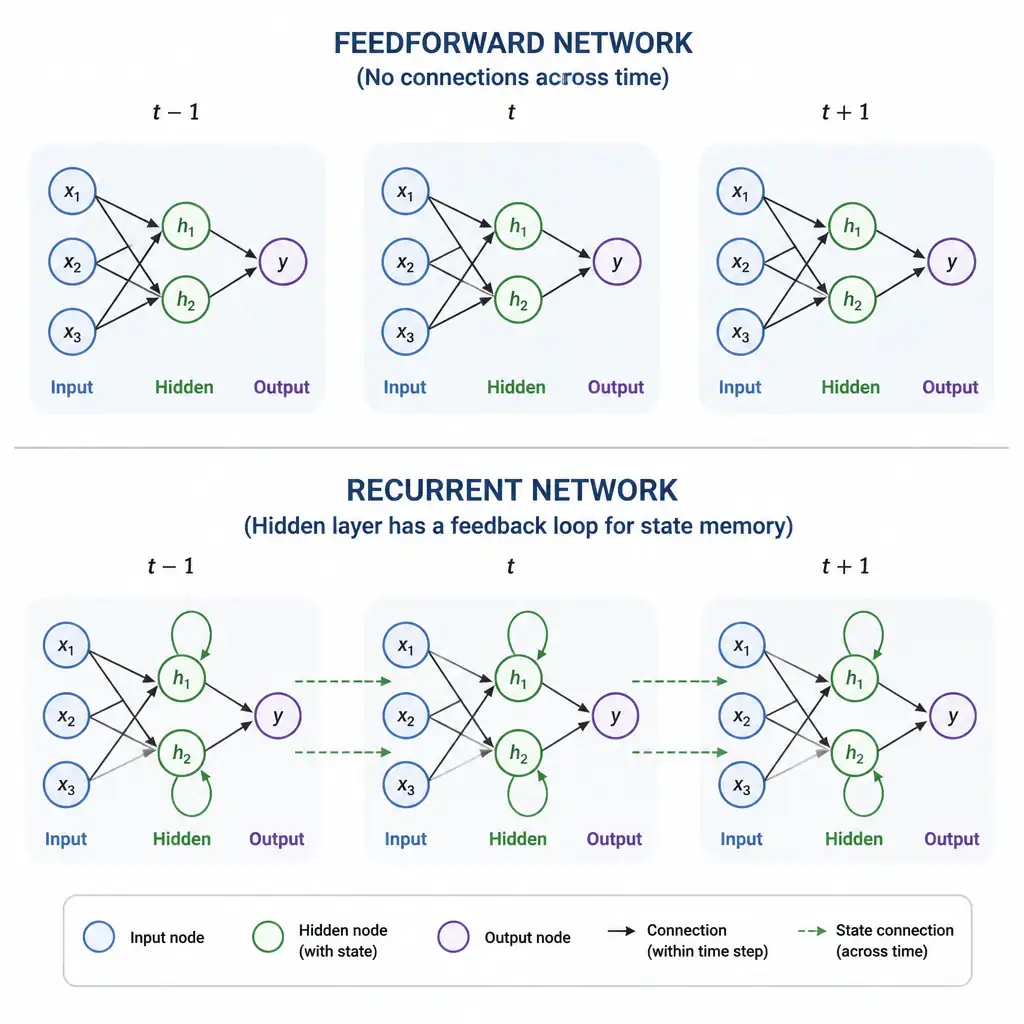
Imagine you're reading a book but forgetting every word as soon as you read it. Standard feedforward networks do that with sequences: they have no memory, no feedback loops, and no sense of order, so they can't track temporal dependencies. Trust me, that's why you need recurrent networks, long short-term memory networks, or Transformers when sequence order matters.
Full Explanation
Standard feedforward neural networks, such as multilayer perceptrons, process inputs in one direction—from the input layer, through hidden layers, directly to the output layer. One key assumption of feedforward architectures is that all inputs are independent of one another. When dealing with sequential data, such as speech, text, time series, or video, the order of the inputs is crucial to understanding their meaning. In natural language processing, the word 'not' changes the entire context of the words that follow it. Because a standard feedforward network has no internal memory or feedback loops, it processes each element of a sequence in isolation. It cannot retain information about prior inputs, meaning it has no concept of time or sequence order. The correct limitation is therefore that the network lacks recurrent connections or internal memory states to track temporal order and dependencies between sequence elements. To resolve this limitation, architectures with recurrent connections—recurrent neural networks, long short-term memory networks, and Transformers—were developed. These architectures maintain internal states, often called hidden states, that persist information across sequence steps, allowing them to capture temporal dependencies. The claim that feedforward networks are mathematically incapable of handling anything other than binary classification tasks is incorrect because feedforward networks can perform regression, multi-class classification, and structured outputs; they are not restricted to binary classification. The claim that computational complexity scales exponentially with sequence length, causing instant memory exhaustion, is incorrect because the computational complexity of a feedforward network is governed by its weights and layer sizes. While processing long sequences with a feedforward network requires flattening the input, which increases the input layer size, it does not scale exponentially or cause immediate memory failure. The claim that the network requires all input values to be non-zero, making sparse sequence data impossible to process, is incorrect because neural networks routinely process zero inputs; sparse data is handled fine by feedforward networks, though it may require specific optimization techniques.