
Generative Adversarial Networks (GANs) utilize a dual-network training dynamic (a generator and a discriminator). Which of the following tasks is a primary and common application of GANs?
Select an answer to reveal the explanation.
Short Explanation
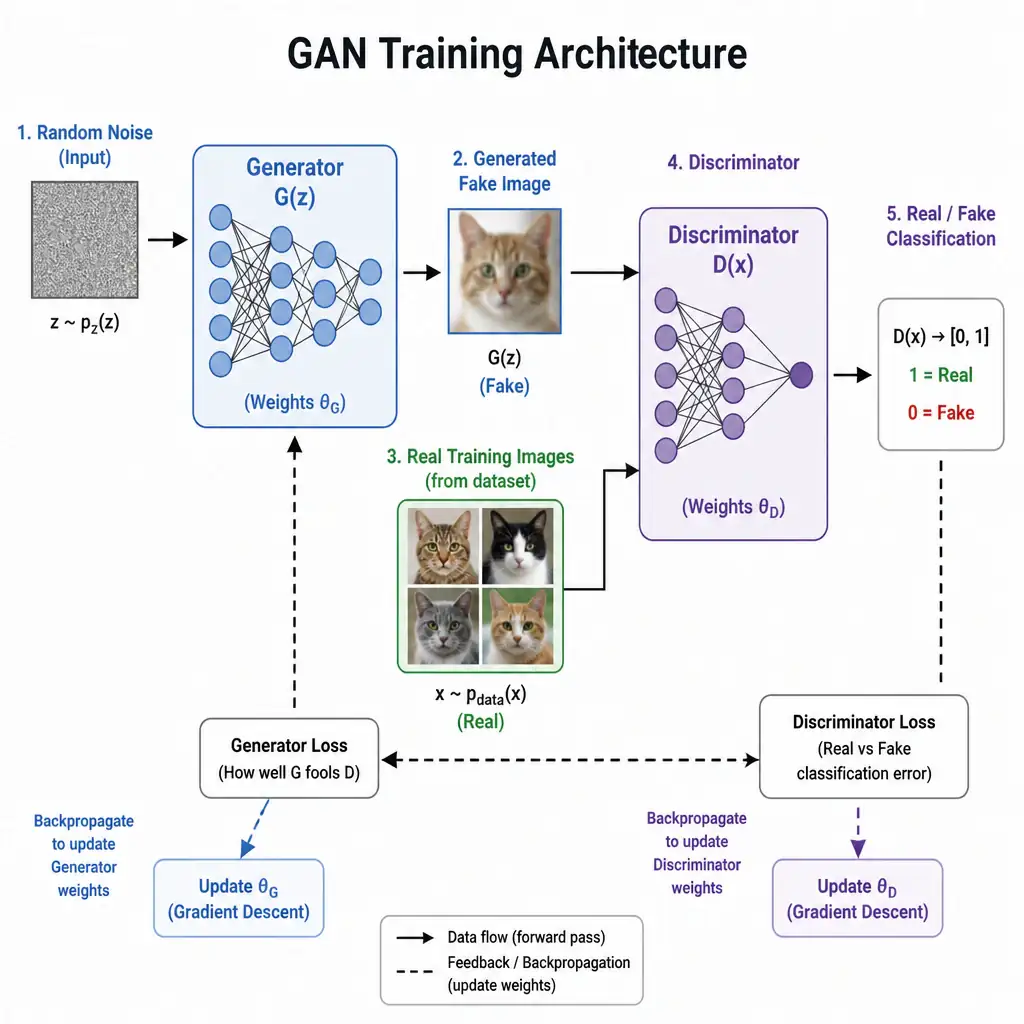
Think of a GAN like a master art forger and an art detective playing cat and mouse. The generator creates fake images, the discriminator tries to spot them, and both get better until the generator can produce realistic new images. That's why you use GANs for high-fidelity image synthesis and style transfer, not for sorting emails or forecasting stock prices.
Full Explanation
Generative Adversarial Networks (GANs) belong to the class of generative machine learning models. Introduced by Ian Goodfellow and colleagues in 2014, GANs are composed of two neural networks that compete against each other: - The Generator learns to create realistic data, such as synthetic images, starting from random noise. - The Discriminator learns to distinguish between real data from the training set and fake data produced by the generator.
Through this adversarial training process, both networks improve iteratively. The generator's objective is to maximize the probability of the discriminator making a mistake. Consequently, GANs are highly effective for tasks involving image generation, super-resolution, text-to-image synthesis, and style transfer, such as transforming a photo into the style of a painting. High-fidelity image synthesis and style transfer is therefore the primary and common application among the choices.
In practice, training GANs can be notoriously unstable, requiring careful tuning of hyperparameters to avoid issues like mode collapse, where the generator produces only a limited variety of outputs. Despite these challenges, their ability to synthesize novel and highly realistic high-dimensional data makes them the dominant choice for creative visual applications, whereas traditional models struggle to generate sharp, realistic images.
The other tasks are not primary GAN applications: - Unsupervised grouping of customers based on purchasing history is a typical application of clustering algorithms, such as K-Means or hierarchical clustering, not generative adversarial networks. - Predicting future stock market prices using historical time series data is generally addressed using recurrent neural networks, LSTMs, Transformers, or traditional statistical models like ARIMA. - Supervised binary classification of emails to detect spam is a classic supervised binary classification problem solved using algorithms like Naive Bayes, Support Vector Machines, or standard feedforward networks, not generative models.