
What is the primary difficulty encountered when training standard (vanilla) Recurrent Neural Networks (RNNs) on very long sequences?
Select an answer to reveal the explanation.
Short Explanation
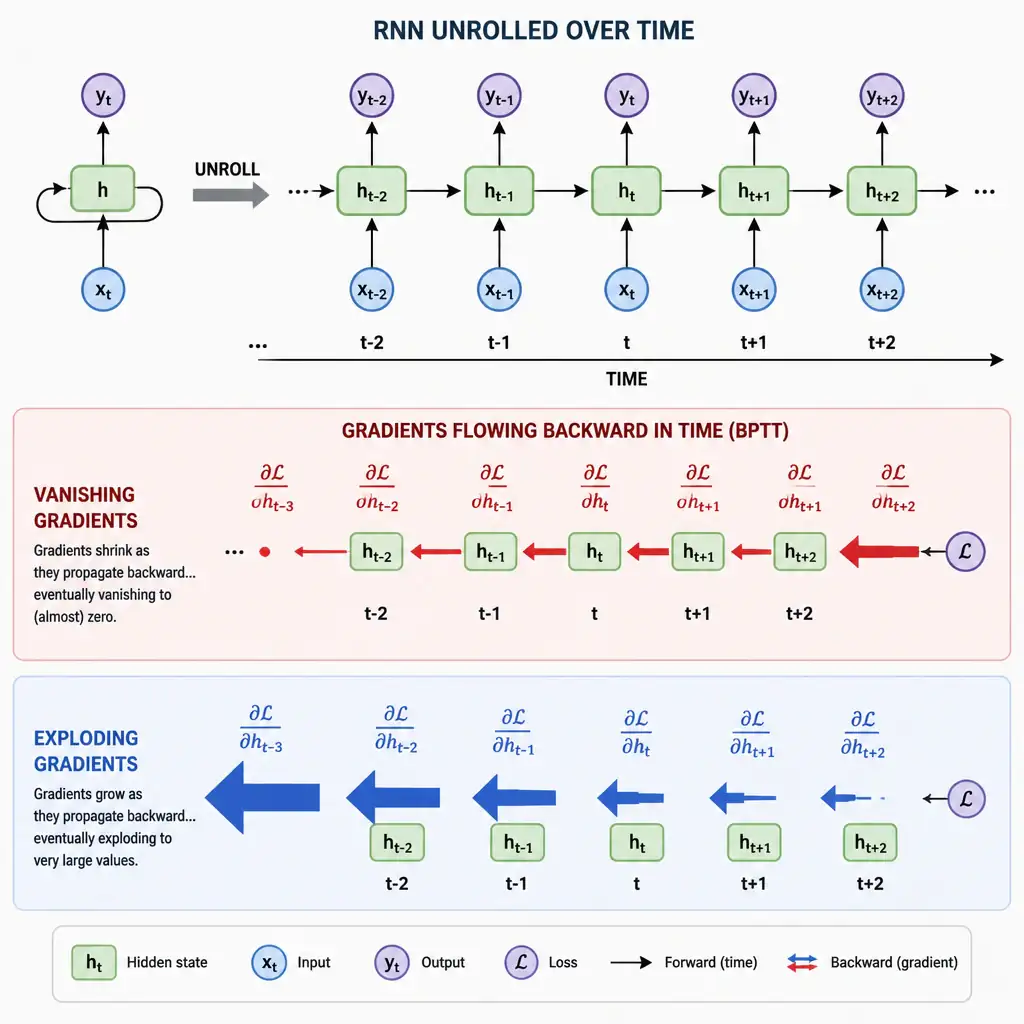
You hit the vanishing or exploding gradient problem when you train vanilla recurrent neural networks on very long sequences. Backpropagation through time multiplies tiny or huge gradients again and again, so the network either forgets early inputs or blows up. That's why you need long short-term memory networks, gated recurrent units, or Transformers.
Full Explanation
Vanilla recurrent neural networks process sequences token-by-token, passing a hidden state forward through time. While this architecture is theoretically capable of modeling sequential dependencies of arbitrary length, in practice, training standard recurrent neural networks on sequences longer than a few dozen steps is extremely difficult due to unstable gradients.
During the backward pass of backpropagation through time, the gradient of the loss at a given time step is calculated with respect to parameters at much earlier steps. This computation involves a product of Jacobian matrices, which are derivatives of the hidden state transition. If the eigenvalues of the weight matrices are less than one, the gradients decay exponentially as they propagate backward, leading to the vanishing gradient problem. The network fails to learn how early inputs affect late outputs. Conversely, if the eigenvalues are greater than one, the gradients grow exponentially, leading to the exploding gradient problem, which causes numerical instability, such as not-a-number values, and weight updates that are too large.
The option saying the computational complexity decreases too rapidly, causing the model to underfit, is incorrect because vanishing and exploding gradients make the model difficult to train, often resulting in underfitting, but not because the computation decreases too rapidly. The option saying the architecture is fundamentally unable to process sequential or time-series data is incorrect because recurrent neural networks are specifically designed for sequential data; they are just limited by sequence length in practice. The option saying the model requires an external memory buffer to store intermediate activations between epochs is incorrect. While sorting sequences by length, using padding or packing, is an optimization technique used to speed up training in frameworks like PyTorch, it is not a structural limitation of standard recurrent neural networks.