
What is a key advantage of using the Rectified Linear Unit (ReLU) activation function in the hidden layers of deep neural networks?
Select an answer to reveal the explanation.
Short Explanation
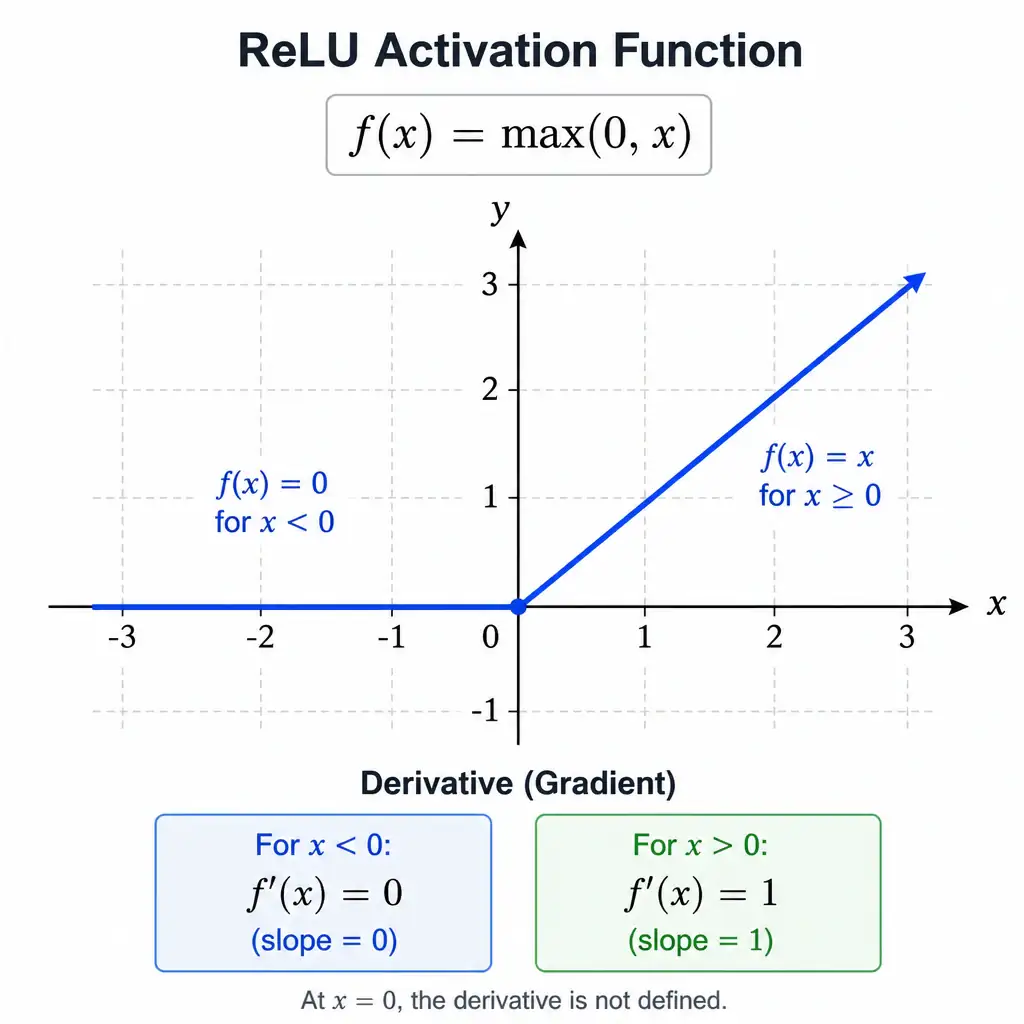
Check this out: you'll find ReLU is the undisputed champ of activation functions in hidden layers because it's incredibly fast to compute. The formula is just $f(x) = \max(0, x)$, so negative inputs become zero and positive inputs pass straight through. Since the derivative is exactly 1 for positive inputs, gradients don't shrink backward, which sidesteps vanishing gradients.
Full Explanation
The Rectified Linear Unit (ReLU) activation function, defined mathematically as $f(x) = \max(0, x)$, has become the standard activation function for the hidden layers of deep neural networks. Its widespread adoption is due to its computational efficiency and its ability to mitigate the vanishing gradient problem.
Unlike activation functions such as Sigmoid or Hyperbolic Tangent (Tanh), which require expensive exponential calculations, ReLU only requires a simple thresholding operation at zero. Furthermore, for any positive input ($x > 0$), the derivative of ReLU is constant and equal to 1. During backpropagation, this constant gradient of 1 propagates backward through the layers without being scaled down. This prevents the gradients from decaying exponentially (vanishing) as they travel to the initial layers of the network, enabling the training of much deeper architectures.
The description that constrains output values strictly between -1 and 1, ensuring stable numerical activations, describes the Hyperbolic Tangent (Tanh) activation function, which outputs values between -1 and 1. Tanh suffers from vanishing gradients when saturated.
The description that guarantees all neurons remain active by providing a small, non-zero slope for negative inputs describes the Leaky ReLU activation function, not the standard ReLU. Standard ReLU outputs a flat zero and a gradient of zero for all negative inputs, which can sometimes lead to 'dead neurons' (the dying ReLU problem) where neurons stop updating entirely.
The description that acts as a probability distribution generator when placed in the final output layer of classification networks describes the Softmax function, which converts logits into a probability distribution. Softmax is used in output layers, not hidden layers, and operates differently than ReLU.