
A machine learning engineer is evaluating a new named entity recognition (NER) model designed to identify medical terms in patient records. Since the dataset is highly imbalanced—with most words not being entities—the engineer wants to use a metric that balances both precision and recall. Which evaluation metric is most appropriate for this NLP task?
Select an answer to reveal the explanation.
Short Explanation
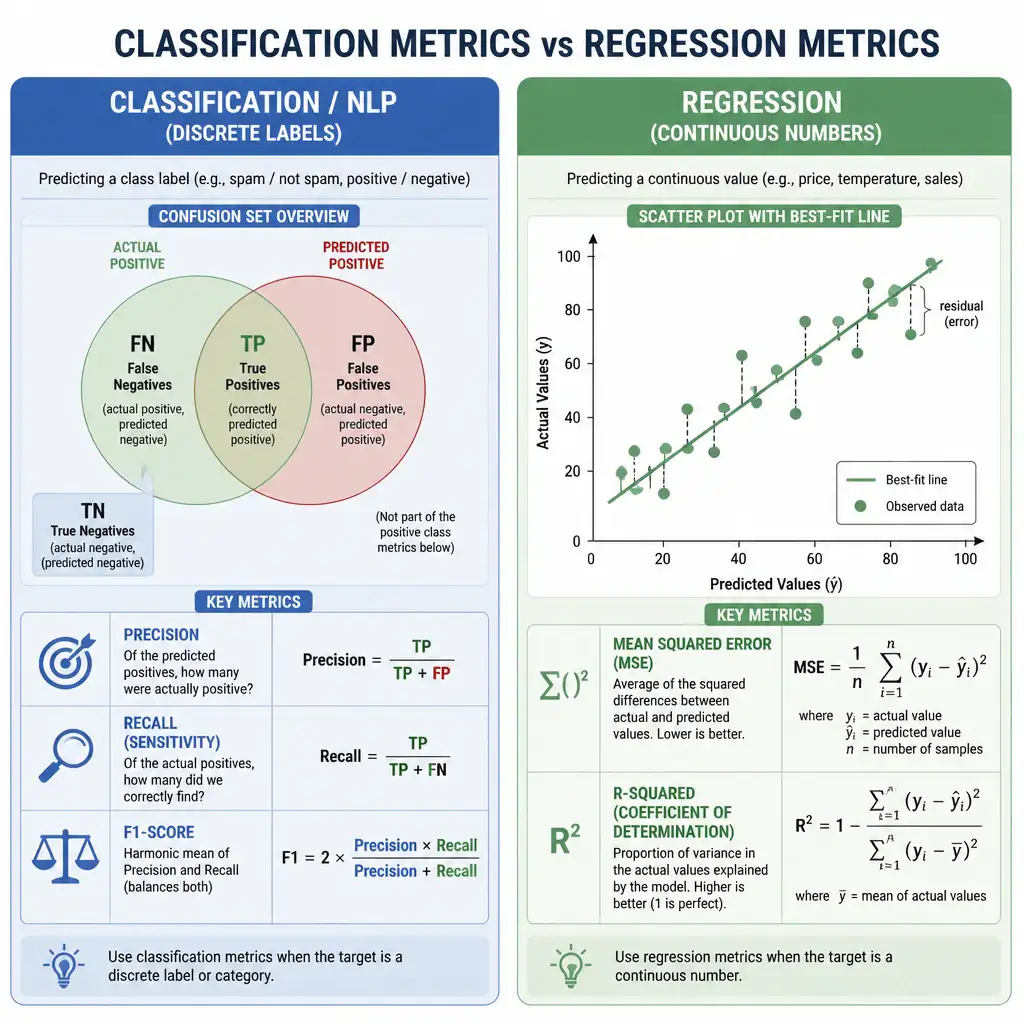
When you're evaluating NER on imbalanced medical records, you need a metric that balances precision and recall, and that's the F1-Score. It won't let a model look good just by ignoring rare entities. The other choices are regression metrics, not classification metrics.
Full Explanation
The correct answer is the F1-Score. In Natural Language Processing (NLP), tasks such as named entity recognition, spam detection, sentiment classification, and sequence labeling are structured as classification problems. These tasks frequently deal with highly imbalanced datasets where the negative class, such as non-entity tokens, vastly outnumbers the positive class. Standard metrics like accuracy can be highly misleading in these scenarios; a model that classifies everything as negative would achieve high accuracy but fail to identify any target entities. The F1-Score addresses this by computing the harmonic mean of precision and recall. Precision measures the ratio of true positive predictions to all positive predictions, ensuring the model does not produce excessive false alarms. Recall measures the ratio of true positives to all actual positives, ensuring the model does not miss critical targets. By balancing both metrics, the F1-Score provides a robust measurement of classification quality under class imbalance. The Mean Squared Error (MSE) choice is a regression metric that calculates the average of the squared differences between the predicted continuous outcomes and the actual target values. It is highly sensitive to outliers but is mathematically irrelevant for classification tasks. The Adjusted R-squared choice is also a regression metric that determines the proportion of variance in a dependent variable explained by independent variables in a regression model, adjusted for the number of predictors. It evaluates goodness-of-fit for linear models, not text classification. The Mean Absolute Error (MAE) choice measures the average of the absolute differences between predictions and actual values in regression. None of these regression metrics are capable of evaluating discrete prediction tasks in NLP, making the F1-Score the only suitable and standard metric among the choices.