
You are setting up a preprocessing pipeline for a transformer-based Large Language Model (LLM). What is the purpose of the initial "tokenization" step?
Select an answer to reveal the explanation.
Short Explanation
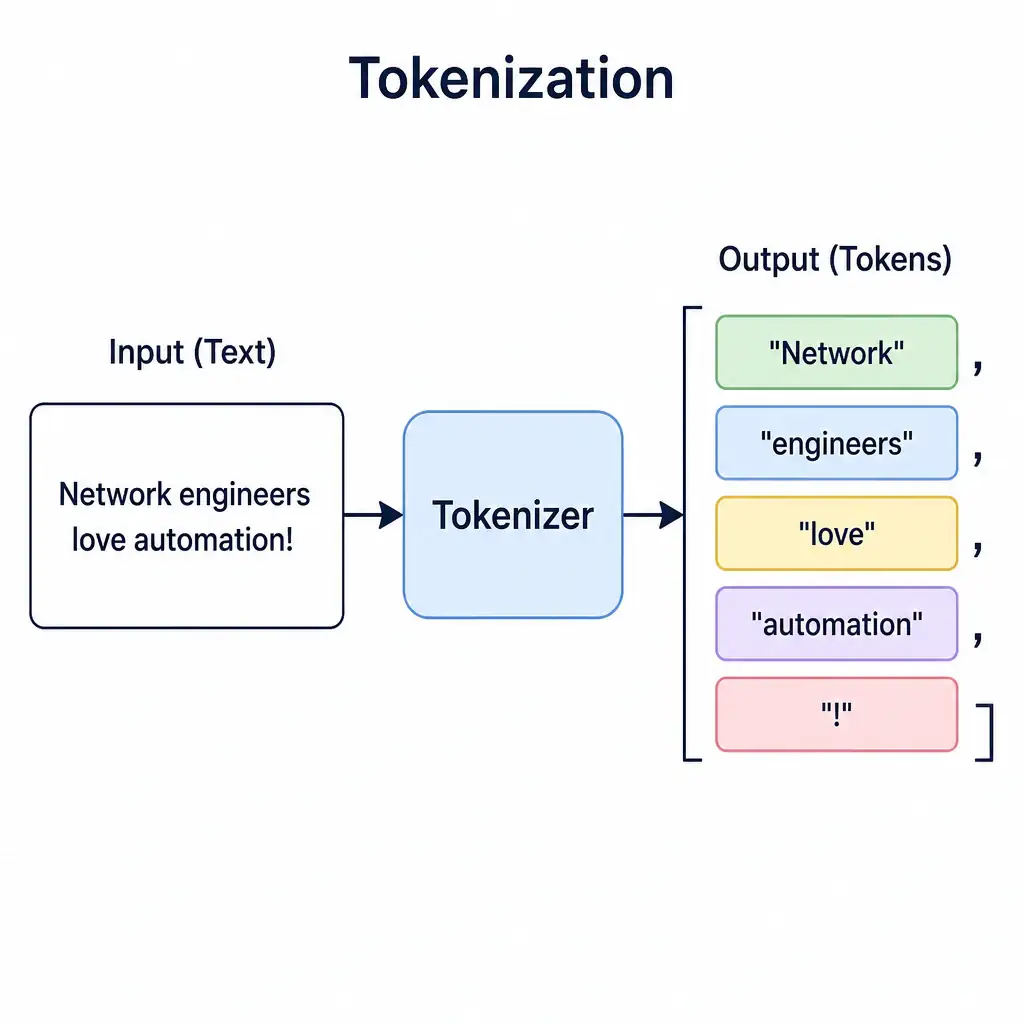
Before a computer can make heads or tails of a sentence, you have to break it down into smaller, bite-sized pieces. Tokenization slices raw text into tokens—words, subwords, or characters—so it's the first step in an NLP pipeline. Don't confuse it with embedding or cleaning.
Full Explanation
Tokenization is the foundational preprocessing step in Natural Language Processing (NLP). It is the process of splitting a continuous sequence of characters (a text string) into smaller, meaningful units called tokens. Depending on the design of the tokenizer, these tokens can be: - Words: Splitting text by whitespace and punctuation (e.g., "Let's go" -> ["Let", "'", "s", "go"]). - Subwords: Breaking words into common sub-components (e.g., "unbelievable" -> ["un", "believ", "able"]), which is highly effective for handling out-of-vocabulary words in modern models like BERT or GPT. - Characters: Slicing the text into individual letters or symbols.
Without tokenization, a model would treat an entire paragraph as a single, massive string, making text analysis impossible.
The filtering-out-common-words approach is incorrect because removing common, low-information words (like "the", "is", "at") is called stop word removal, which is a separate text cleaning step. The converting-words-into-dense-high-dimensional-vectors approach is incorrect because converting text or tokens into numerical vector representations is known as word embedding or vectorization (e.g., Word2Vec, TF-IDF). The standardizing-text-by-lowercasing-and-correcting-spelling-errors approach is incorrect because correcting spelling mistakes is part of text cleaning, normalization, or spell-checking, not tokenization.