
You need to group unlabeled network flow data points into distinct, non-overlapping subsets based on numerical feature similarity. Which of the following algorithms is designed specifically to perform this unsupervised clustering task?
Select an answer to reveal the explanation.
Short Explanation
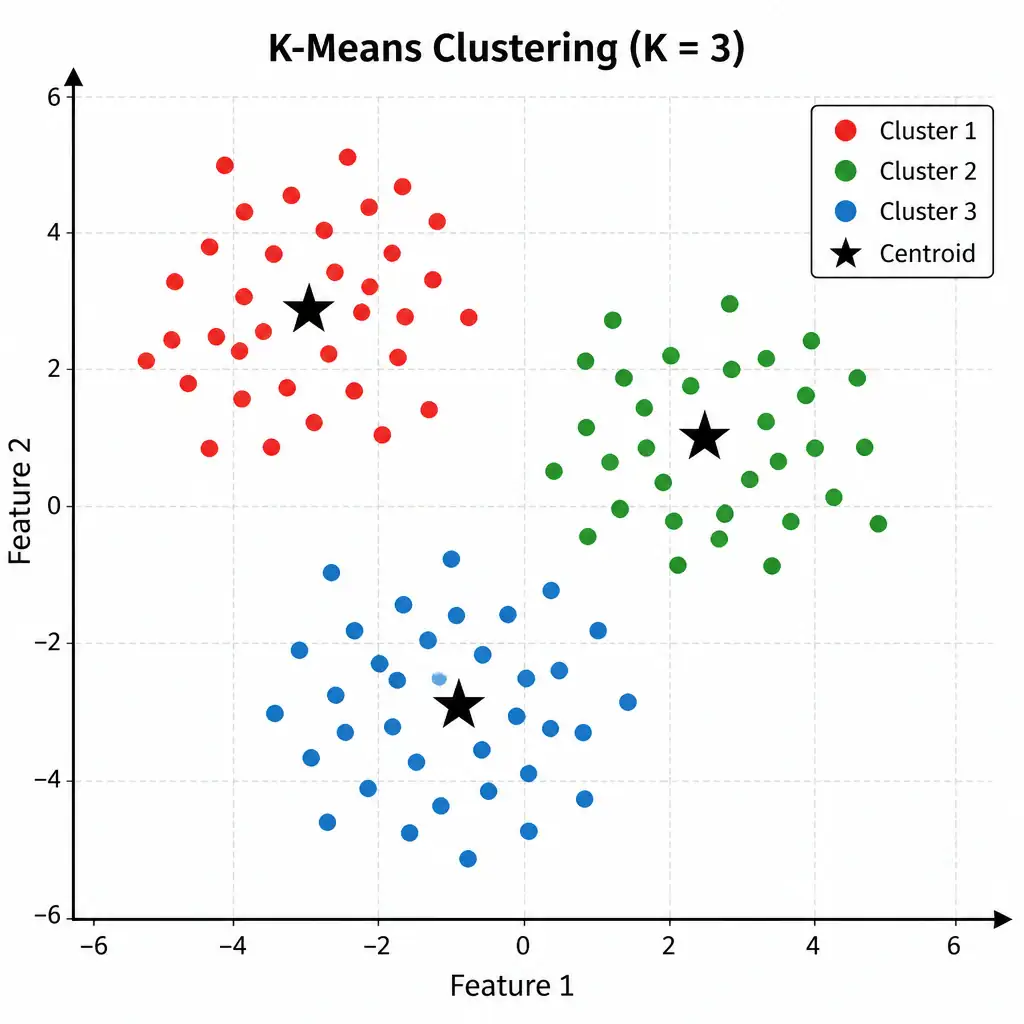
K-Means is your go-to for unsupervised clustering. It drops K centroids into unlabeled network flow data and groups points by feature similarity. KNN, SVM, and decision trees are supervised, so they don't fit this task.
Full Explanation
K-Means Clustering is one of the most popular and straightforward unsupervised learning algorithms used for clustering. The goal of K-Means is simple: group similar data points together to discover underlying patterns. It achieves this by partitioning n observations into K clusters, where each observation belongs to the cluster with the nearest mean, acting as a prototype or centroid of the cluster. For unlabeled network flow data grouped by numerical feature similarity into distinct, non-overlapping subsets, K-Means Clustering is the algorithm designed for the task. It is crucial to distinguish K-Means from supervised algorithms that have similar names or are used for classification. K-Means Clustering is unsupervised and groups unlabeled data points based on feature similarity, using Euclidean distance to centroids. The K-Nearest Neighbors option is incorrect because K-Nearest Neighbors is supervised and used for classification or regression; it classifies a new data point based on the majority vote of its K nearest labeled neighbors, not by forming unlabeled clusters. The Support Vector Machine option is incorrect because a Support Vector Machine is supervised and designed primarily for classification and regression by finding an optimal hyperplane that maximizes the margin between different classes. The Decision Tree classifier option is incorrect because a Decision Tree is supervised and builds a flowchart-like structure to predict a target class or continuous value, not to cluster unlabeled data.