
During the optimization process using gradient descent, what role does the hyperparameter known as the 'learning rate' play?
Select an answer to reveal the explanation.
Short Explanation
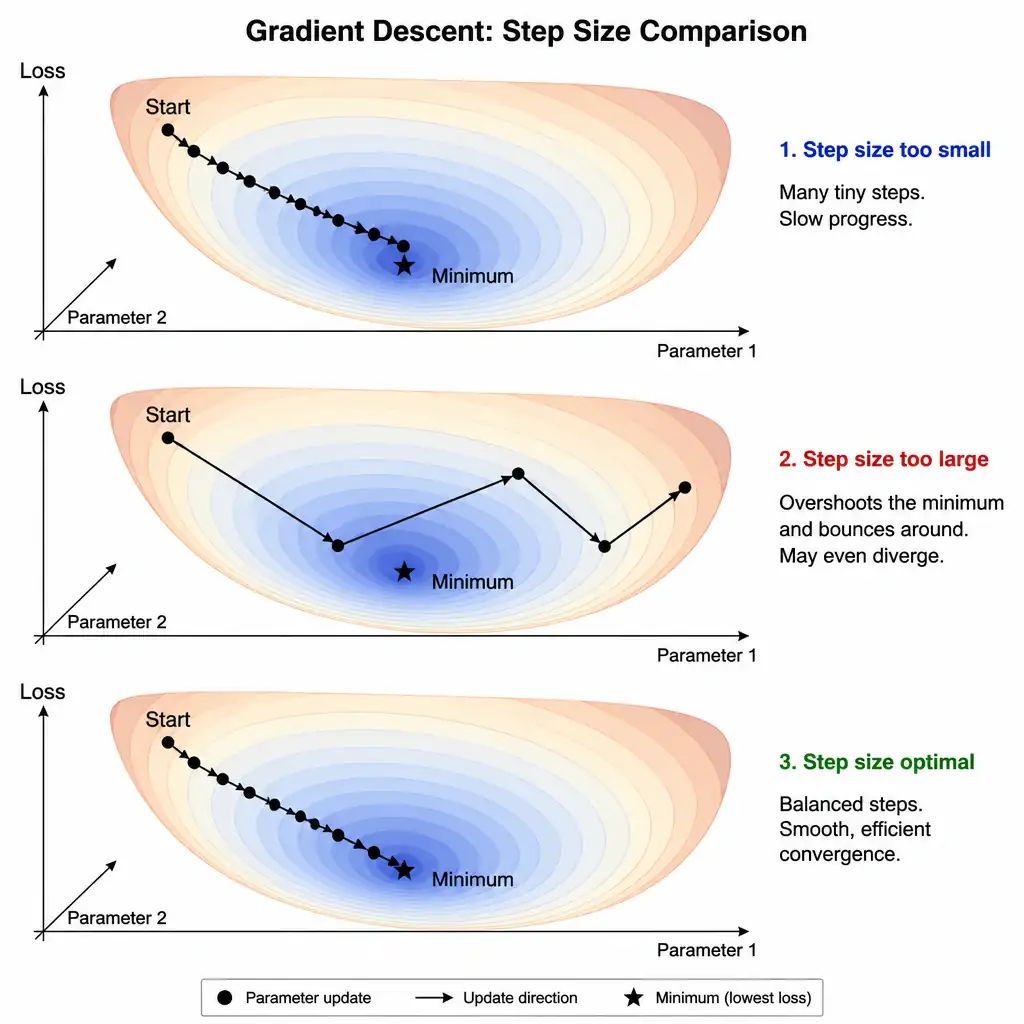
Think of the learning rate like the dial on your stove. If you turn it up too high, your weights overshoot and never settle; if you turn it too low, training crawls. It controls the size of each step your optimizer takes down the loss mountain toward a minimum.
Full Explanation
The statement defining the learning rate as the step size taken toward a local minimum of the loss function during weight updates is correct. The learning rate (often represented by Greek symbols such as eta or alpha) is a critical hyperparameter in training machine learning models using gradient descent or its variants (such as Adam or RMSprop). When a model processes a batch of data, it calculates the gradient of the loss function with respect to each weight. The gradient indicates the direction of steepest ascent (i.e., how to increase the error). To minimize the error, the optimizer updates the weights in the opposite direction. The learning rate determines the scale or 'step size' of this update: weight = weight - (learning_rate * gradient). If the learning rate is too large, the optimizer may overshoot the optimal minimum and potentially diverge, causing training loss to explode. If it is too small, the model will take excessively small steps, leading to slow training progress and risk of getting trapped in suboptimal local minima or saddle points. The statement specifying the exact number of epochs the training algorithm will run before stopping is wrong because epochs are a separate hyperparameter specifying how many passes the model makes over the entire dataset. The statement calculating the percentage accuracy of the model on the validation dataset is wrong because accuracy and similar evaluation metrics, such as F1-score, measure model performance rather than guiding optimization steps. The statement determining the total number of layers and neurons configured within a neural network is wrong because that describes model architecture (depth and width), which is configured before training and is independent of the learning rate. Finding the optimal learning rate often involves using techniques like learning rate schedules or learning rate finders.