
During the training phase of a deep neural network, you decide to implement a dropout rate of 0.3 on your hidden layers. What is the primary objective of this technique?
Select an answer to reveal the explanation.
Short Explanation
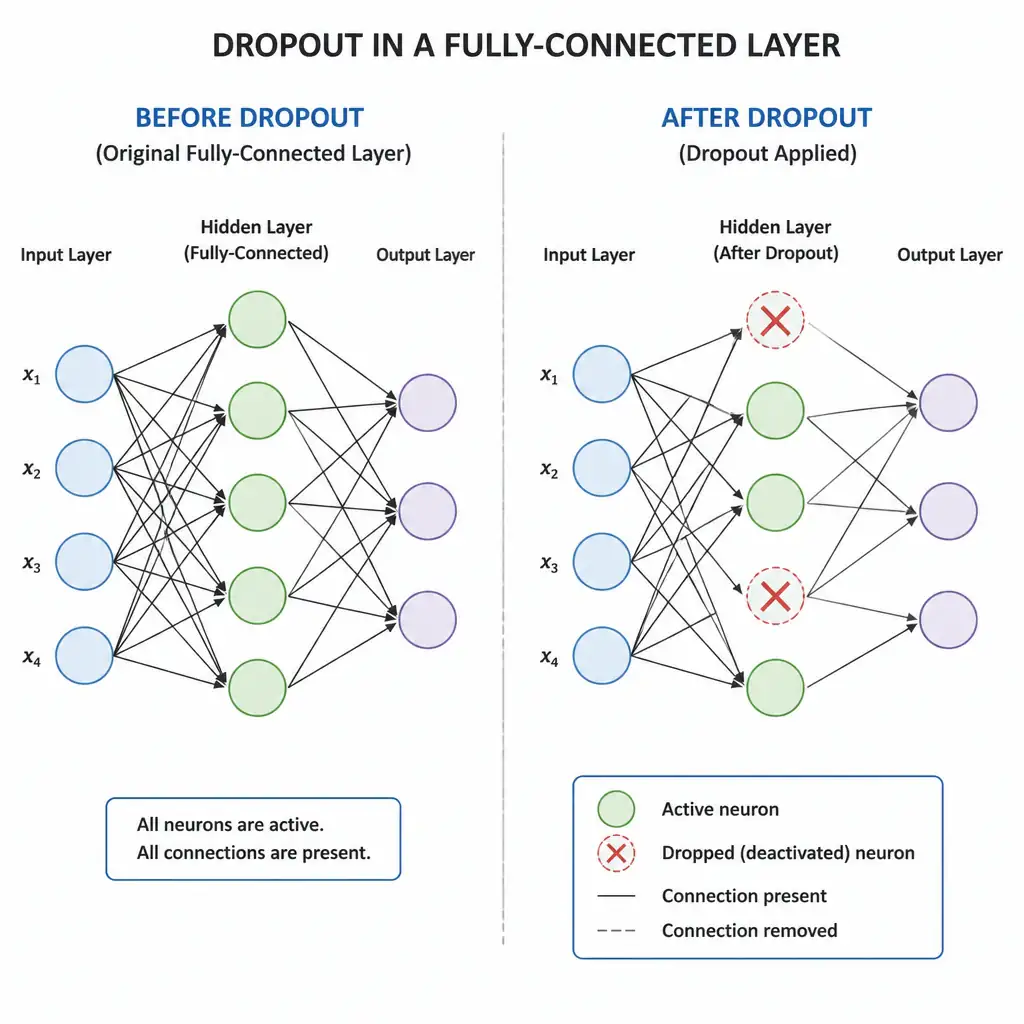
You use dropout to stop a few neurons from doing all the work. By randomly deactivating 30% of hidden-layer neurons each training step, you force the network to spread learning across more neurons, which reduces overfitting. That keeps the model from memorizing the training set.
Full Explanation
Dropout is a widely used regularization technique for deep neural networks. During training, at each gradient update step, dropout randomly 'drops out' (deactivates) a specified percentage of neurons (nodes) in the network's layers along with their incoming and outgoing connections. The selection of deactivated nodes changes at every training iteration.
This mechanism prevents neurons from co-adapting too closely. Co-adaptation occurs when some neurons rely on the specific outputs of other neurons to correct their errors, which leads to overfitting on the training data. By forcing the network to learn redundant representations with different subsets of active neurons, dropout improves the model's ability to generalize to new, unseen datasets. During inference (testing/prediction), dropout is turned off, and all neurons are active, with their weights scaled by the dropout probability to account for the lack of dropped nodes.
The correct objective is therefore to mitigate overfitting by randomly deactivating a subset of neurons during each training step.
The claim that dropout permanently compresses the neural network's architecture to make it run faster on edge devices is incorrect because dropout does not permanently change the structure or size of the model; the full network is preserved and utilized during inference. The claim that dropout dynamically accelerates training iterations by ignoring low-weight connections is incorrect because dropout does not select connections by weight magnitude; it randomly deactivates neurons, and it actually tends to increase the total number of training epochs required to converge, even though it reduces the computation per epoch slightly. The claim that dropout increases the learning rate of the optimizer when loss reduction begins to stall is incorrect because dropout is a regularization method and is unrelated to adjusting the optimizer's learning rate.