
Imagine you have just trained a machine learning model, and it achieves a remarkable 99.8% accuracy on your training dataset. However, when you deploy this model to production and feed it fresh, real-world data, the accuracy drops to 52%. What phenomenon is your model experiencing?
Select an answer to reveal the explanation.
Short Explanation
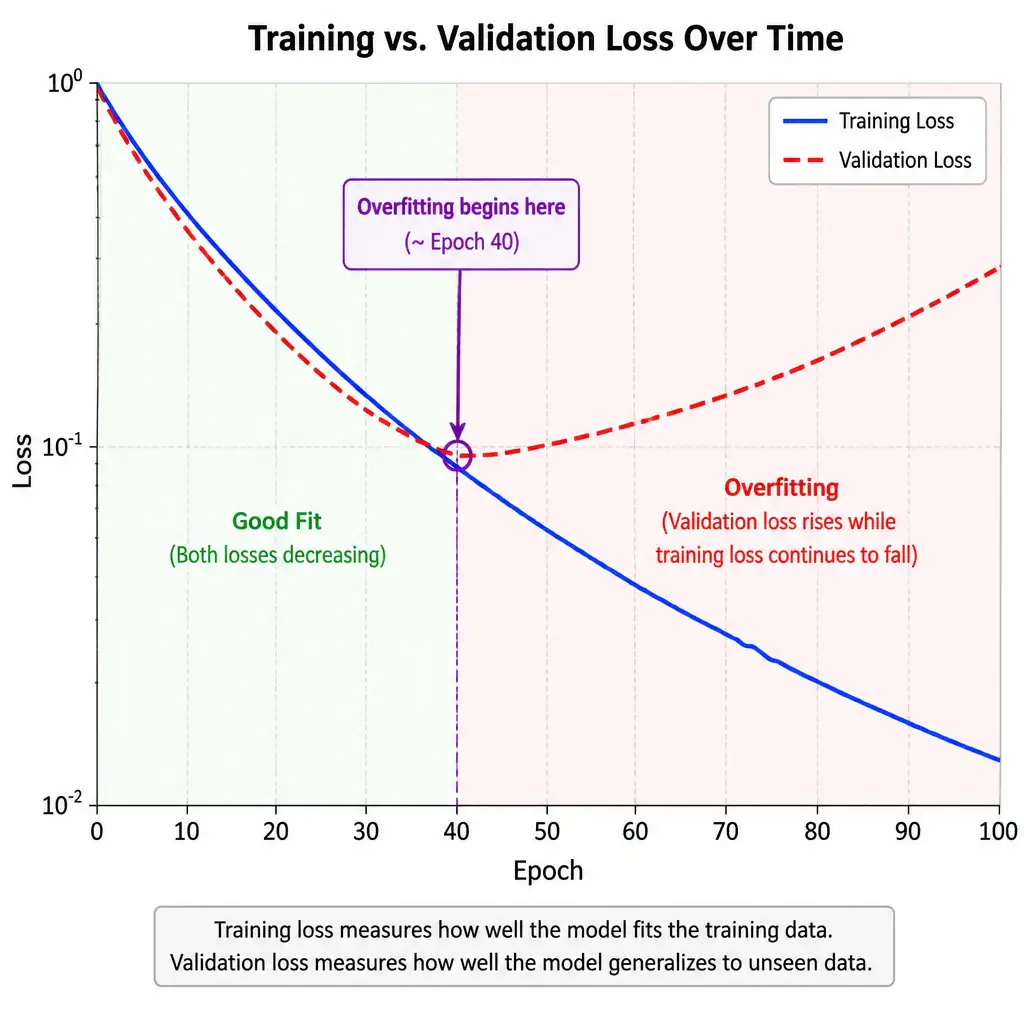
Here's the deal: your model is overfitting because it memorized the training data's noise instead of learning patterns that generalize. You saw 99.8% in training, but real-world data exposed that it wasn't actually learning. You want a model that generalizes, not one that just copies what it already saw.
Full Explanation
Overfitting is a fundamental challenge in supervised machine learning where a model learns the training dataset too well. Specifically, it captures the noise, outliers, and random fluctuations in the training data rather than the underlying mathematical function that describes the relationship between the features and the target. As a result, while the training loss is extremely low and accuracy is exceptionally high, the model generalizes poorly to unseen validation or test datasets. That is exactly what happens when accuracy is 99.8% on training data but drops to 52% on fresh production data.
To understand the other choices: the underfitting option describes the opposite problem, where the model is too simple to capture the trend in the training data. The high-bias option is another term related to underfitting; a model with high bias makes restrictive assumptions and cannot capture complex patterns, leading to poor performance on both training and test data. The data-leakage option describes a data preparation error where target information from the validation or test set is inadvertently mixed into the training set, causing inflated performance metrics during development but failure in production.
To mitigate overfitting, practitioners use techniques such as cross-validation, regularization (L1/L2), pruning (in decision trees), dropout (in neural networks), or simply gathering more training data.