
A clinic wants to implement an AI system that analyzes chest X-ray scans to automatically flag potential cases of pneumonia. Given that the input data consists of 2D pixel grids with local spatial relationships, which neural network architecture is best suited for this task?
Select an answer to reveal the explanation.
Short Explanation
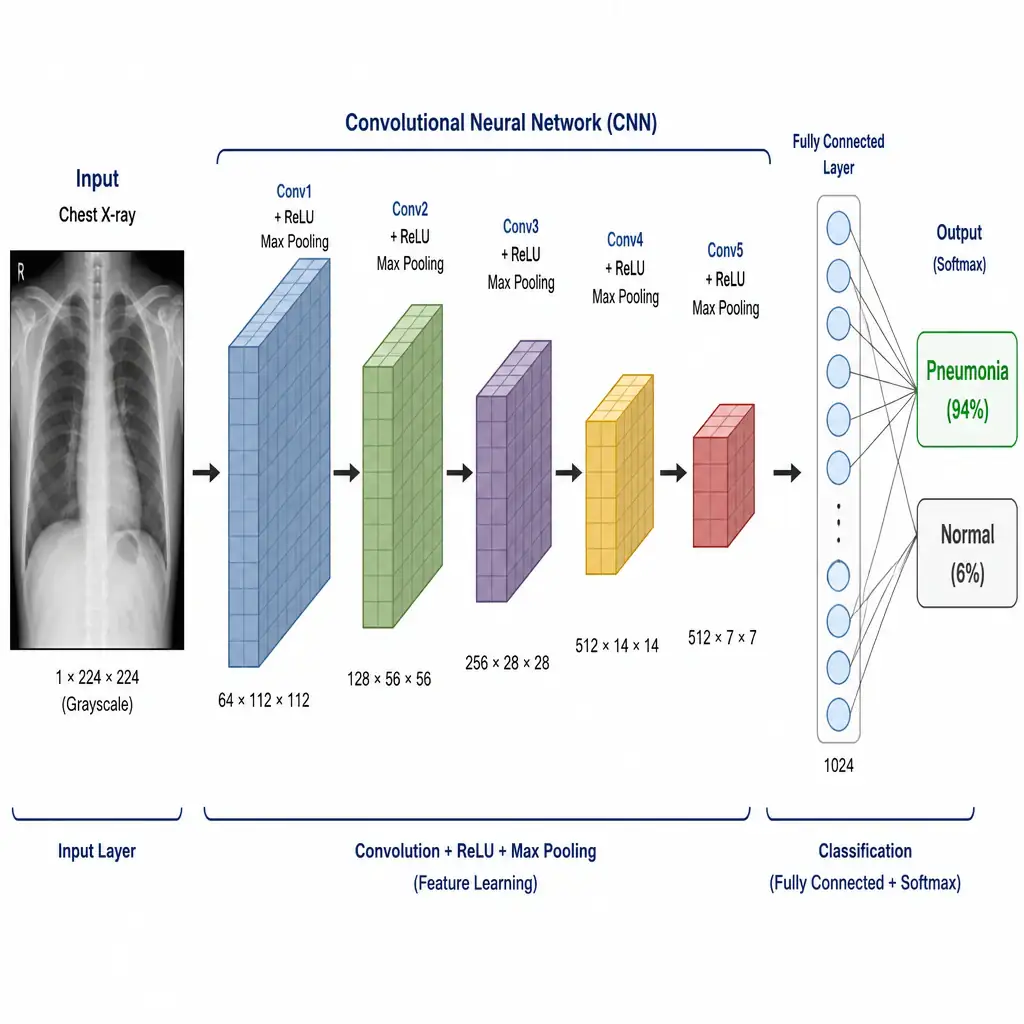
Here's the deal—if you're dealing with images, you should immediately think of Convolutional Neural Networks (CNNs). They slide filters over pixel grids to catch local spatial patterns like edges and shapes, which is exactly what you need to flag pneumonia in chest X-rays. RNNs and Transformers are great for sequences, but CNNs rule the image world.
Full Explanation
Convolutional Neural Networks (CNNs) are specialized deep learning architectures designed to process grid-like topology data, most notably 2D images. CNNs are highly effective for computer vision tasks such as image classification, object detection, and image segmentation.
The key advantage of CNNs lies in their use of convolutional layers. In these layers, a set of learnable filters (kernels) slides (convolves) across the spatial dimensions of the input image. This operation enforces three important principles: 1. Sparse Connectivity: Each neuron in a convolutional layer is connected only to a local region of the input volume (its receptive field), rather than to every single pixel. This drastically reduces the parameter count compared to fully connected networks. 2. Parameter Sharing: The same filter weights are applied across the entire image. If a filter learns to detect a horizontal edge in one corner of an image, it can detect the same edge in any other part of the image. 3. Spatial Hierarchies: CNNs automatically build hierarchical representations, learning low-level edge features in early layers, which are combined into mid-level shapes and high-level object representations in deeper layers.
Let's review the incorrect architectures: - Recurrent Neural Networks (RNNs) are designed to process sequential data, such as time-series or text, by maintaining internal memory states, but they are not optimized for processing 2D grid structures. - Transformers use self-attention mechanisms to weigh relationships between all tokens in a sequence, and while they can be adapted for vision (Vision Transformers), standard CNNs remain the classic baseline architecture for spatial classification. - Generative Pre-trained Transformers (GPT) are specialized models designed for natural language generation and sequence prediction.
Therefore, the Convolutional Neural Network is the most suitable architecture for image-based diagnostics.