
During the training of a deep neural network, after the input has passed forward through the layers and the prediction error has been calculated, how does the network determine exactly how to adjust the millions of weights and biases inside its hidden layers to reduce that error?
Select an answer to reveal the explanation.
Short Explanation
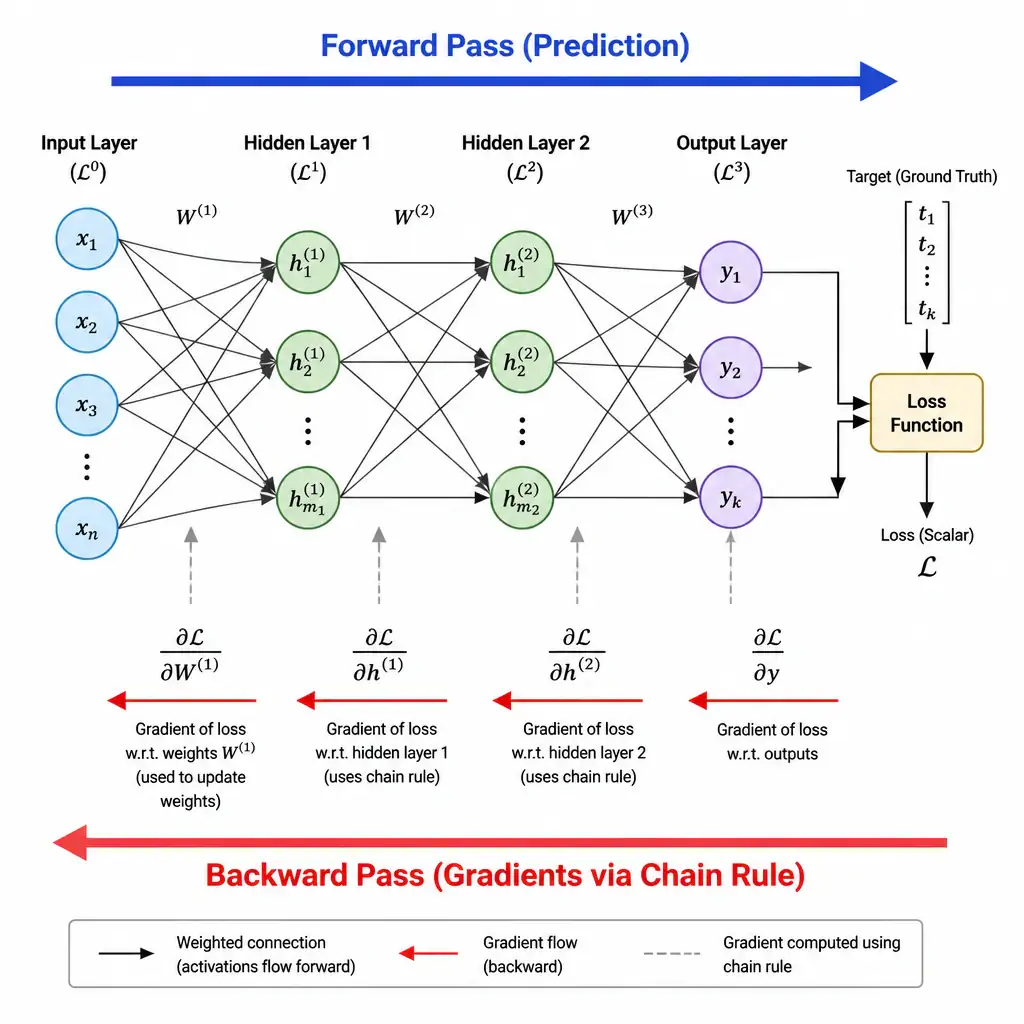
Here's the deal—backpropagation is where the network learns. It starts at the error and works backward, using the chain rule to figure out how each weight and bias contributed. Then the optimizer nudges them to reduce the loss.
Full Explanation
Backpropagation, short for 'backward propagation of errors,' is the core algorithm used to train artificial neural networks. It is a supervised learning method that works in conjunction with an optimization algorithm, such as Gradient Descent, to minimize the network's loss.
The training loop of a neural network consists of three main steps: 1. Forward Pass: Input data is fed forward through the network. Each layer applies weights, biases, and activation functions, culminating in a prediction at the output layer. 2. Loss Calculation: The output prediction is compared against the actual target value using a loss function, yielding a scalar error value. 3. Backward Pass, or Backpropagation: The algorithm calculates the partial derivatives, also called gradients, of the loss function with respect to every weight and bias in the network. Starting from the output layer, it uses the calculus chain rule to recursively compute gradients for each preceding hidden layer.
Once the gradients are calculated via backpropagation, the optimizer uses them to update the weights and biases, for example by subtracting a fraction of the gradient scaled by the learning rate. This process is repeated across many epochs, gradually minimizing the error.
The choice describing forward propagation is wrong because forward propagation only computes the intermediate activations and output predictions; it does not calculate gradients or update weights, even though the wording claims it updates parameters.
The choice describing weight initialization is wrong because weight initialization is a one-time setup step performed before training begins to prevent issues like vanishing or exploding gradients. It does not determine how to adjust millions of weights and biases after an error has been calculated.
The choice describing hyperparameter tuning is wrong because hyperparameter tuning is an external process of selecting structural settings, such as learning rate or number of layers, and it does not calculate gradients or update weights during normal backpropagation iterations.
Therefore, backpropagation is the process of calculating gradients to update weights and biases.