
You are training a convolutional neural network to classify different species of birds, but you only have 200 images of each species. To prevent the model from overfitting and to help it generalize to new, unseen photos, you want to artificially increase the size of your training set without taking new pictures. What technique should you use?
Select an answer to reveal the explanation.
Short Explanation
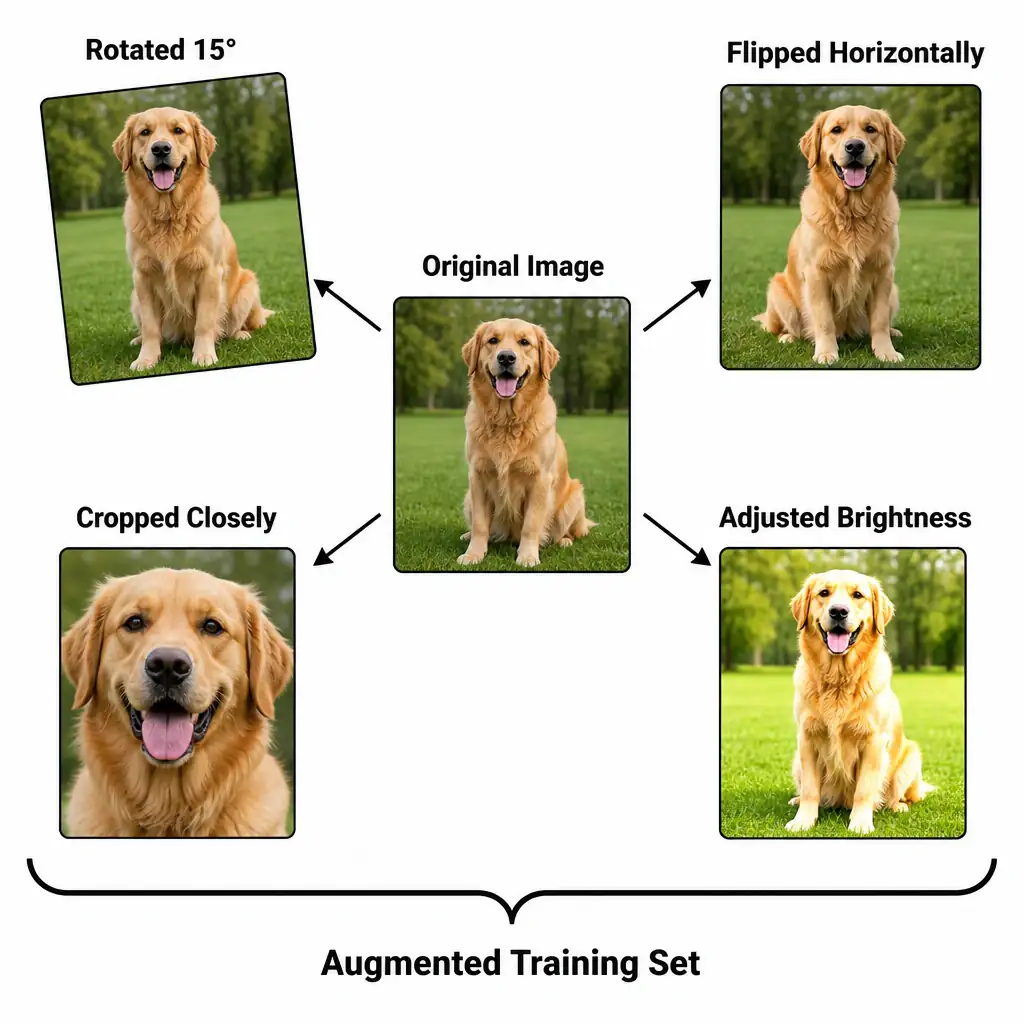
Check this out—if you train your bird classifier on only a few hundred clean, centered photos, it will fail when a bird is upside down, zoomed out, or differently lit. Instead, use data augmentation: randomly flip, rotate, crop, or adjust brightness on existing images so the network sees many label-preserving variations. This multiplies your dataset size and teaches the model to recognize the bird, not the original photo angle.
Full Explanation
Data augmentation is a technique commonly used to artificially expand the size and diversity of a training dataset by creating modified versions of the existing data points. It is especially prevalent in computer vision, but it is also used in natural language processing and audio classification.
When training deep learning models, having insufficient data often leads to overfitting, where the model memorizes the specific details of the training set rather than learning generalizable patterns. Data augmentation addresses this by applying various random, label-preserving transformations to the input data. For image datasets, these transformations include horizontal and vertical flipping, rotation by small angles, zooming and cropping, adjusting brightness, contrast, or color saturation, and adding minor noise such as Gaussian noise. Since these modifications do not change the actual class of the image—an image of a blue jay is still a blue jay even if it is flipped or rotated—they force the model to be invariant to these transformations. This improves the model's generalization capabilities on unseen test data.
The other choices do not solve the problem. Feature extraction, described as selecting only the most relevant pixels, identifies important descriptors in the images, but it does not increase the dataset size. Principal Component Analysis (PCA), described as compressing image features into a lower-dimensional space, is a dimensionality reduction technique used to compress features and reduce dataset width, not to expand the number of training samples. Dataset pruning, described as removing duplicate or highly similar images, involves removing data points to clean up or downsize the dataset, which is the opposite of expanding the training set.
Therefore, data augmentation, by applying random transformations like rotations, flips, and crops to the existing images, is the correct technique for artificially increasing dataset size and diversity.