
You are designing a Convolutional Neural Network (CNN) for facial recognition. As the feature maps pass deeper into the network, the computational load threatens to overwhelm your hardware. Which type of layer should you insert to downsample the feature maps, reducing their width and height while retaining the most important visual information?
Select an answer to reveal the explanation.
Short Explanation
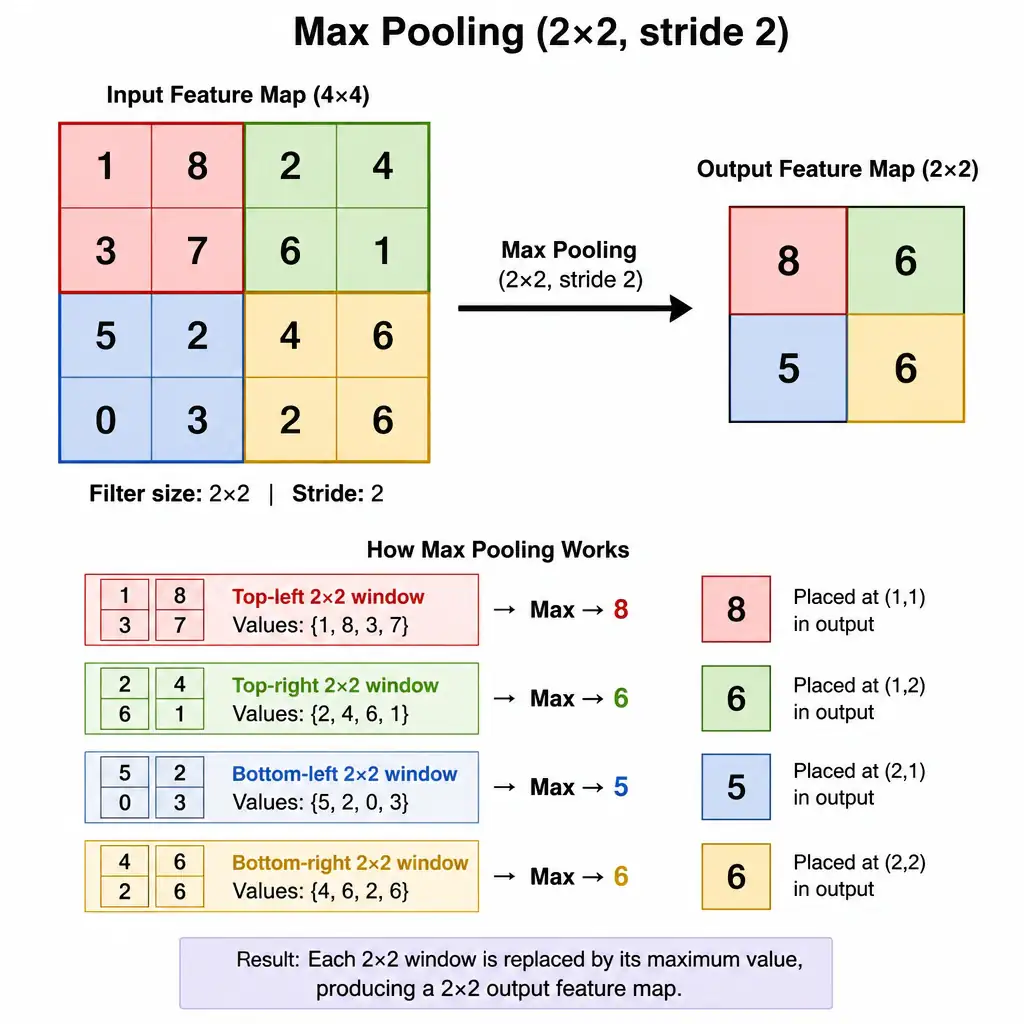
When your convolutional layers spit out huge feature maps, you've got to shrink their width and height with a pooling layer. Max Pooling scans a small window, keeps the strongest value, and tosses the rest, so your hardware can keep up while the important visual patterns survive.
Full Explanation
In Convolutional Neural Networks (CNNs), a pooling layer is a standard component inserted between successive convolutional layers. Its primary purpose is to reduce the spatial dimensions (width and height) of the input volume (the feature maps).
Pooling operates independently on each depth slice of the input and downsamples it. The most common form is Max Pooling, which applies a filter (typically 2x2 with a stride of 2) across the input and selects the maximum value within that sub-window, discarding the remaining values. Another variation is Average Pooling, which calculates the mean value of the sub-window.
By reducing the spatial dimensions, pooling serves several critical functions: 1. Computational Efficiency: It reduces the total number of parameters and computations required in the subsequent layers of the network, preventing GPU memory exhaustion. 2. Overfitting Control: By summarizing features, it abstracts the representation and reduces the risk of the model memorizing precise pixel locations. 3. Translation Invariance: It helps the network become invariant to small translations, rotations, or distortions of the features in the input image. If an active feature shifts slightly, its pooled value will often remain the same.
Let's review the incorrect choices: - The fully connected layer that maps all extracted features to class probabilities flattens the feature maps and connects every neuron to every activation of the previous layer, which actually increases the parameter count significantly. - The batch normalization layer that standardizes inputs across mini-batches standardizes activations to stabilize and accelerate training, but does not alter the spatial dimensions of feature maps. - The activation layer such as ReLU that introduces non-linear thresholds applies element-wise mathematical transformations to introduce non-linearity, keeping the spatial dimensions identical.
Therefore, the pooling layer, such as Max Pooling, is specifically designed to downsample the spatial dimensions.