
Your team is building a computer vision system to identify defects in manufacturing parts on a conveyor belt. A senior engineer recommends using a traditional machine learning approach like Support Vector Machines (SVMs) with hand-crafted descriptors like HOG (Histogram of Oriented Gradients). You advocate for a Deep Learning approach using a Convolutional Neural Network (CNN). What is the primary advantage of your proposed deep learning approach over the traditional pipeline?
Select an answer to reveal the explanation.
Short Explanation
Check this out—CNNs learn the useful visual features straight from the raw pixels, so you skip the painful work of hand-crafting descriptors like HOG. That’s the big win: the model builds its own representations instead of relying on fragile, manually engineered features.
Full Explanation
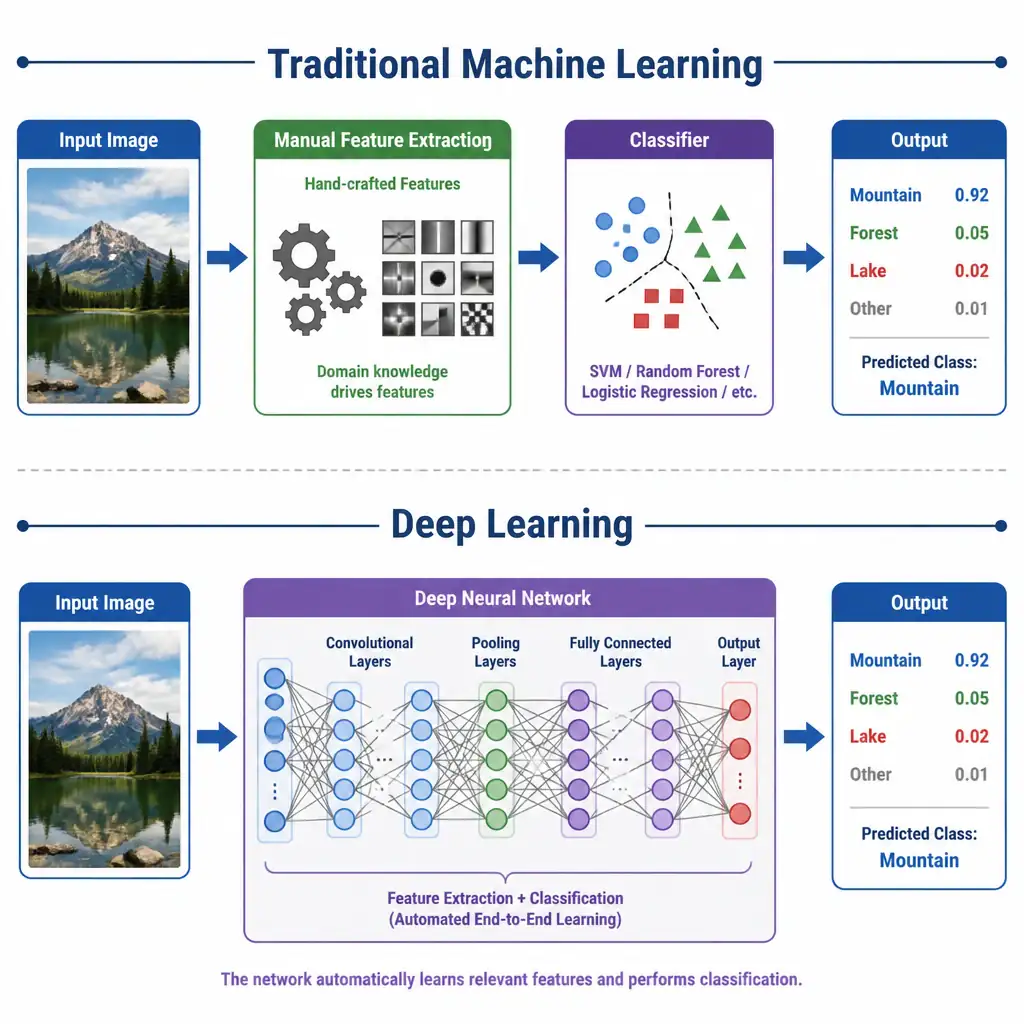
The fundamental distinction between traditional machine learning and deep learning in computer vision lies in how features are extracted from raw data. Traditional computer vision pipelines rely heavily on manual feature engineering. Engineers use domain expertise to write algorithms that extract specific hand-crafted features, such as edges, textures, or keypoints, using methods like Scale-Invariant Feature Transform (SIFT) or Histogram of Oriented Gradients (HOG). These extracted features are then passed into a classifier like a Support Vector Machine (SVM) or Random Forest. This approach is highly fragile, as the engineered features may not generalize well to variations in lighting, scale, orientation, or background clutter.
In contrast, deep learning architectures, specifically Convolutional Neural Networks (CNNs), combine feature extraction and classification into a single, end-to-end learning pipeline. Through backpropagation, the model automatically learns hierarchical representations directly from raw pixel inputs. The lower convolutional layers detect low-level features such as edges and color gradients. The middle layers combine these to represent shapes and textures, and the higher layers construct complex semantic concepts corresponding to the target objects. This automatic feature extraction makes deep learning models highly robust and capable of achieving state-of-the-art accuracy on complex image recognition tasks.
The correct advantage is that deep learning models bypass the need for manual feature engineering by learning representations directly from the raw pixels. This is the primary reason a CNN is preferable to a traditional pipeline built around hand-crafted descriptors and a separate classifier.
The claim that deep learning models are highly interpretable, making it easy to explain exactly how they make decisions, is incorrect. Deep learning models are notoriously difficult to interpret, often referred to as 'black boxes' because they contain millions of parameters, unlike simpler decision trees or linear classifiers.
The claim that deep learning models require far less labeled training data to achieve high classification accuracy is incorrect. Deep learning models generally require massive datasets to generalize effectively without overfitting, whereas traditional machine learning models can sometimes perform reasonably well on smaller datasets.
The claim that deep learning models require significantly less computational power and memory during training is incorrect. Deep learning models are extremely compute-intensive and require powerful hardware like GPUs or TPUs to train.