
Why must we apply non-linear activation functions (like ReLU or Sigmoid) between the layers of a deep neural network rather than just stacking linear layers?
Select an answer to reveal the explanation.
Short Explanation
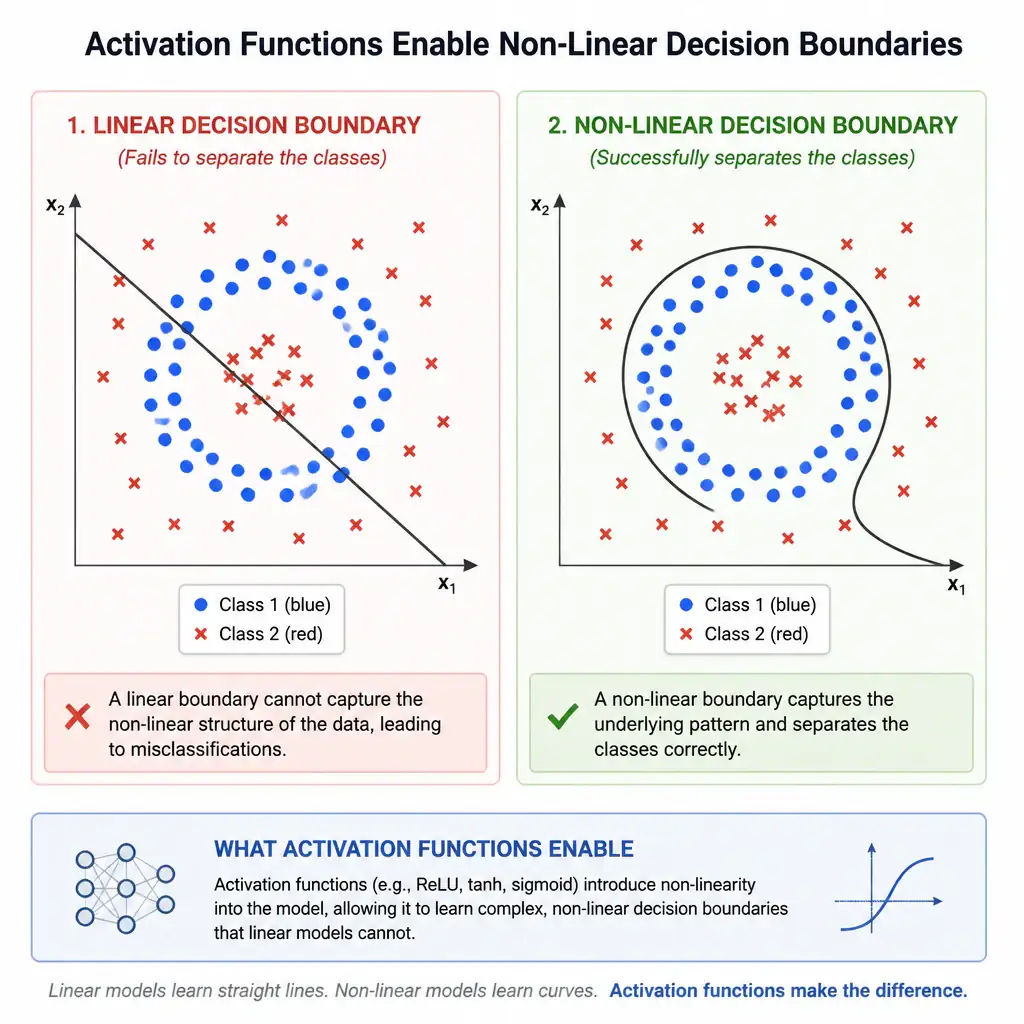
Here's the deal: if you stack linear layers without activations, you just get one big linear model, no matter how deep it is. You need non-linear functions like ReLU or Sigmoid to bend the decision boundaries and learn complex patterns.
Full Explanation
In deep learning, the capability of neural networks to solve highly complex tasks stems from their architectural depth and non-linear properties. The correct reason is to introduce non-linearity, allowing the network to learn complex decision boundaries. A linear transformation is represented as f(x) = wx + b. If you stack multiple layers that only perform linear transformations, the composition of these layers is mathematically equivalent to a single linear transformation: y = W_3(W_2(W_1 x + b_1) + b_2) + b_3 = W_effective x + b_effective. Without a non-linear activation function, a neural network with a hundred layers would have no more representational power than a simple linear regression model. It would be incapable of learning complex patterns, curves, or decision boundaries, such as the XOR gate problem or image recognition features. Non-linear functions like ReLU, Sigmoid, or Tanh allow the network to approximate virtually any continuous function, which is the idea behind the Universal Approximation Theorem. The claim that activations prevent weights from initializing to zero is wrong because weight initialization is handled by specific initialization algorithms, such as Xavier or He initialization, before training begins, not by the activation function. The claim that activations calculate the classification loss at the output layer is wrong because loss calculation is performed by a loss function, like Cross-Entropy or Mean Squared Error, at the output layer to evaluate prediction error, not by the activation functions within the hidden layers. The claim that activations guarantee that the model never experiences overfitting is wrong because overfitting is actually more likely in highly complex non-linear models, and regularization techniques, like dropout or L2 regularization, are used to mitigate overfitting, not activation functions. Therefore, activation functions are required to introduce non-linearity, enabling deep neural networks to model complex relationships.