
Your team is tasked with building a machine learning model to predict home prices in a new residential development based on historical sales figures and housing features. Because you have labeled training data consisting of both the features and the final selling prices, you need an algorithm that learns the mapping function from inputs to outputs. Which of the following algorithms should you choose?
Select an answer to reveal the explanation.
Short Explanation
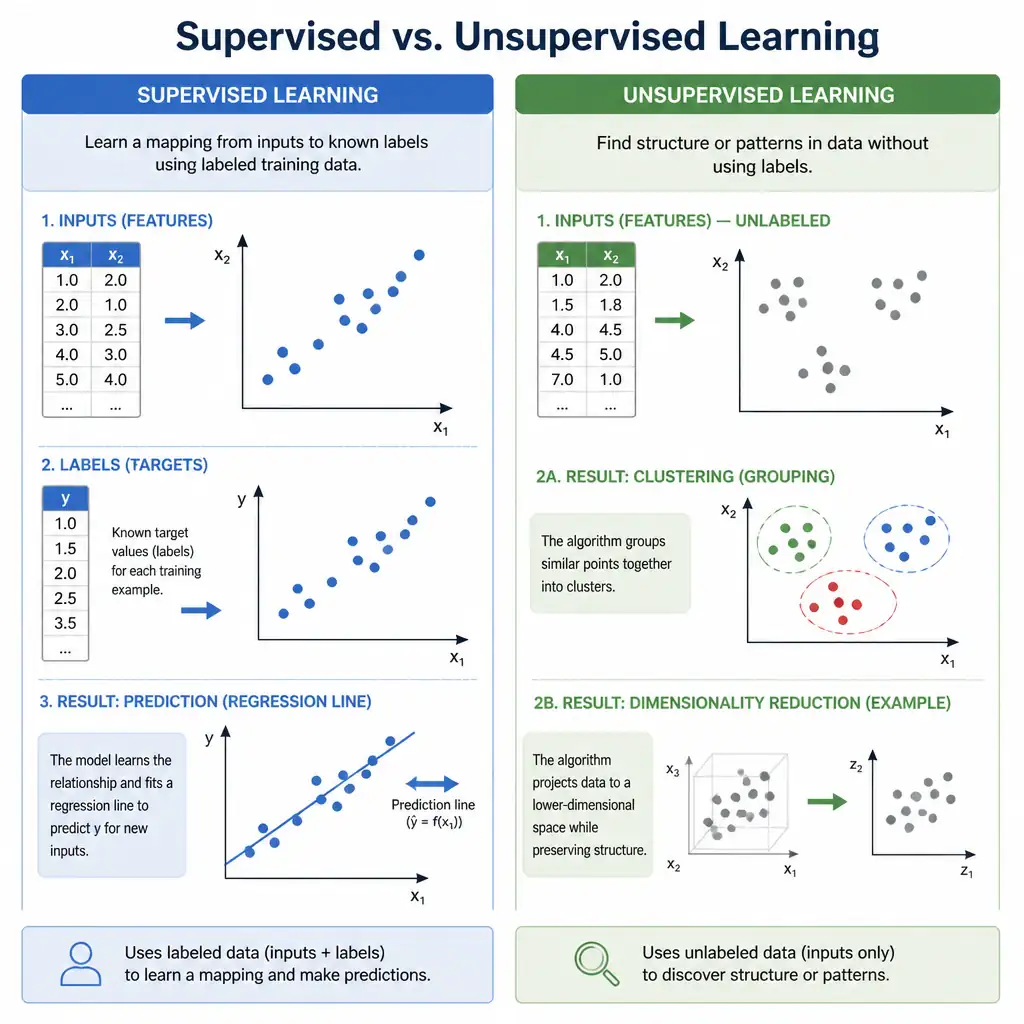
When you've got labeled data like historical home prices, you're doing supervised learning. Linear Regression fits the bill because it maps inputs such as square footage to a continuous output like price. The clustering, dimensionality-reduction, and association-rule options don't learn that input-to-price mapping.
Full Explanation
In machine learning, algorithms are broadly classified into supervised and unsupervised learning based on the presence of labeled data. Supervised learning algorithms are trained on a labeled dataset, where each training example is paired with its correct output label. The goal of the algorithm is to learn a mapping function from input variables (x) to output variables (y). Linear Regression is a fundamental supervised learning algorithm used for regression tasks. It models the relationship between a dependent scalar variable (the output) and one or more explanatory variables (inputs) by fitting a linear equation to the observed data. Because the historical sales data includes both the input features (such as square footage or location) and the target labels (selling prices), it requires a supervised method like Linear Regression. K-Means Clustering is an unsupervised learning algorithm. It is designed to partition unlabeled data into K distinct, non-overlapping clusters based on feature similarity. It does not use target labels and cannot make predictions of continuous variables like price. Principal Component Analysis (PCA) is an unsupervised dimensionality reduction technique. It is used to project high-dimensional data onto a lower-dimensional space while preserving as much variance as possible. It is not used for mapping inputs to labeled outputs. Apriori Association Rules is an unsupervised data mining algorithm used for market basket analysis. It identifies frequent itemsets and association rules within transactional databases, rather than predicting continuous target variables from input features. Therefore, Linear Regression is the correct choice for this supervised learning scenario.