
When designing a neural network to model sequential or time-series data—such as predicting stock prices or translating languages—which architectural component is essential for a Recurrent Neural Network (RNN) to track temporal dependencies?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal: if you're modeling sequences, you need something that remembers what came before. Recurrent units or memory cells pass an internal hidden state from one step to the next, so the network keeps temporal context instead of forgetting every input.
Full Explanation
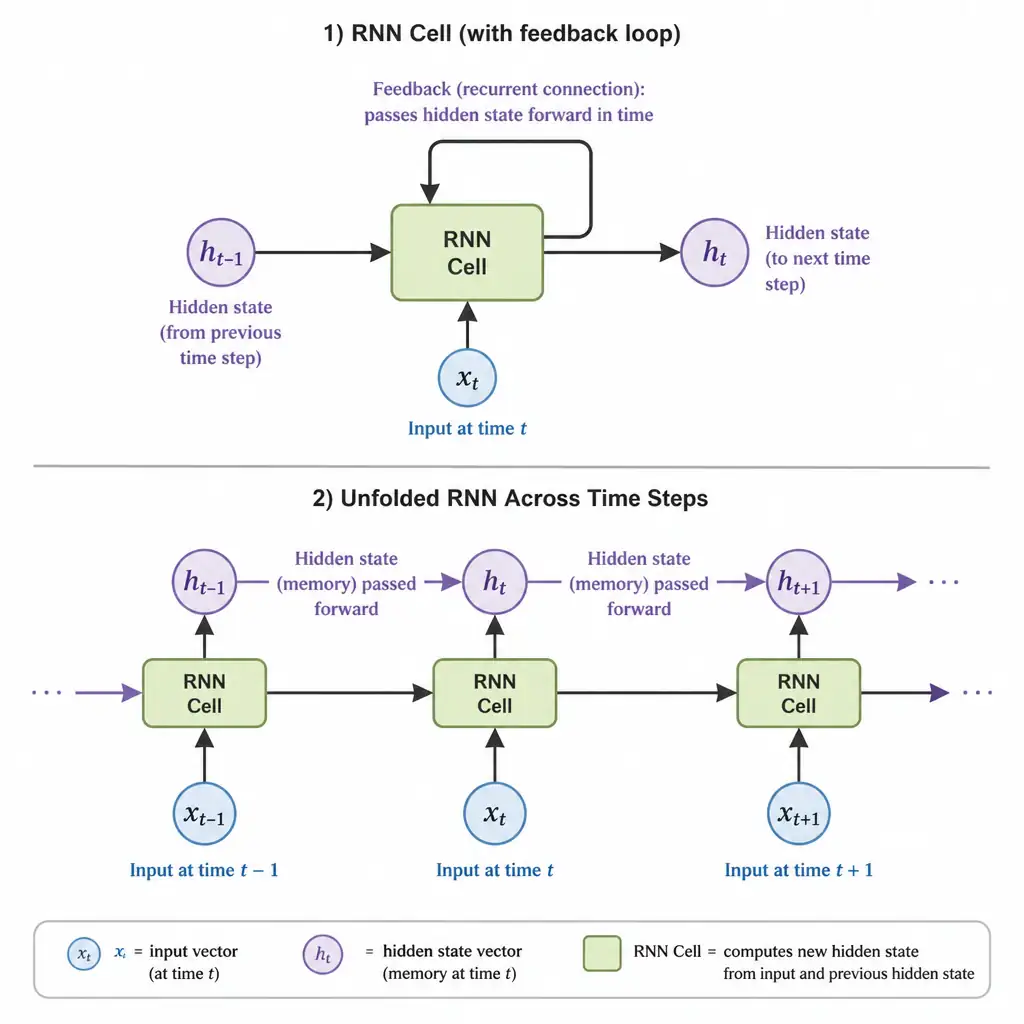
Recurrent Neural Networks (RNNs) are designed to process sequential data where the order of inputs is critical. Unlike standard feedforward architectures, which assume all inputs are independent, RNNs process sequences step-by-step and maintain an internal hidden state that acts as a memory of what the network has seen so far.
This memory is implemented via recurrent connections or memory cells, such as recurrent units. At each time step t, the recurrent unit takes the current input vector x_t and the previous hidden state vector h_{t-1} to calculate the new hidden state h_t. This hidden state is then passed forward to the next step. In more advanced architectures like Long Short-Term Memory networks or Gated Recurrent Units, specialized internal gates, including input, forget, and output gates, manage this memory, allowing the network to retain important long-term dependencies while discarding irrelevant information and mitigating the vanishing gradient problem.
The static convolutional filters that extract localized spatial patterns from grid structured inputs are characteristic of Convolutional Neural Networks used for extracting spatial features from static images or grid data, not the defining mechanism of an RNN.
The multi-head attention mechanisms that compute relationships between all words in a sentence simultaneously are the core component of Transformer models. While Transformers handle sequences, they do so in parallel using self-attention rather than sequential recurrent memory cells.
The normalization operations that scale features across a mini-batch to speed up optimization describe Batch Normalization, which is an optimization technique used in many different architectures to accelerate training, but is not the defining architectural element of an RNN.
For the exam, remember that the defining feature of an RNN is its ability to handle sequence data through feedback loops and internal memory states.