
When analyzing the structural layout of various neural network architectures, what is the primary difference between a shallow neural network and a deep neural network?
Select an answer to reveal the explanation.
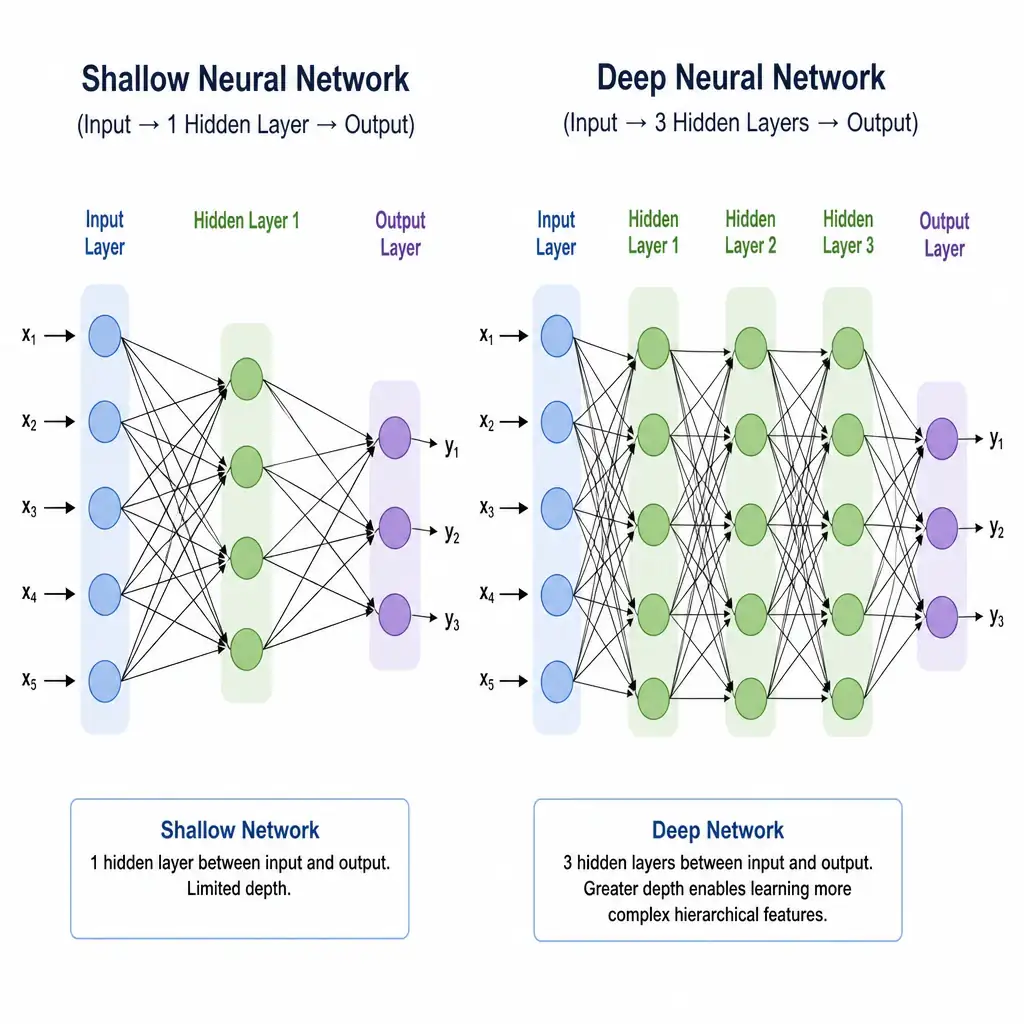
Short Explanation
You've probably heard 'deep learning' many times, but it's not magic—it's depth! The 'deep' part means multiple hidden layers stacked between input and output, while shallow network has very few. That depth lets network build hierarchy of features, from simple patterns to complex concepts.
Full Explanation
The correct statement says deep neural network contains multiple hidden layers stacked between input and output layers, whereas shallow network has very few. The fundamental distinction between shallow and deep neural networks lies in architectural depth, determined by number of hidden layers between input and output layers. Shallow neural network typically contains only one or two hidden layers. Under Universal Approximation Theorem, shallow network with single hidden layer containing infinite number of neurons can theoretically approximate any continuous function. However, representing complex functions with shallow network requires impractically large number of parameters (neurons), making it computationally inefficient and prone to overfitting. Deep neural network addresses this by stacking multiple hidden layers sequentially. This allows model to learn hierarchical representations of data. Early layers extract low-level features, which are then combined by deeper layers to represent highly abstract patterns. This hierarchical structure allows deep networks to approximate complex mappings with significantly fewer total parameters than shallow network. The claim that shallow neural network is restricted to single layer in total, combining input and output functions into one vector, is incorrect because even shallow network consists of at least three distinct layers: input layer, one hidden layer, and output layer. It is not restricted to single combined layer. The claim that deep neural network is structurally limited and can only be applied to multi-dimensional image arrays is incorrect because deep networks are general-purpose architectures used for wide-ranging data formats, including natural language text, speech signals, tabular data, and time-series sequences—not just images. The claim that shallow neural network is mathematically prohibited from using non-linear activation functions like ReLU is incorrect because shallow networks can, and regularly do, utilize non-linear activation functions such as Sigmoid, Tanh, or ReLU to solve non-linear problems. For exam, remember that 'deep' refers directly to presence of multiple sequential hidden layers that facilitate hierarchical feature extraction.