
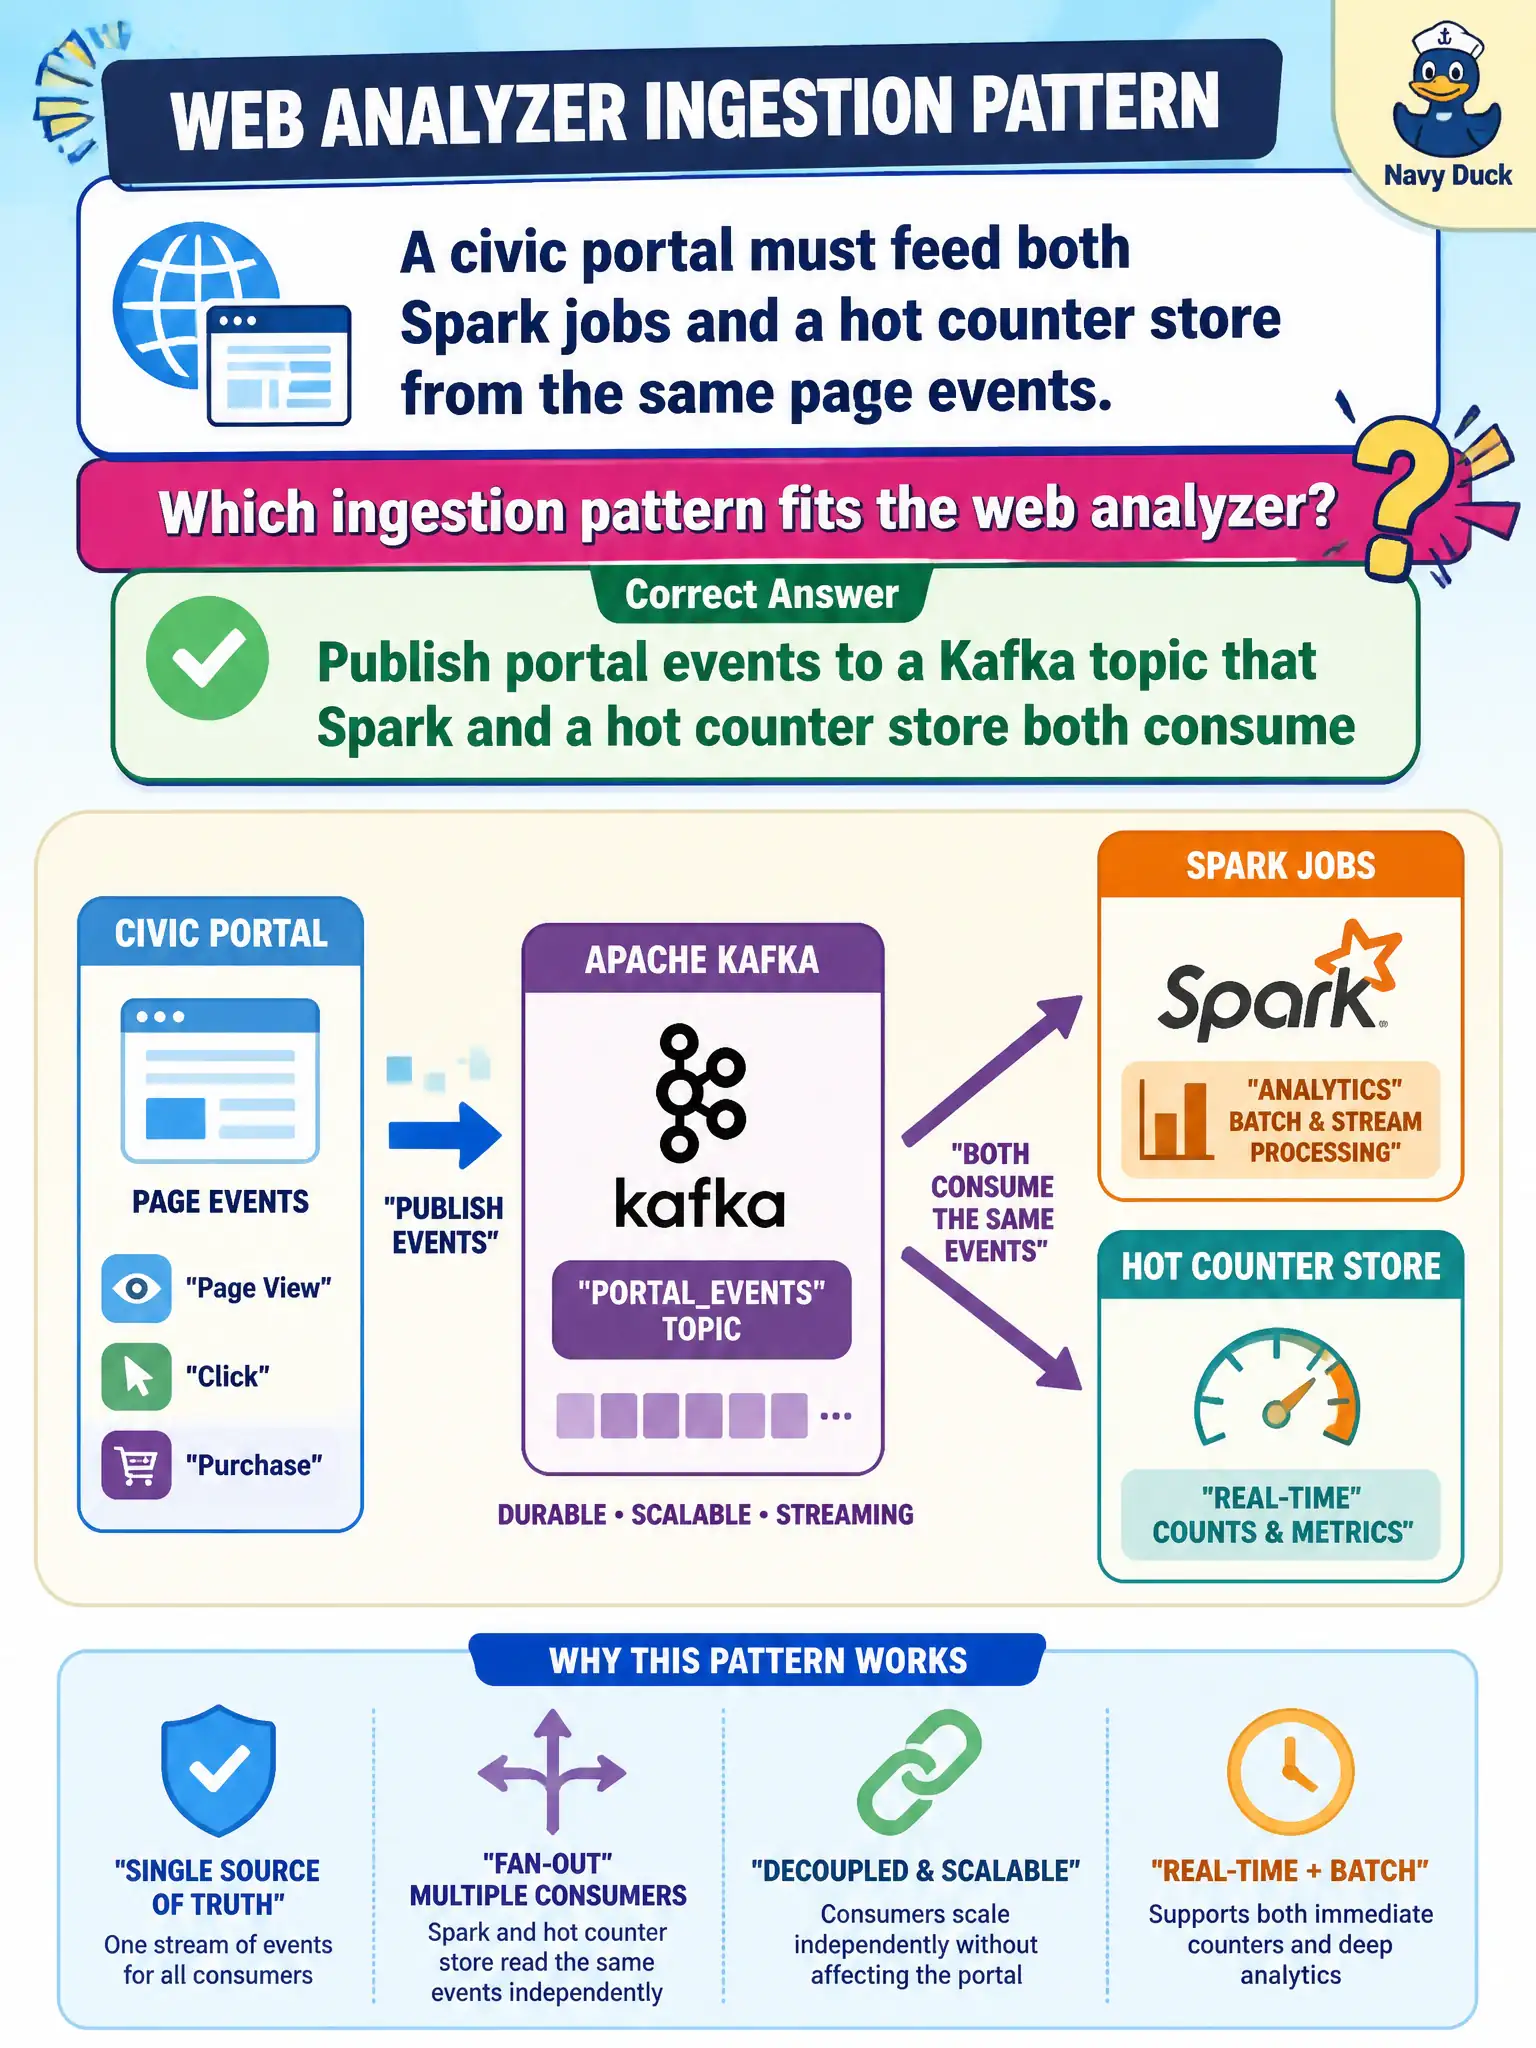
A civic portal must feed both Spark jobs and a hot counter store from the same page events. Which ingestion pattern fits the web analyzer?
Select an answer to reveal the explanation.
Short Explanation
One topic, many listeners—that is the Kafka idea for city page hits. Spark can crunch history while a hot store ticks live counters from the same stream. Publish once, consume many times, and stop forking brittle copy pipelines.
Full Explanation
Publishing portal events to a Kafka topic that both Spark jobs and a hot counter store consume is the ingestion fan-out pattern that fits a civic web analyzer needing batch depth and live counters. One governed event contract feeds multiple sinks without dual silent instrumentation. Chapter 8 and Chapter 10 ideas meet here: the bus as shared spine for municipal analytics.
Writing events only to a laptop CSV that each team copies by email overnight cannot reliably feed Spark and hot counters with shared semantics. Hard-coding separate silent beacons that never share a common event bus multiplies drift and double-counts risk. Bypassing ingestion so dashboards query production OLTP tables under lock couples analytics load to transactional systems unwisely.
Exam caveat: both consumers still need their own lag monitoring and idempotent writes; a healthy topic does not guarantee every sink is correct. Operational check: publish a test portal event and confirm it increments a hot counter and lands in a Spark-readable lake path from the same Kafka topic without separate beacon codepaths. Document the verified decision in the municipal architecture runbook so future on-call and audit staff inherit the same standard.