
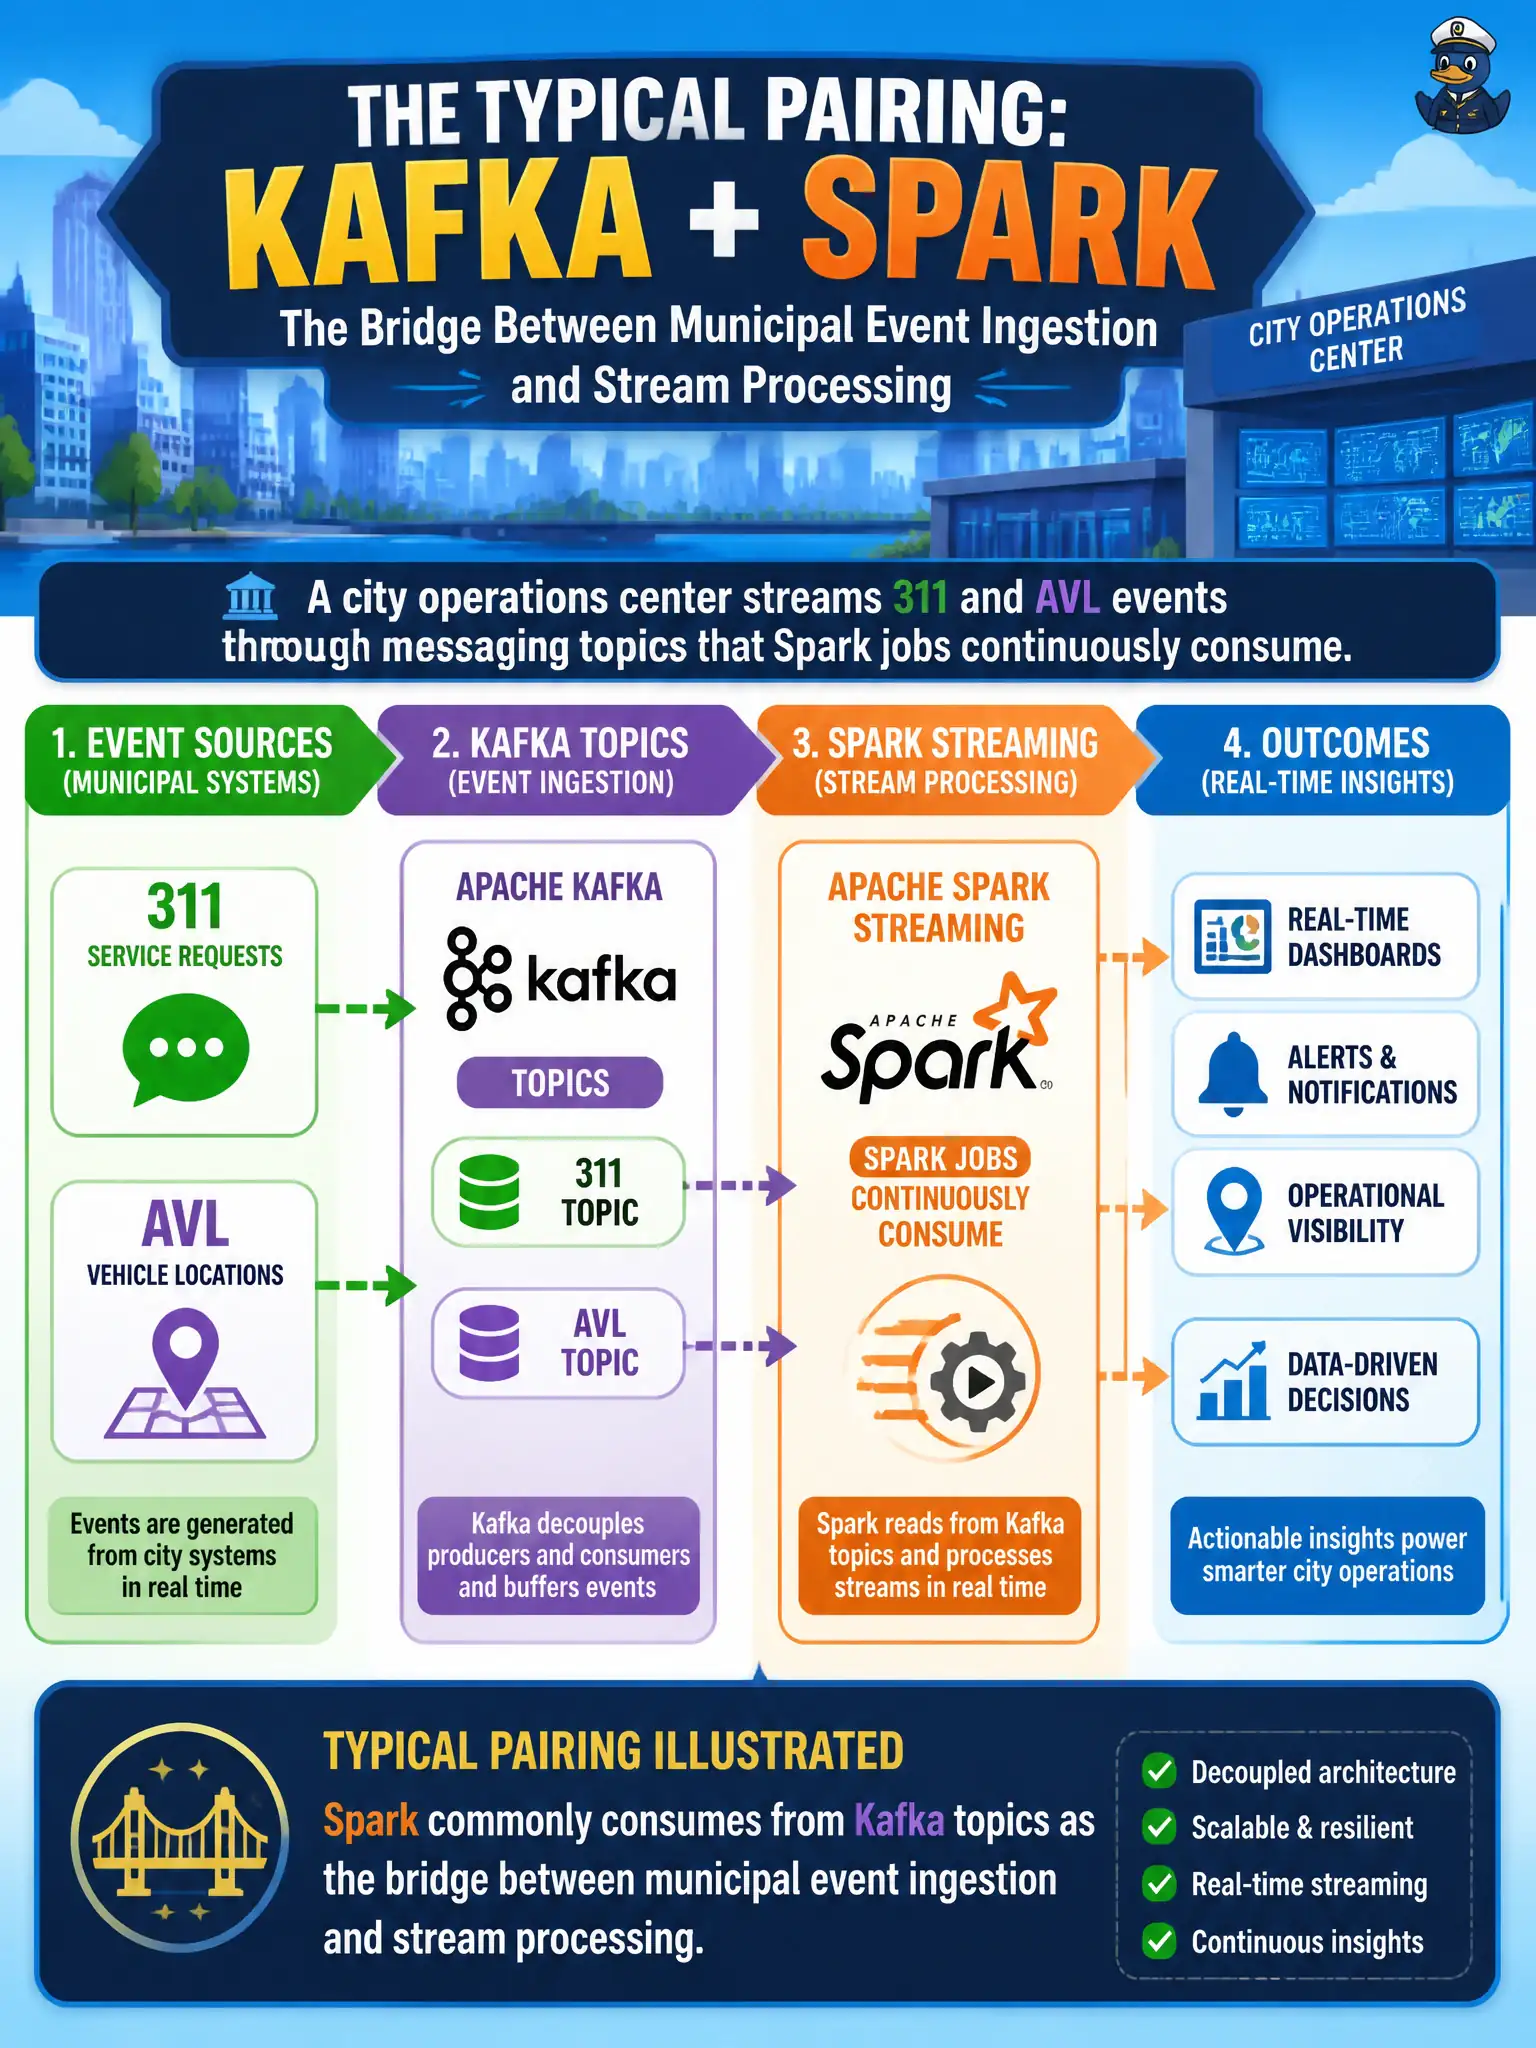
A city operations center streams 311 and AVL events through messaging topics that Spark jobs continuously consume. What typical pairing does this illustrate?
Select an answer to reveal the explanation.
Short Explanation
Kafka is the city's radio channel; Spark is the dispatch board listening in. Events hop on the topic, and Spark jobs tune in to process them as they arrive.
Full Explanation
Streaming 311 and AVL events through messaging topics that Spark jobs continuously consume illustrates a typical pairing: Spark commonly consumes from Kafka topics as the bridge between municipal event ingestion and stream processing. Messaging delivers; Spark analyzes. Spark must not ignore messaging systems and only read USB drives for live operations centers. Claiming Kafka-style topics cannot feed analytical stream processors is incorrect. Saying messaging buses replace Spark entirely for all analytics confuses transport with compute. Exam caveat: coordinate consumer groups, offsets, and schema evolution between the bus and Spark jobs so city feeds stay replayable. Operational check: verify a Spark structured streaming query is subscribed to the 311/AVL topics, check lag metrics under load, and confirm restart resumes from committed offsets. In production terms for Kafka topics feeding Spark jobs, assign an owning team, wire a dashboard that shows the pattern is healthy under peak civic load, and require a staging drill that rehearses failure and recovery before resident impact. Revisit the choice when traffic shape, retention, or integrity needs change, and keep a named rollback owner on the change record. Re-test both the happy path and the failure path for Kafka topics feeding Spark jobs after material dependency upgrades so regressions are caught before the next public release.