
A public-health team needs to send PDF inspection reports plus photos into Amazon Bedrock for multimodal analysis. What pipeline capability is required?
Select an answer to reveal the explanation.
Short Explanation
Inspection PDFs and photos are a package deal. The pipeline has to prep both text and images for multimodal Bedrock inputs—not toss the pictures or leave them in a shared inbox limbo.
Full Explanation
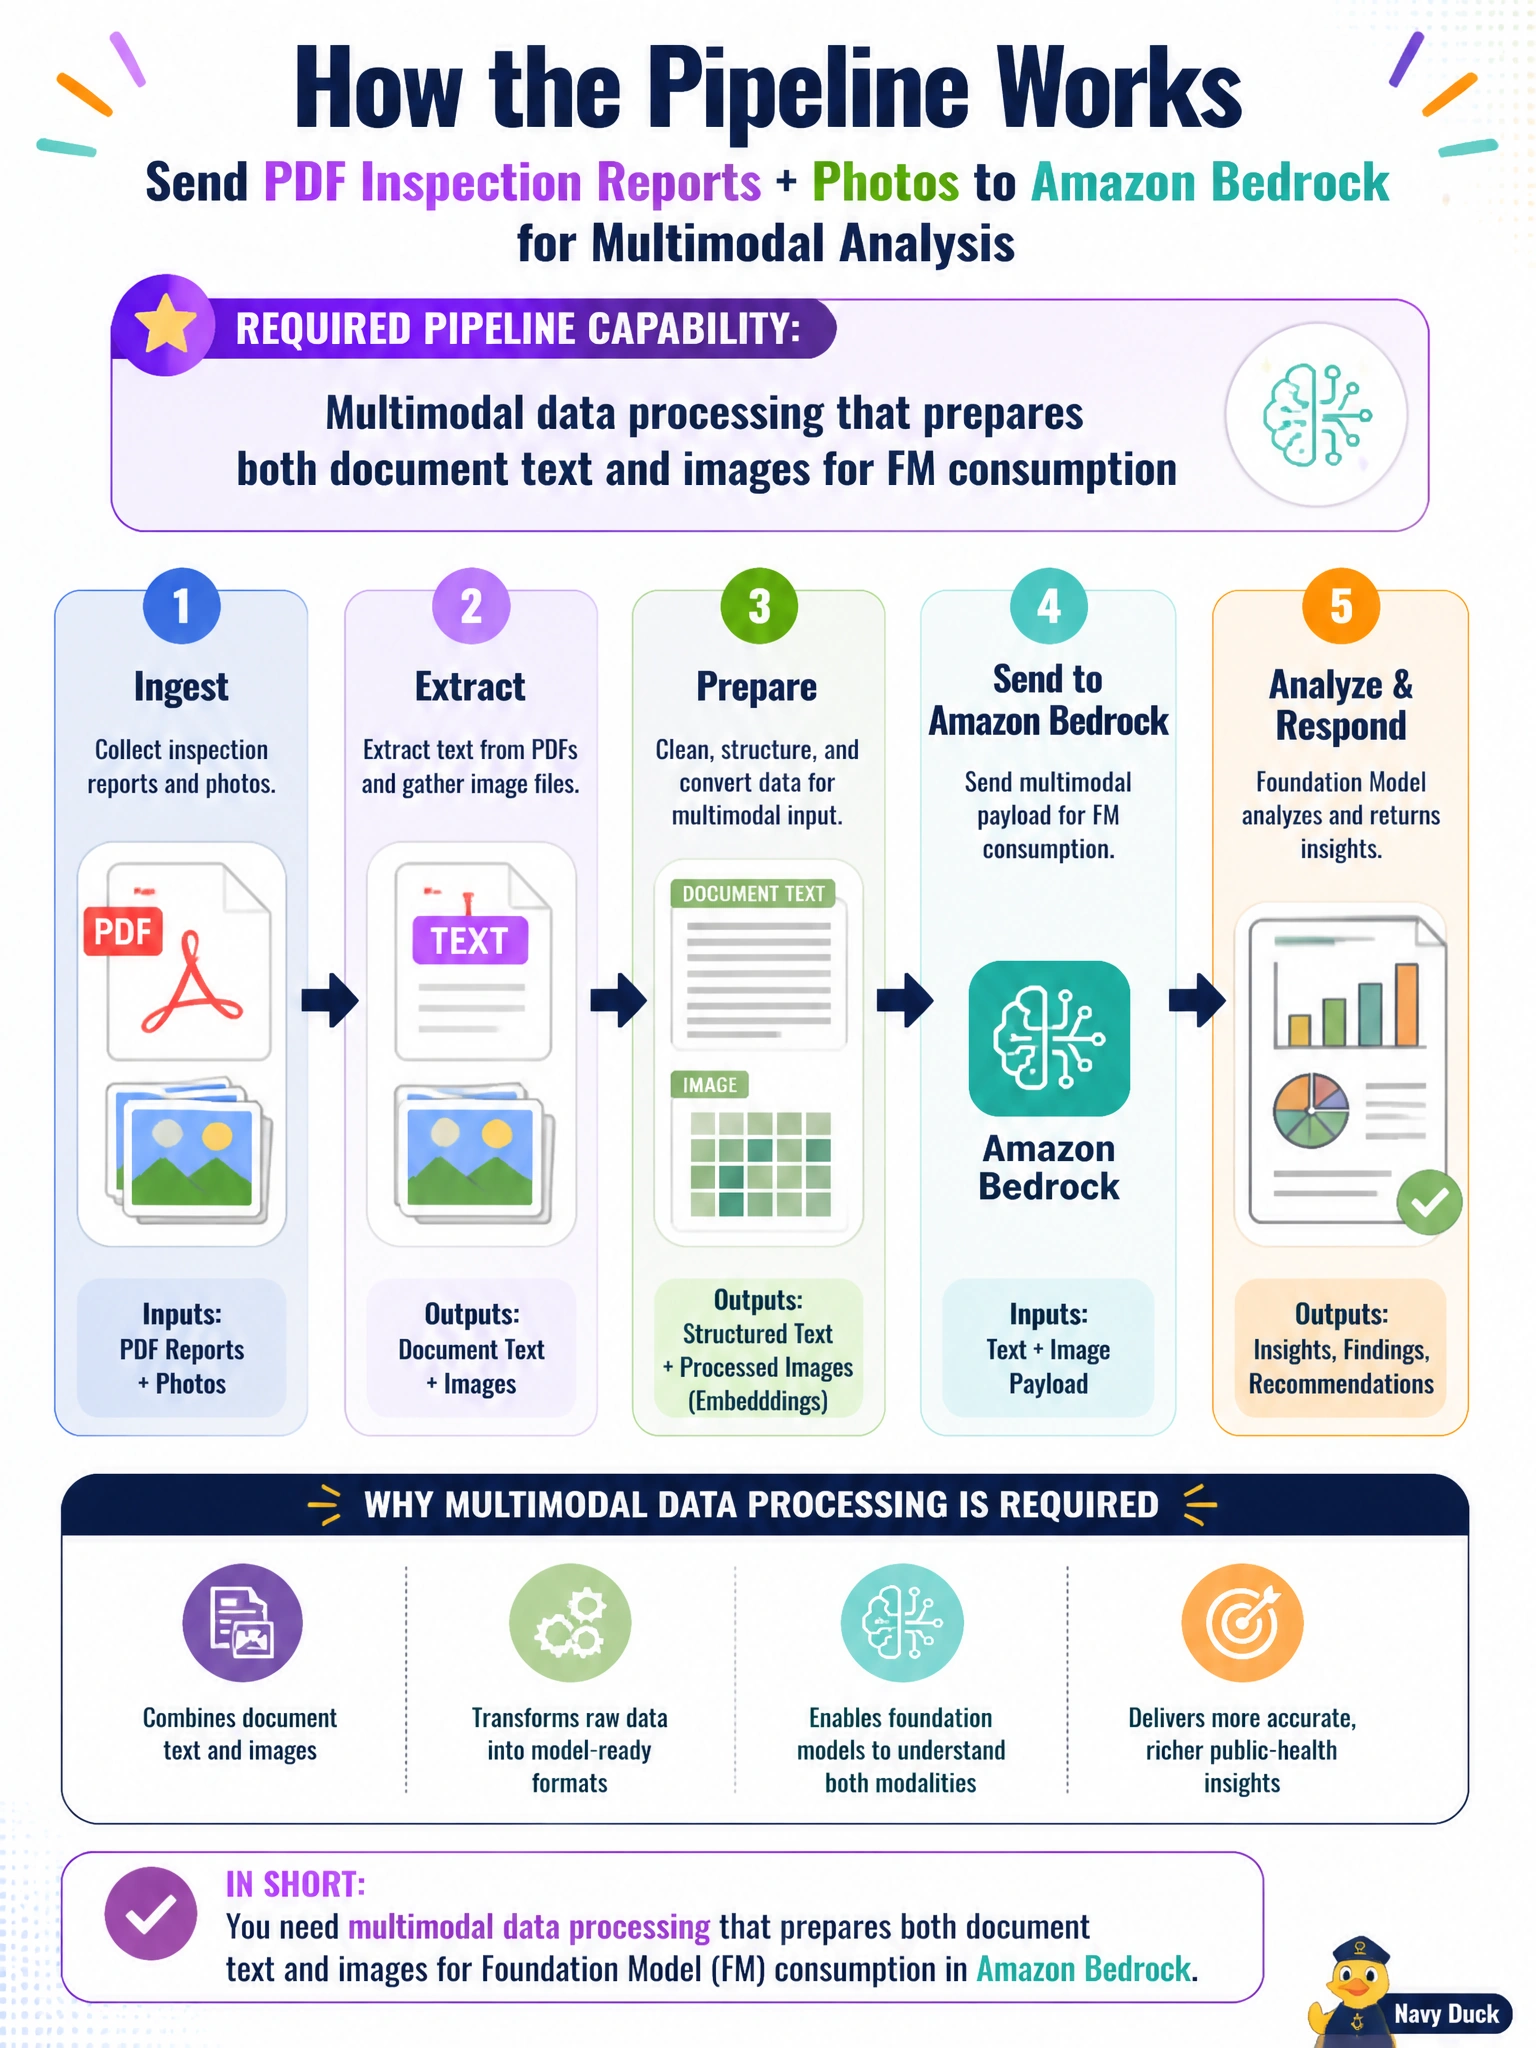
A public-health team sending PDF inspection reports plus photos into Amazon Bedrock for multimodal analysis needs multimodal data processing that prepares both document text and images for FM consumption. The pipeline must extract or preserve report text, normalize images (format, size, allowed MIME types), and assemble a Bedrock-compatible multimodal request so visual evidence and written findings are analyzed together. Dropping either modality loses inspection signal the model is being asked to use.
Text-only OCR that permanently discards all inspection photos satisfies a text path while violating the multimodal requirement. Emailing photos to a shared inbox with no structured FM input path creates an unstructured human queue, not a reproducible pipeline. Storing photos only on paper printouts in a filing cabinet keeps evidence offline and out of GenAI workflows entirely.
Exam caveat: multimodal Bedrock workloads require explicit prep for each modality; “we have PDFs and photos” is not the same as “the API received both.”
Operational check: ingest sample PDF+photo packages, verify the processor emits both text and image parts in the invoke payload, run multimodal analysis, and confirm outputs reference visual and textual findings before production cutover.