
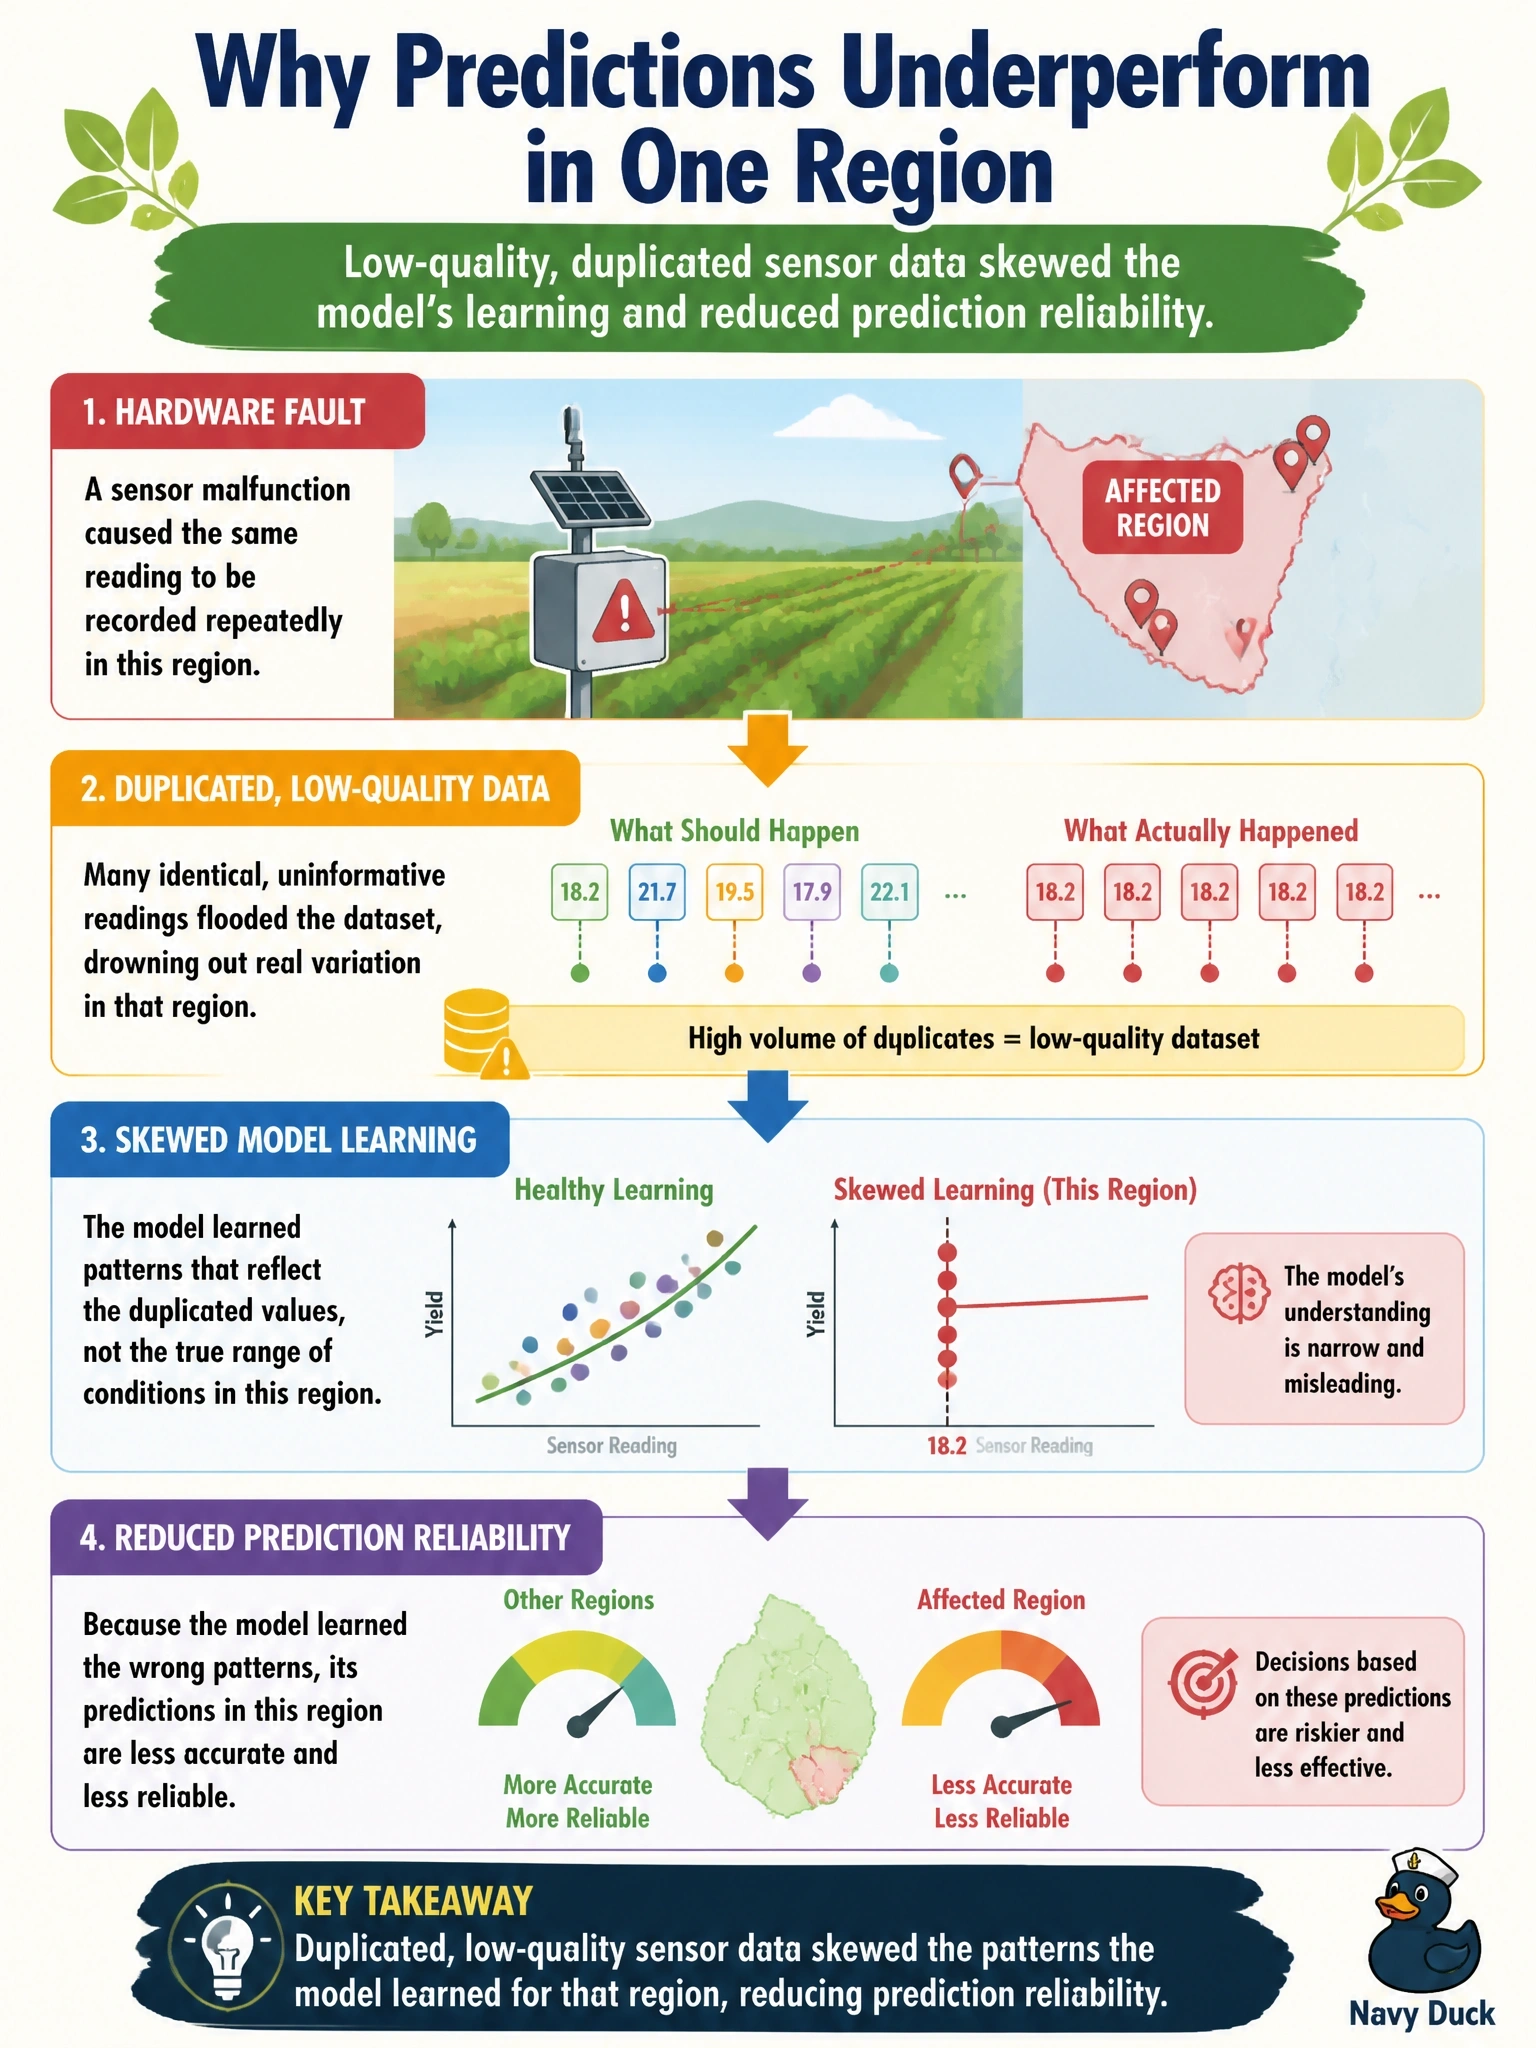
A farm cooperative's yield-prediction AI tool consistently underperforms in one region. Investigation shows that sensor readings from that region were frequently duplicated due to a hardware fault. What is the most likely explanation for the tool's poor performance there?
Select an answer to reveal the explanation.
Short Explanation
Imagine asking a room full of farmers for their opinion, but one person keeps shouting the same answer over and over — the room's average skews toward that one loud voice. That's what duplicated sensor readings do to your model: they overweight one set of conditions, so it learns a distorted, confidently wrong picture of that region's yield patterns.
Full Explanation
Duplicated sensor readings don't cancel out — they pile up. Every time a faulty sensor repeats a reading, that value gets counted again during training, so the model treats it as more representative of the region than it really is. Over enough repetitions, the model's learned relationship between conditions and yield for that region gets pulled toward whatever the duplicated readings happened to show, whether or not that reflects the actual range of conditions farmers experience there. The claim that duplicate entries simply cancel each other out misunderstands how training works: nothing in the math automatically offsets repeated values, it only amplifies their influence. The idea that the region's weather is just inherently more unpredictable sidesteps the specific, already-identified cause in the scenario — a hardware fault — and substitutes a vague, unverified alternative. And the notion that the tool automatically excludes data from regions with hardware faults assumes a safeguard that doesn't exist unless someone specifically builds and maintains it; AI systems don't self-audit their input pipelines by default. The operational check: whenever a model underperforms in one segment, look first at whether the data feeding that segment is complete, accurate, and non-duplicated before assuming the underlying phenomenon itself is simply harder to predict.