
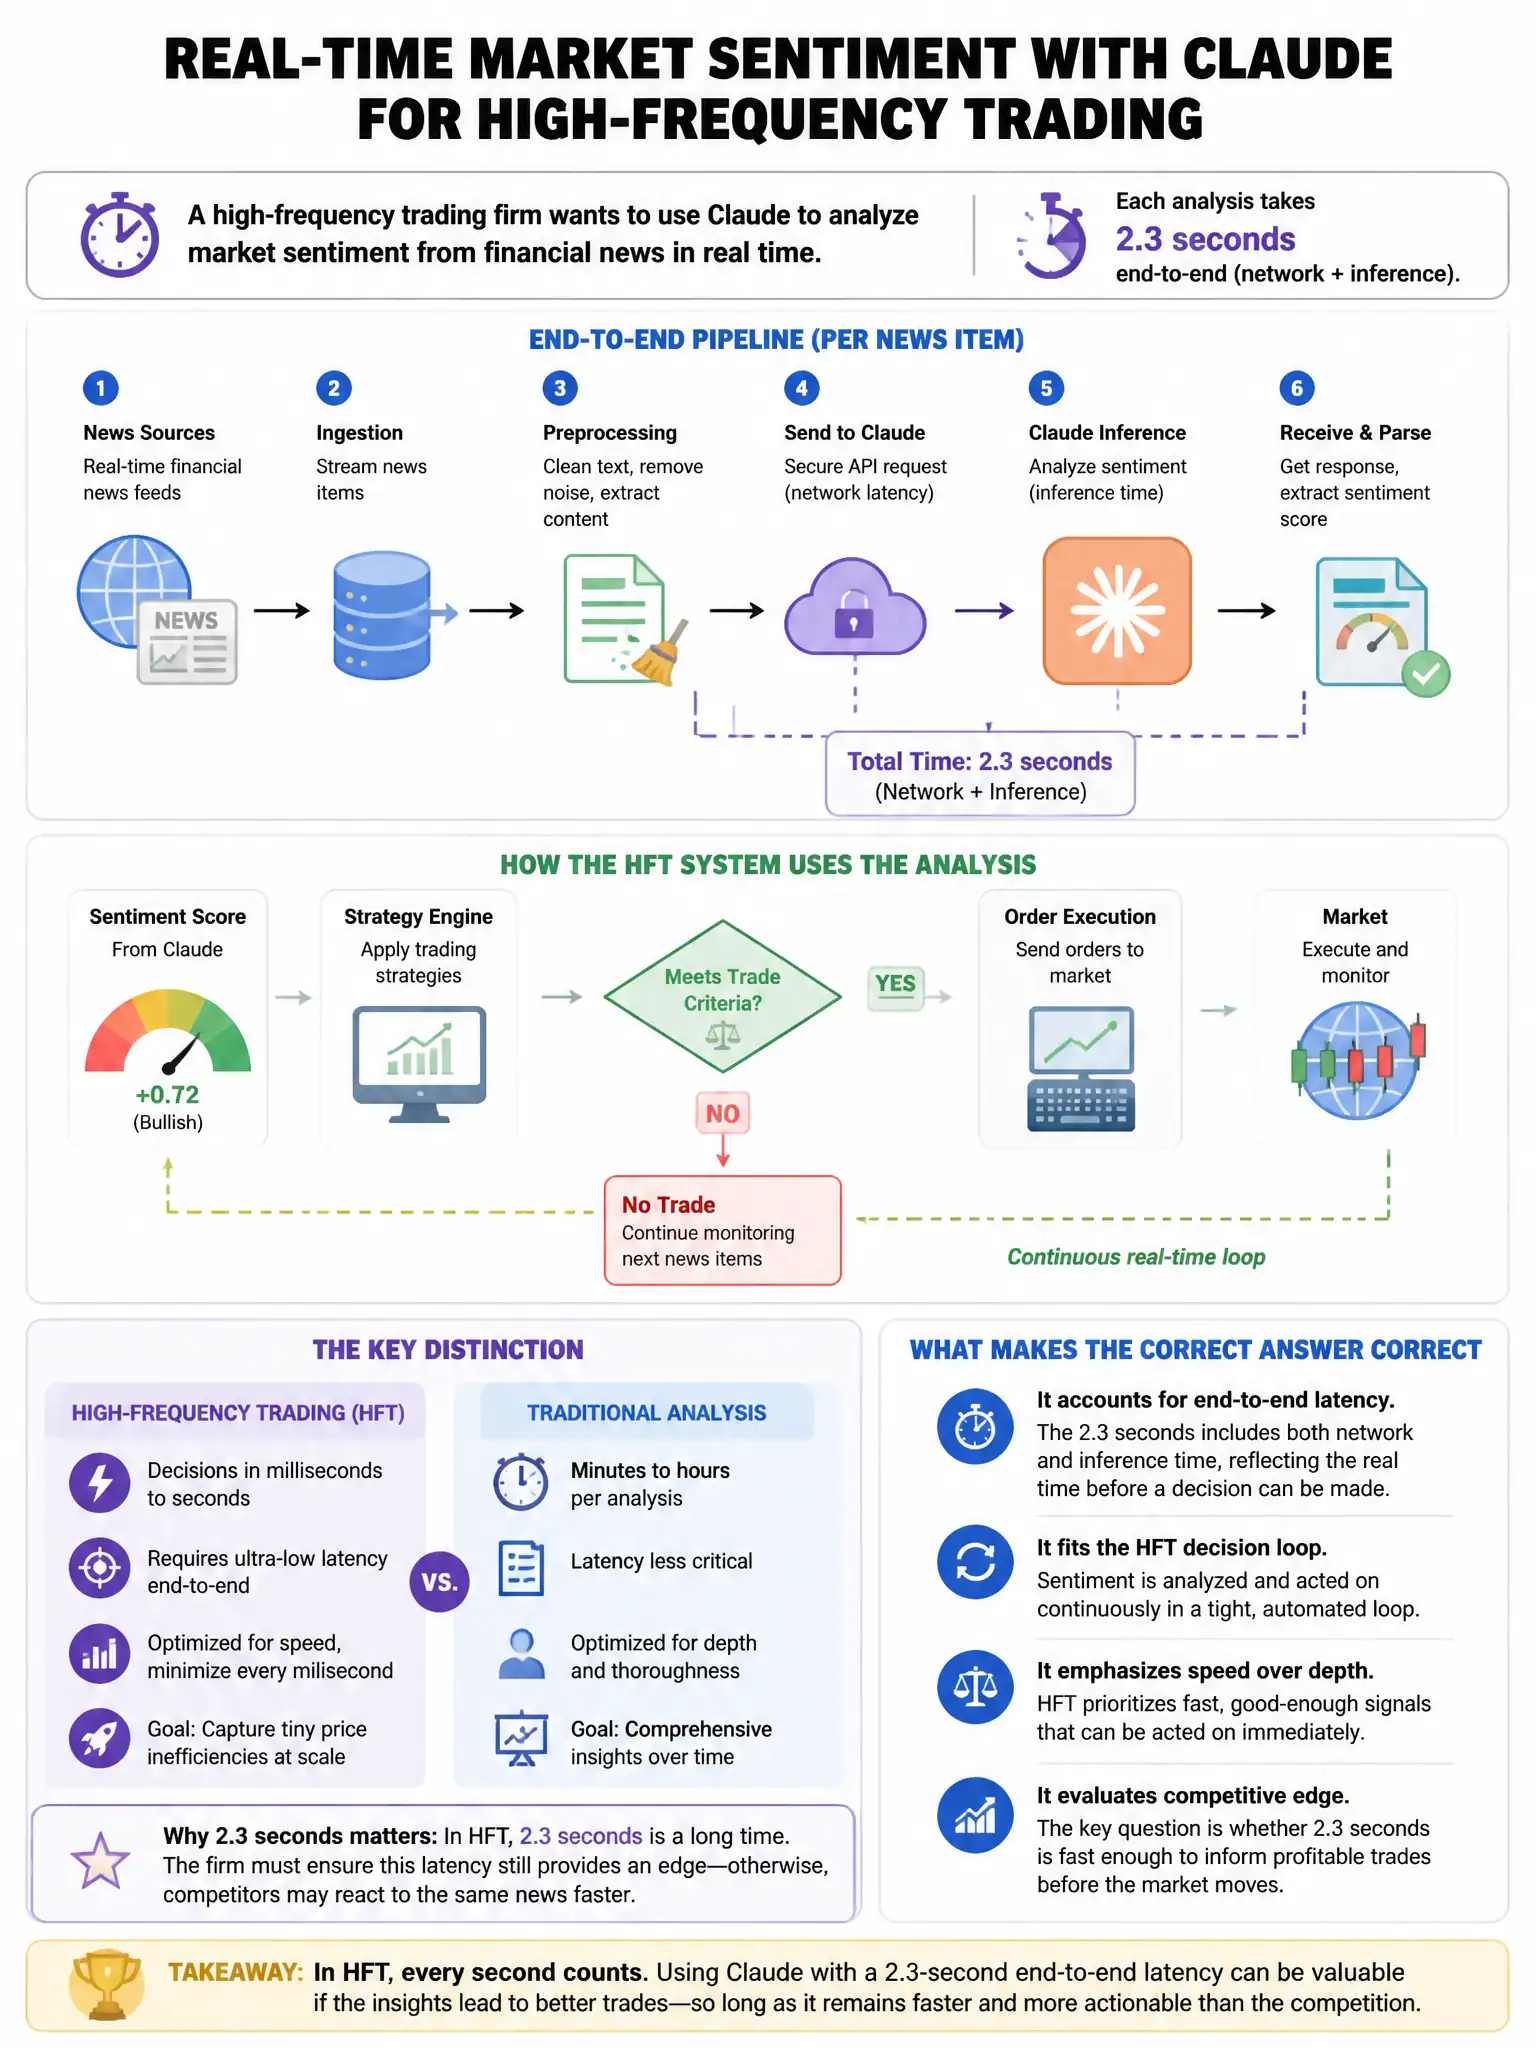
A high-frequency trading firm wants to use Claude to analyze market sentiment from financial news in real time. Each analysis takes 2.3 seconds end-to-end (network + inference). The system needs to analyze 500 news articles per minute. How many concurrent API connections must the architect provision, and what rate limit considerations apply?
Select an answer to reveal the explanation.
Short Explanation
You need about 20 concurrent connections because 500 articles per minute × 2.3 seconds ÷ 60 seconds ≈ 19.2. You'll also need to request a rate limit increase in advance, since a new API account's default limits may be too low.
Full Explanation
The correct approach is approximately 20 concurrent connections, calculated with Little's Law: throughput (500 articles per minute) × latency (2.3 seconds per article ÷ 60 seconds per minute ≈ 0.038 minutes) = 19.2 concurrent connections, so the architect should provision about 20 concurrent API connections to sustain the throughput. The critical planning insight is that new API accounts start at conservative rate limits for both requests per minute and tokens per minute, and reaching 500 requests per minute typically requires requesting a rate limit increase from Anthropic in advance, not just provisioning connections. The claim that one connection is sufficient is wrong because the Claude API does not manage client concurrency server-side in a way that lets a single connection submit 500 requests per minute with sub-second scheduling; client-side concurrency management is required. The claim that 500 concurrent connections are needed is wrong because that is a severe over-provision; connections do not need to be held open for the duration of a request in the standard HTTP API pattern, and far fewer concurrent connections can sustain 500 requests per minute. The claim that the throughput requirement cannot be met with the Claude API is wrong because 500 articles per minute with about 20 concurrent connections is well within the Claude API's technical capability at appropriate rate limit tiers, so on-premises model deployment is not required.