
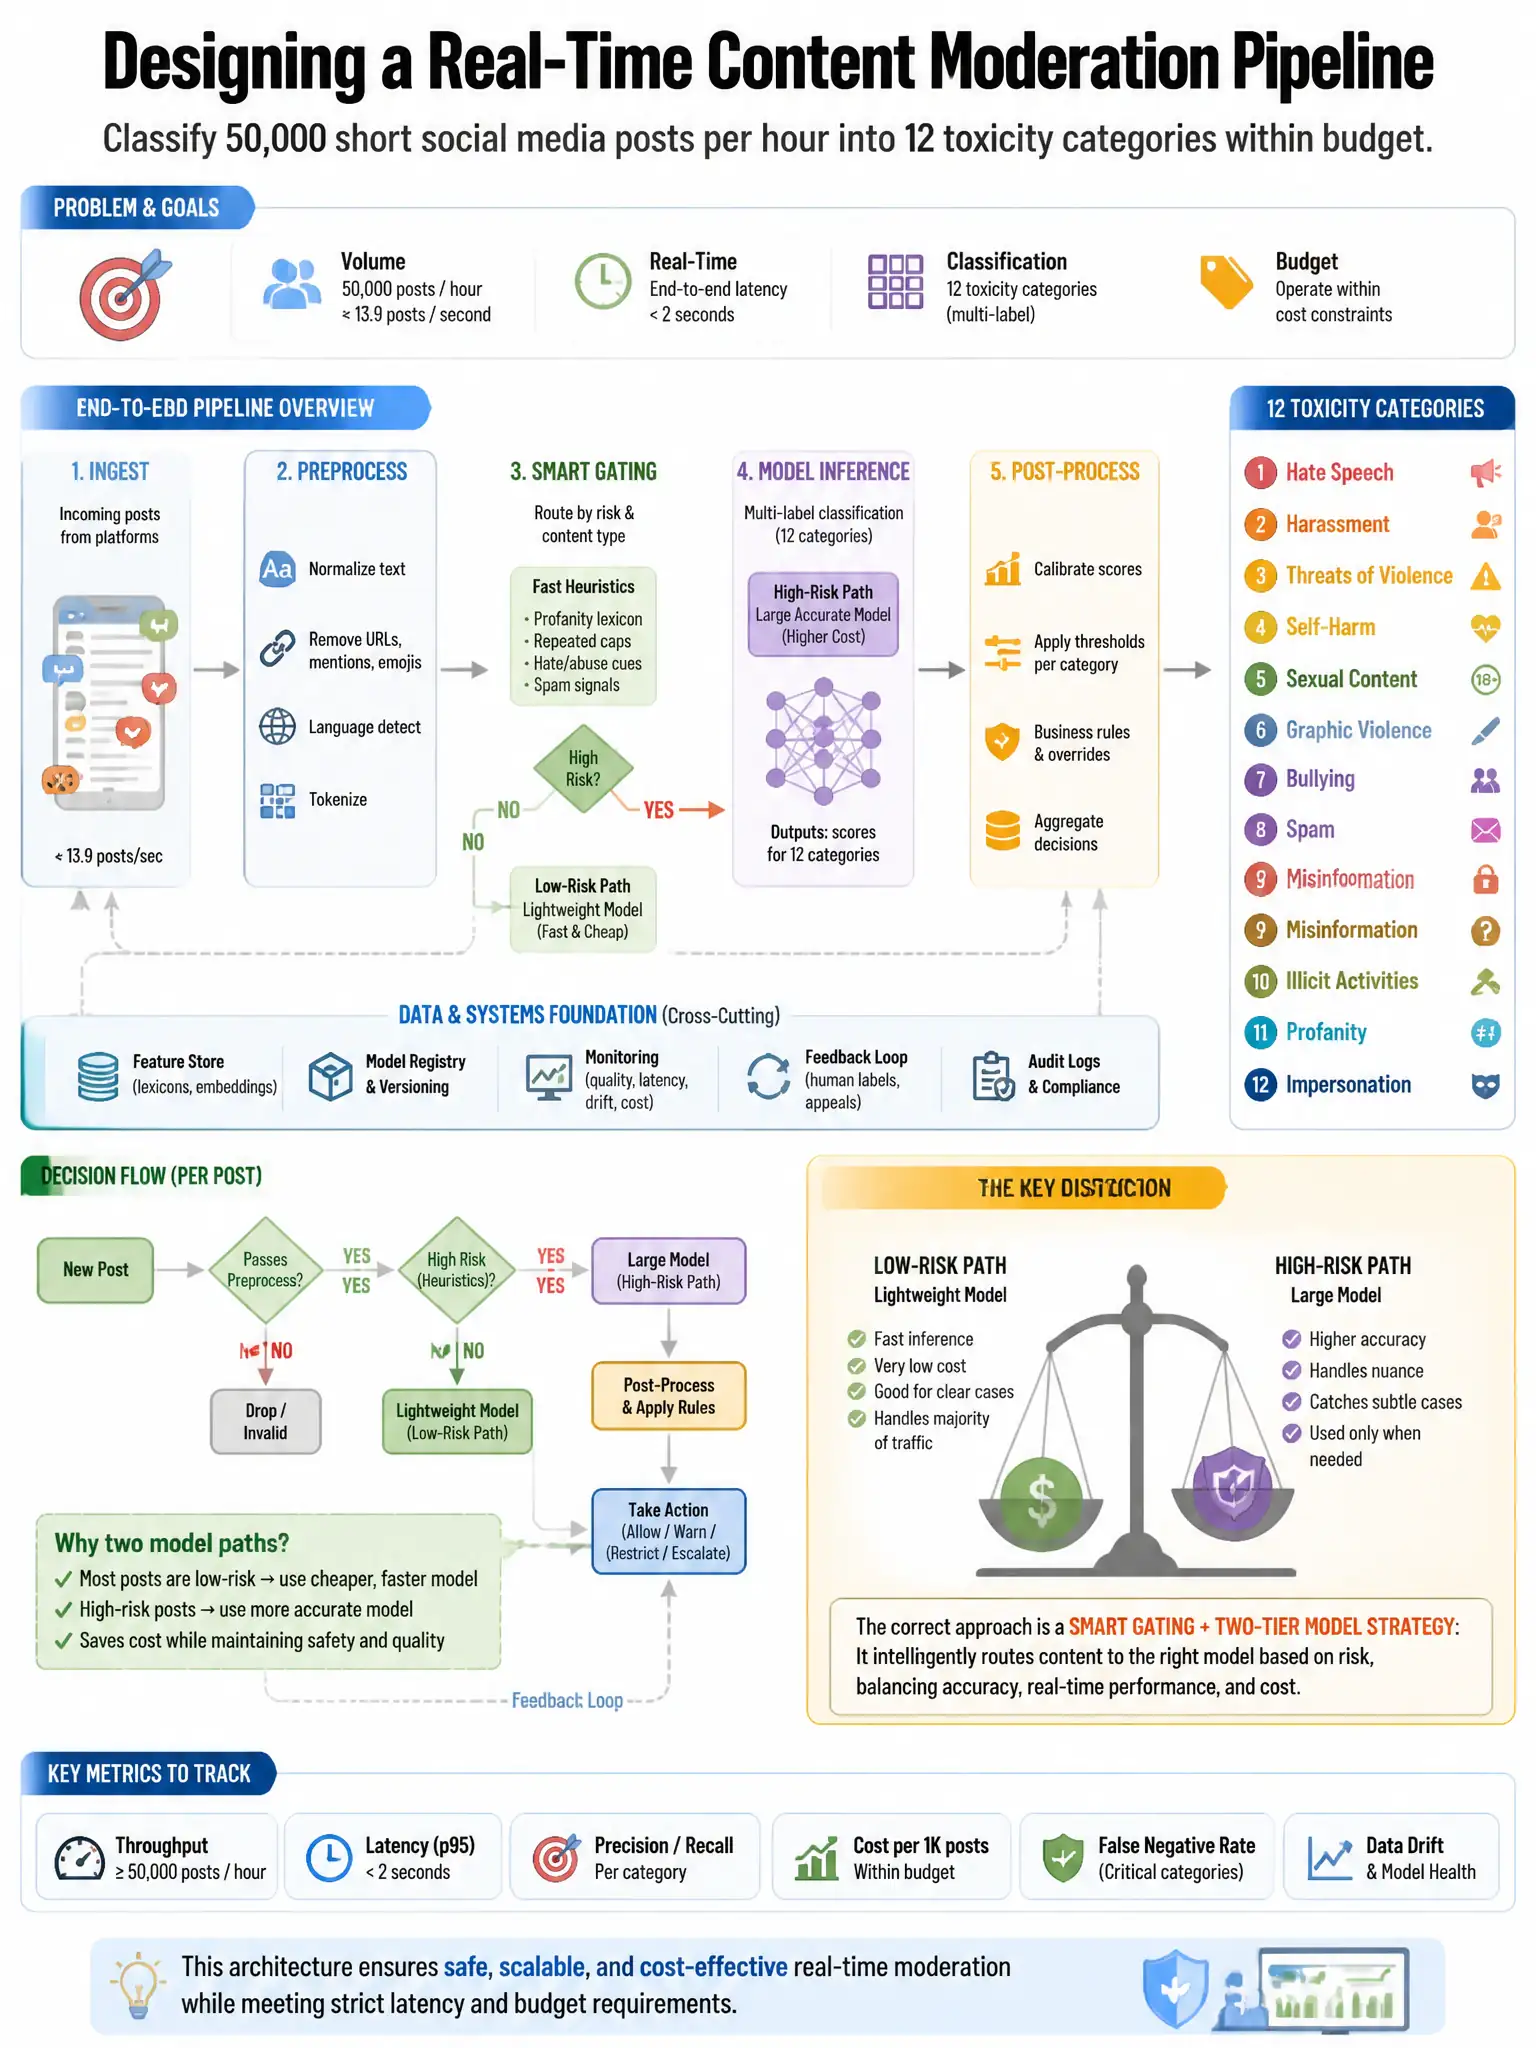
An architect is designing a real-time content moderation pipeline that must classify 50,000 short social media posts per hour into 12 toxicity categories. The system has a budget constraint of $0.50 per 1,000 posts and a latency requirement of under 500ms per classification. Which deployment pattern best fits these constraints?
Select an answer to reveal the explanation.
Short Explanation
You need the high-volume, low-latency model here: claude-3-haiku with a structured system prompt, JSON schema, and concurrent worker pools. It fits the $0.50 per 1,000 posts budget and the sub-500ms latency target while keeping classification consistent.
Full Explanation
The correct deployment pattern is claude-3-haiku with a tightly structured system prompt containing the 12-category taxonomy and a JSON output schema, deployed with concurrent worker pools to meet throughput. Claude-3-haiku is purpose-built for high-volume, low-latency classification tasks. Its cost profile and sub-second latency make it well-suited for the 50K/hour throughput at $0.50 per 1,000 posts. The structured taxonomy in the system prompt with JSON schema output maximizes consistency. Concurrent worker pools horizontally scale to throughput requirements. The claude-3-5-sonnet option with 100 posts batched per API call in a single prompt is wrong because batching makes attribution of classifications back to individual posts ambiguous and does not address latency at 500ms for Sonnet. The claude-3-5-haiku option with extended thinking enabled is wrong because extended thinking adds significant latency and cost, directly violating the 500ms requirement, and is unnecessary for structured classification. The claude-3-opus option with a keyword pre-filter is wrong because Opus far exceeds the cost budget and the keyword pre-filter introduces precision/recall tradeoffs that undermine the classification system's purpose.