
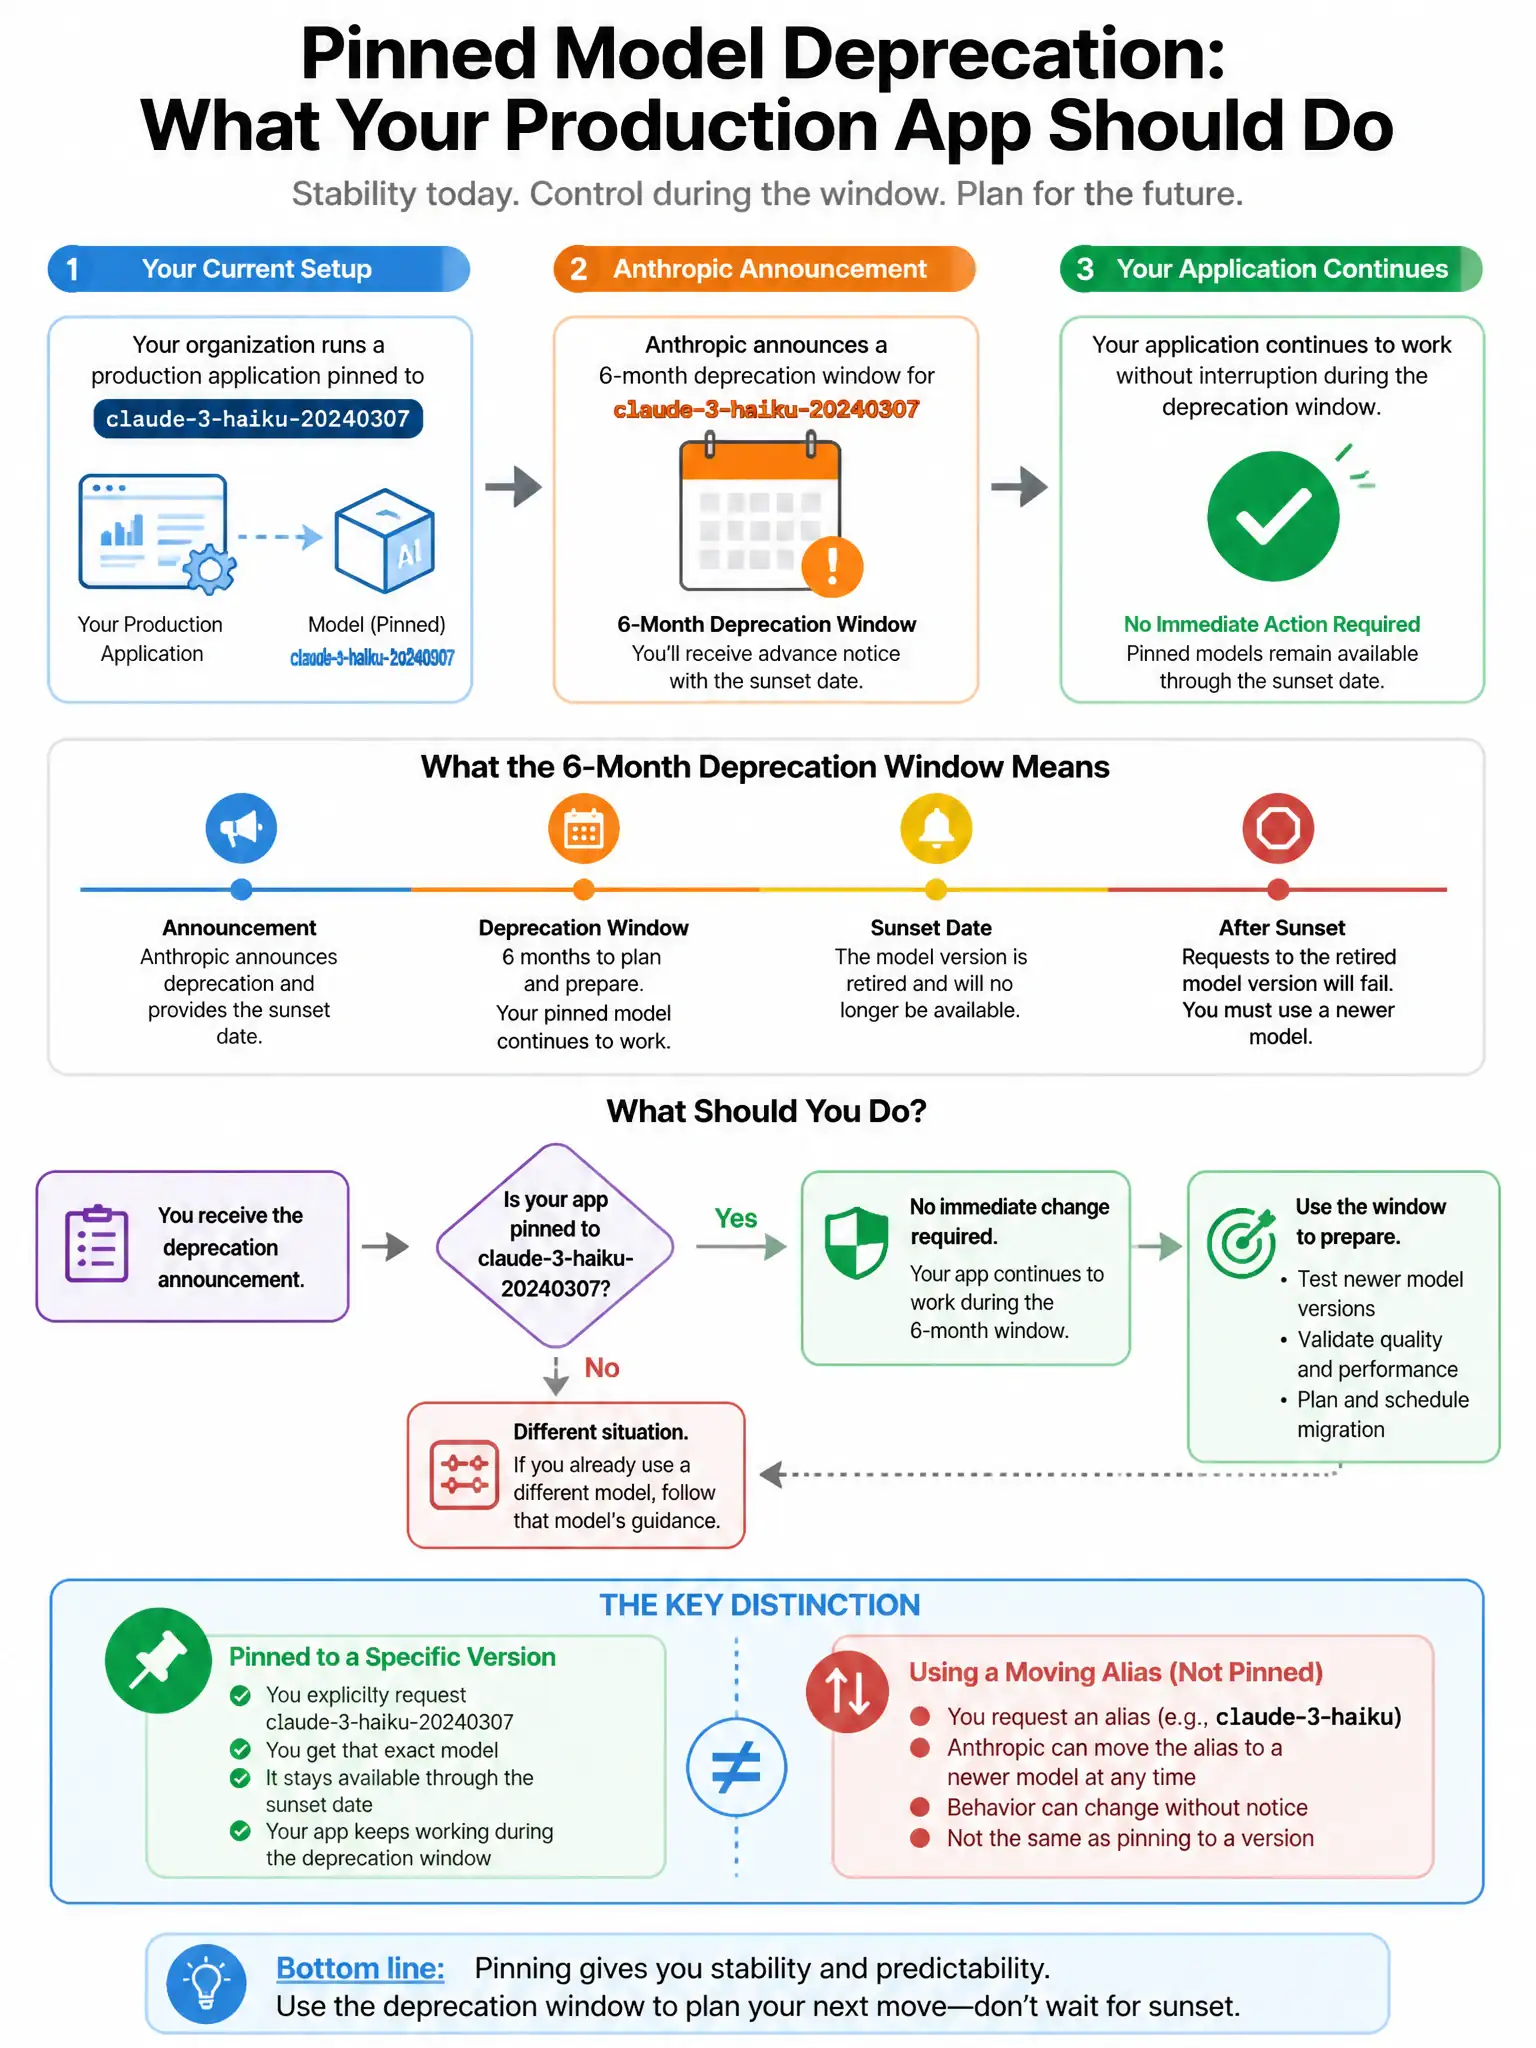
Your organization runs a production application pinned to claude-3-haiku-20240307. Anthropic announces a 6-month deprecation window for this model version. Your application processes 2 million classification requests per day with strict latency SLAs. What is the most operationally sound deprecation migration strategy?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need shadow traffic testing to compare output distributions statistically before moving production traffic. That catches behavioral regressions without risking latency SLAs. Then you shift traffic in stages with automated rollback triggers.
Full Explanation
The correct strategy is the shadow traffic pipeline that routes a small percentage of live requests to the successor model, compares output distributions statistically, and then performs a staged traffic shift with automated rollback triggers. Shadow traffic testing with statistical comparison of output distributions identifies behavioral regressions without risking production SLAs. Staged rollout with automated rollback triggers is the industry-standard approach for high-volume, latency-sensitive migration. The immediate migration to the latest claude-3-5-haiku model with both versions running in parallel for 30 days is wrong because the 30-day window is arbitrary and does not validate output consistency statistically; it adds cost without structured evaluation. Waiting until deprecation and relying on automatic forwarding to the replacement model is wrong because automatic forwarding is not guaranteed, and assuming classification backward compatibility at 2M requests per day is a dangerous operational gamble that violates the principle of validating before relying on. Pinning all requests to the model alias claude-haiku-latest is wrong because that alias is not a supported API alias; Anthropic's API requires explicit version strings, so this approach would fail at the API call level.