
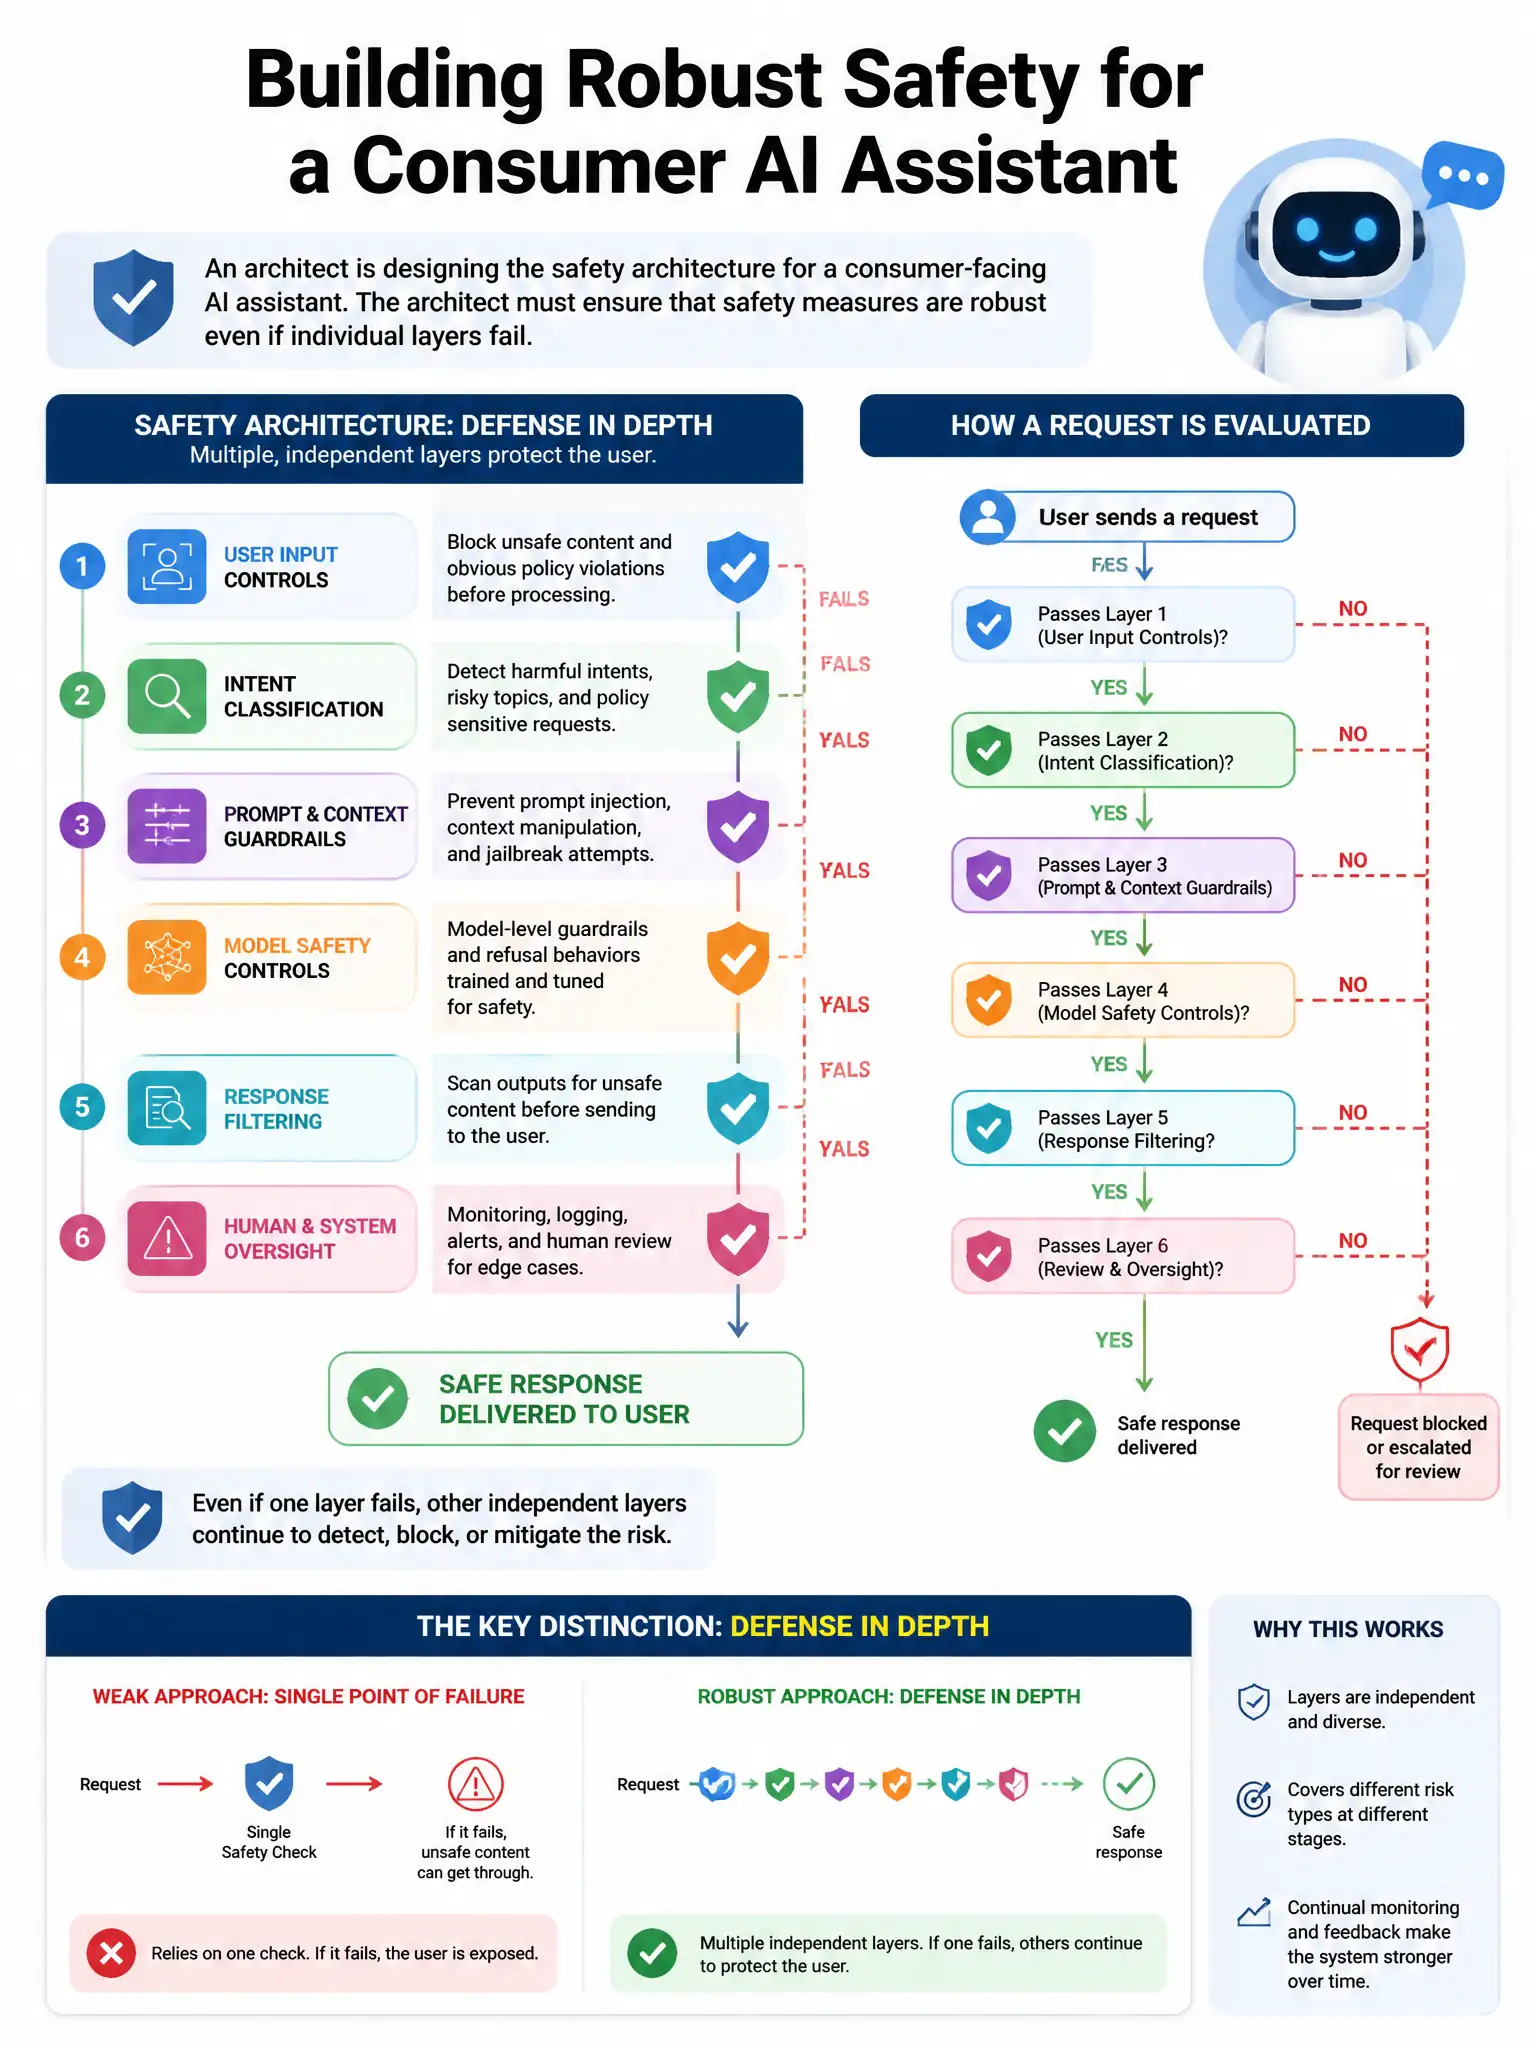
An architect is designing the safety architecture for a consumer-facing AI assistant. The architect must ensure that safety measures are robust even if individual layers fail. Which layered safety stack design is most comprehensive?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need independent safety layers that cover each other's blind spots: catch harmful requests before Claude sees them, use Claude's constitutional training for nuanced judgment, scan outputs before delivery, and route flagged cases to human review. Each layer compensates for failure modes of others.
Full Explanation
The three-layer stack design — pre-processing input classifier that detects harmful request categories before Claude sees them, Claude's constitutional safety training as primary behavioral layer, post-processing output classifier that scans generated content before delivery to users, plus human review workflows for flagged content — is correct because defense-in-depth for artificial-intelligence safety requires independent layers that each provide coverage the others may miss: pre-processing classifiers can detect request types that trigger safety concerns, such as jailbreak attempts and harmful categories, before they reach Claude; Claude's constitutional training handles nuanced judgment on ambiguous content; post-processing classifiers provide final gate for content that may have slipped through; human review provides escalation for uncertain cases. Each layer compensates for failure modes of others. Relying on Claude's built-in safety training as sole safety mechanism is wrong because it creates single point of failure — safety training is not perfect, and adversarial inputs can bypass it; defense requires independent layers. Implementing output filtering only, since Claude's safety training handles input-level issues, is wrong because output-only filtering misses opportunity to prevent harmful inputs from being processed at all, wastes compute on generating content that will be blocked, and misses input-level signals, such as attack-prompt structure. Using blocklist of harmful keywords applied at input and output layers, relying on Claude for everything else, is wrong because keyword blocklists are trivially bypassed through synonyms, spelling variations, and context — they provide weak coverage and high false positives; they can supplement but cannot substitute for behavioral layers.