
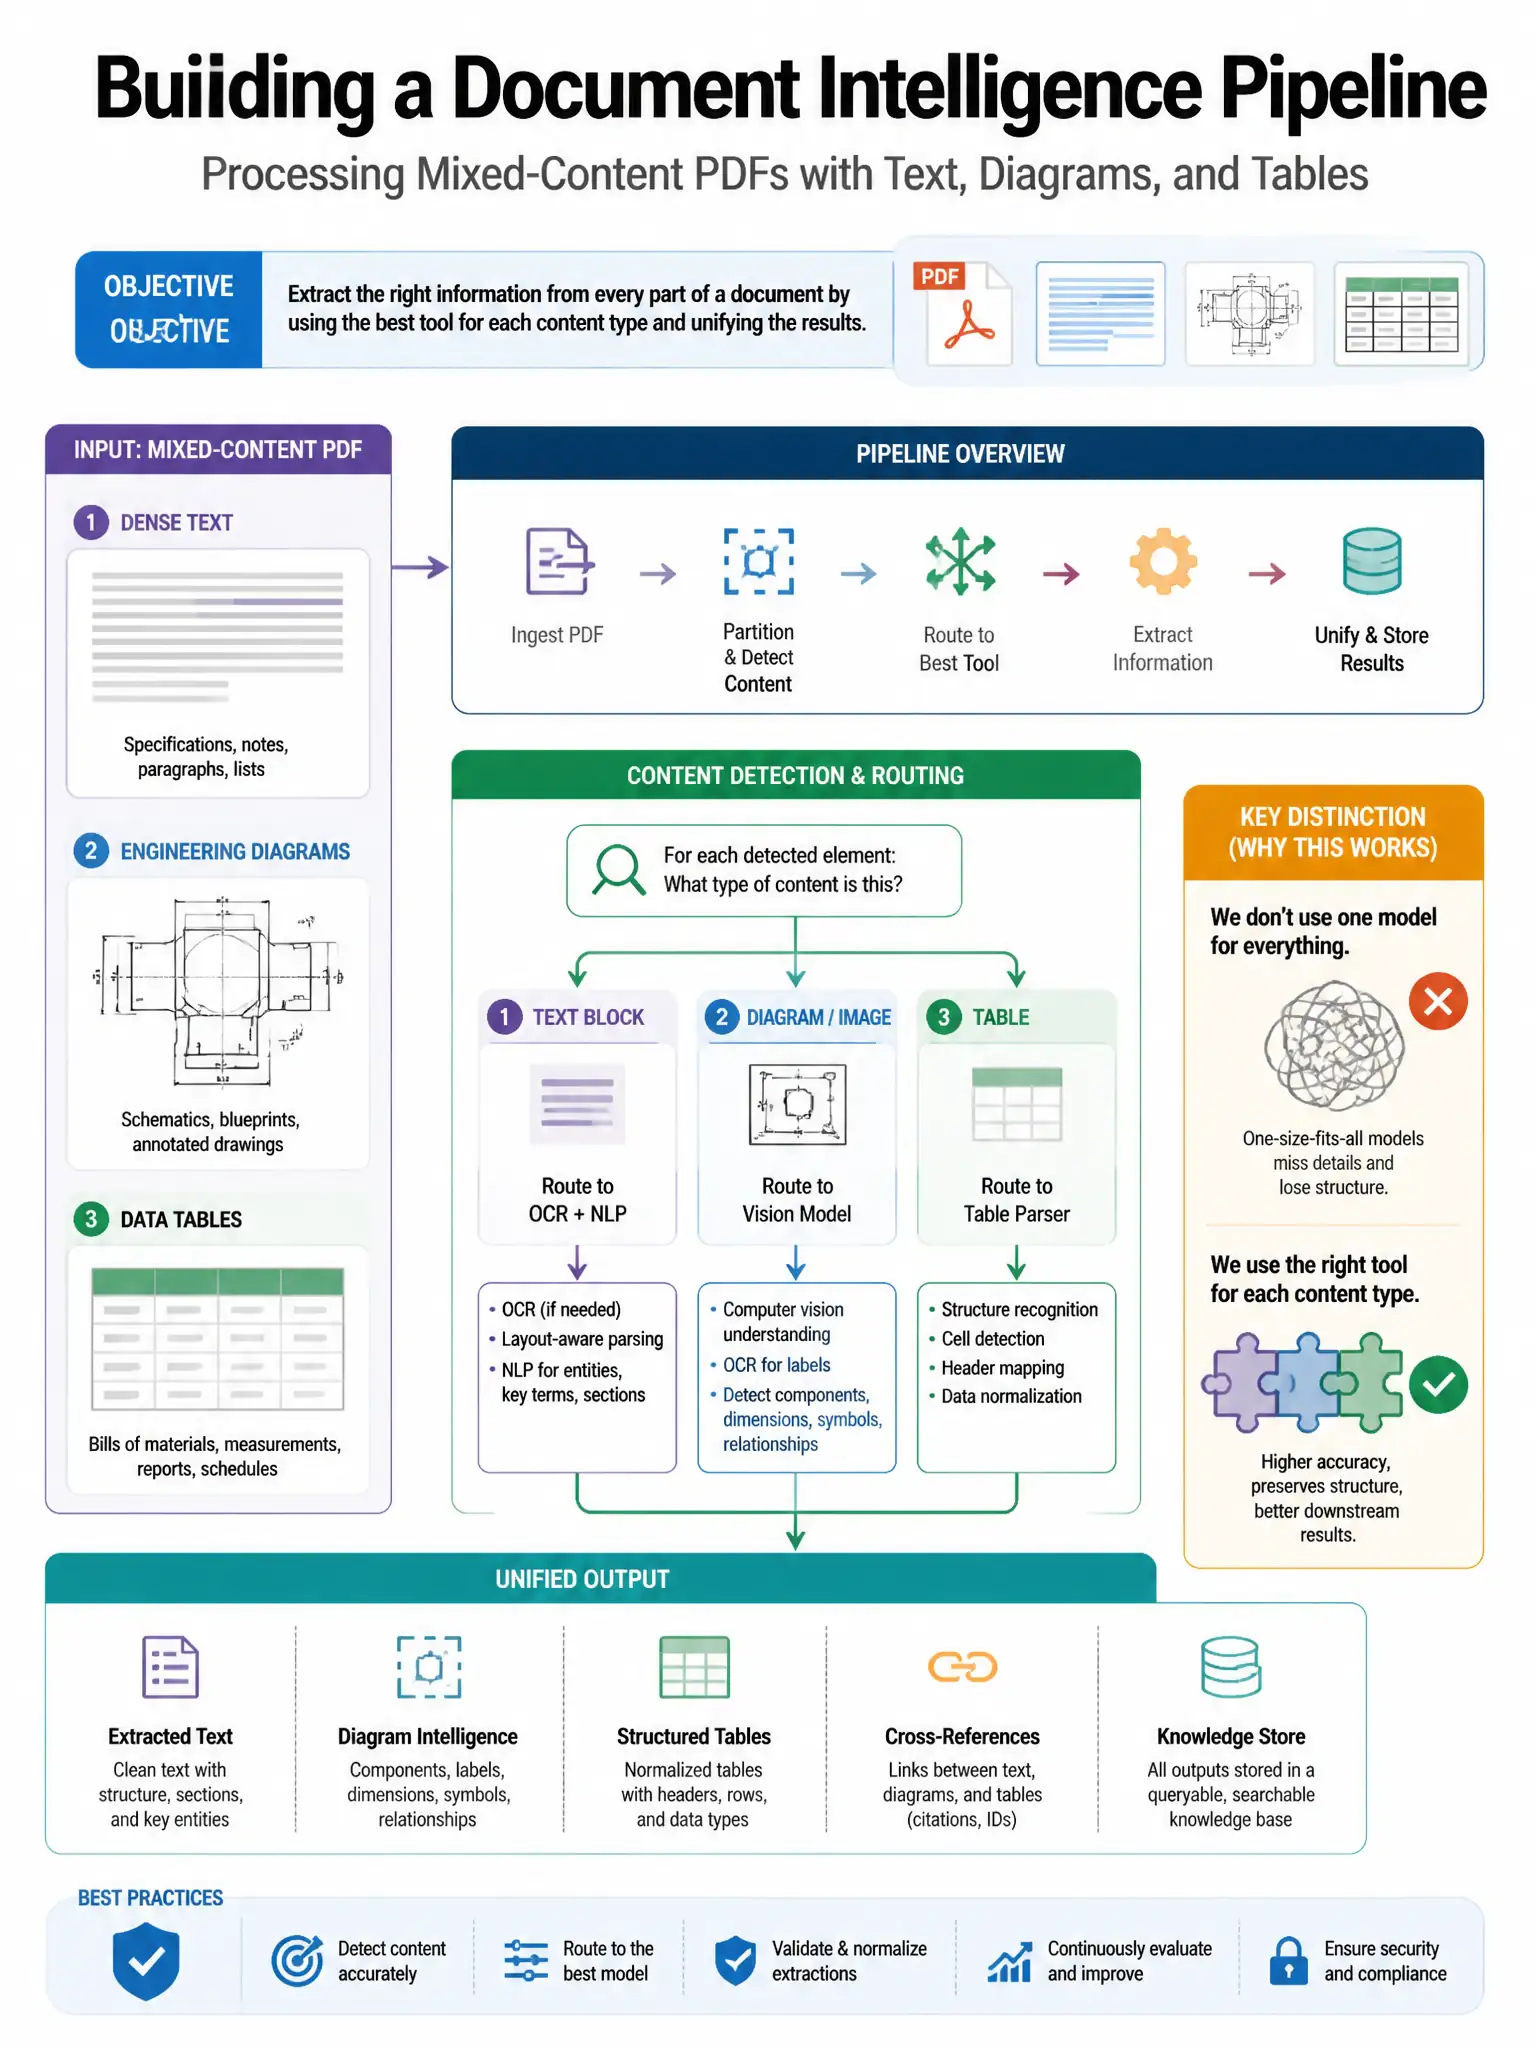
An architect is building a document intelligence pipeline that processes mixed-content PDFs containing dense technical text, engineering diagrams, and data tables. The system must extract structured data from all three content types with high accuracy. The PDFs are converted to images before processing. Which approach yields the best extraction accuracy?
Select an answer to reveal the explanation.
Short Explanation
You want the strongest multimodal model on the whole page, so send all page images to claude-3-5-sonnet. It handles dense text, diagrams, and tables together with high fidelity, which is exactly what mixed-content PDFs need.
Full Explanation
The best approach is to send all page images to claude-3-5-sonnet, because it has the strongest multimodal reasoning capability for complex mixed-content documents. It handles diagrams, tables, and dense technical text with high fidelity, and mixed-content pages often contain all three types together, making per-page classification fragile. The approach that sends all page images to claude-3-haiku is wrong because Haiku's vision capability is weaker on complex diagrams and structured tables, leading to higher extraction errors. The approach that pre-classifies pages by content type, routes diagram pages to claude-3-opus, and sends text pages to claude-3-haiku is wrong because page-level classification fails on mixed pages containing both text and diagrams simultaneously, and the routing overhead adds complexity. The approach that converts PDFs to text using OCR first, then sends the text-only representation to Claude for structured extraction is wrong because OCR loses spatial layout information critical for interpreting diagrams and the semantic structure of data tables; vision models can use visual context that OCR discards.