
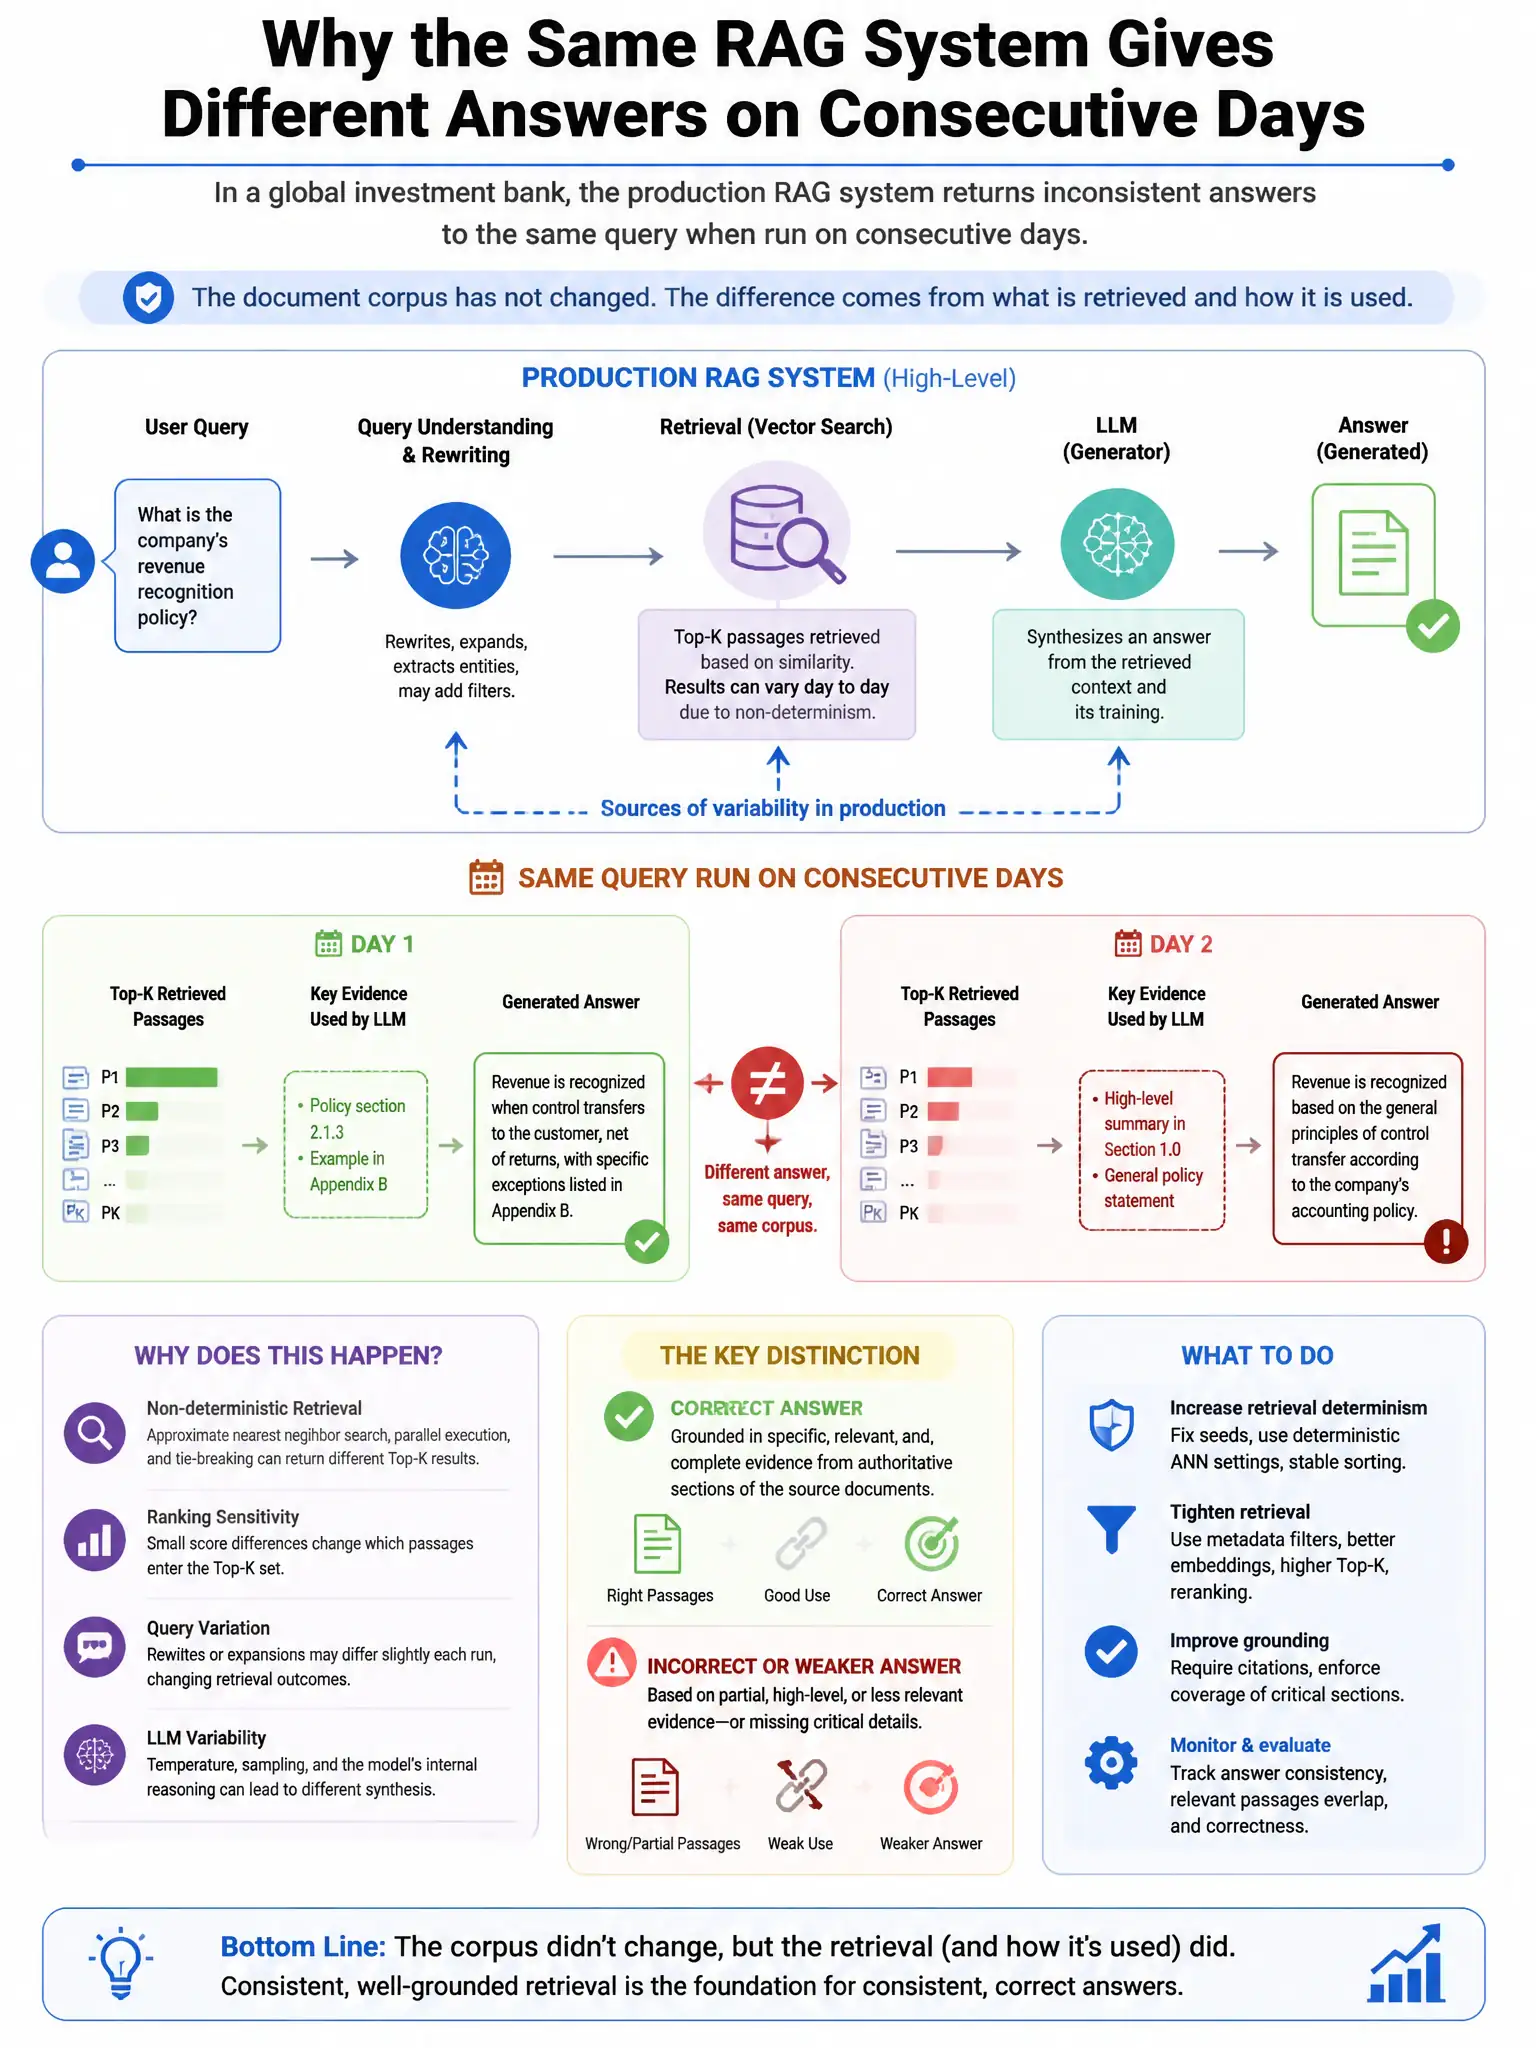
A global investment bank's production RAG system returns inconsistent answers to the same query when run on consecutive days. The underlying document corpus has not changed, and the query and retrieval parameters are identical. The engineering team's investigation reveals: (1) top-5 retrieved documents differ between runs, (2) vector similarity scores for the same document vary by ±0.03 between runs, (3) the embedding model version was updated two weeks ago with a minor patch. No other infrastructure changes occurred. What is the root cause and the correct architectural remediation?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — if you update the embedding model but don't re-embed the corpus, your documents and queries end up in different vector spaces. That breaks similarity scores and makes retrieval jump around. Re-embed everything with the current model to get consistent answers.
Full Explanation
An embedding model version update that changes embedding geometry is the root cause of retrieval inconsistency when the corpus hasn't changed. Embeddings generated by the pre-patch model and queries processed by the post-patch model exist in different geometric spaces — the vector distances no longer reflect semantic similarity accurately. The ±0.03 score variance for the same document reflects that post-patch query embeddings are positioned differently relative to pre-patch document embeddings. The fix is corpus re-embedding: every document must be re-processed through the updated embedding model to restore geometric consistency between documents and queries. This is a standard operational requirement when embedding model versions change. The approximate nearest neighbor explanation does not address score variance caused by embedding space misalignment — the same document with a misaligned embedding will still have inconsistent similarity to the query regardless of search algorithm determinism. The floating-point precision explanation papers over the symptom by including more candidates, but it doesn't fix the geometric inconsistency; answers derived from misaligned embeddings remain unreliable. The duplicate embeddings explanation addresses a different failure mode entirely — the ±0.03 variance on the same document is not explained by duplicate vectors.