
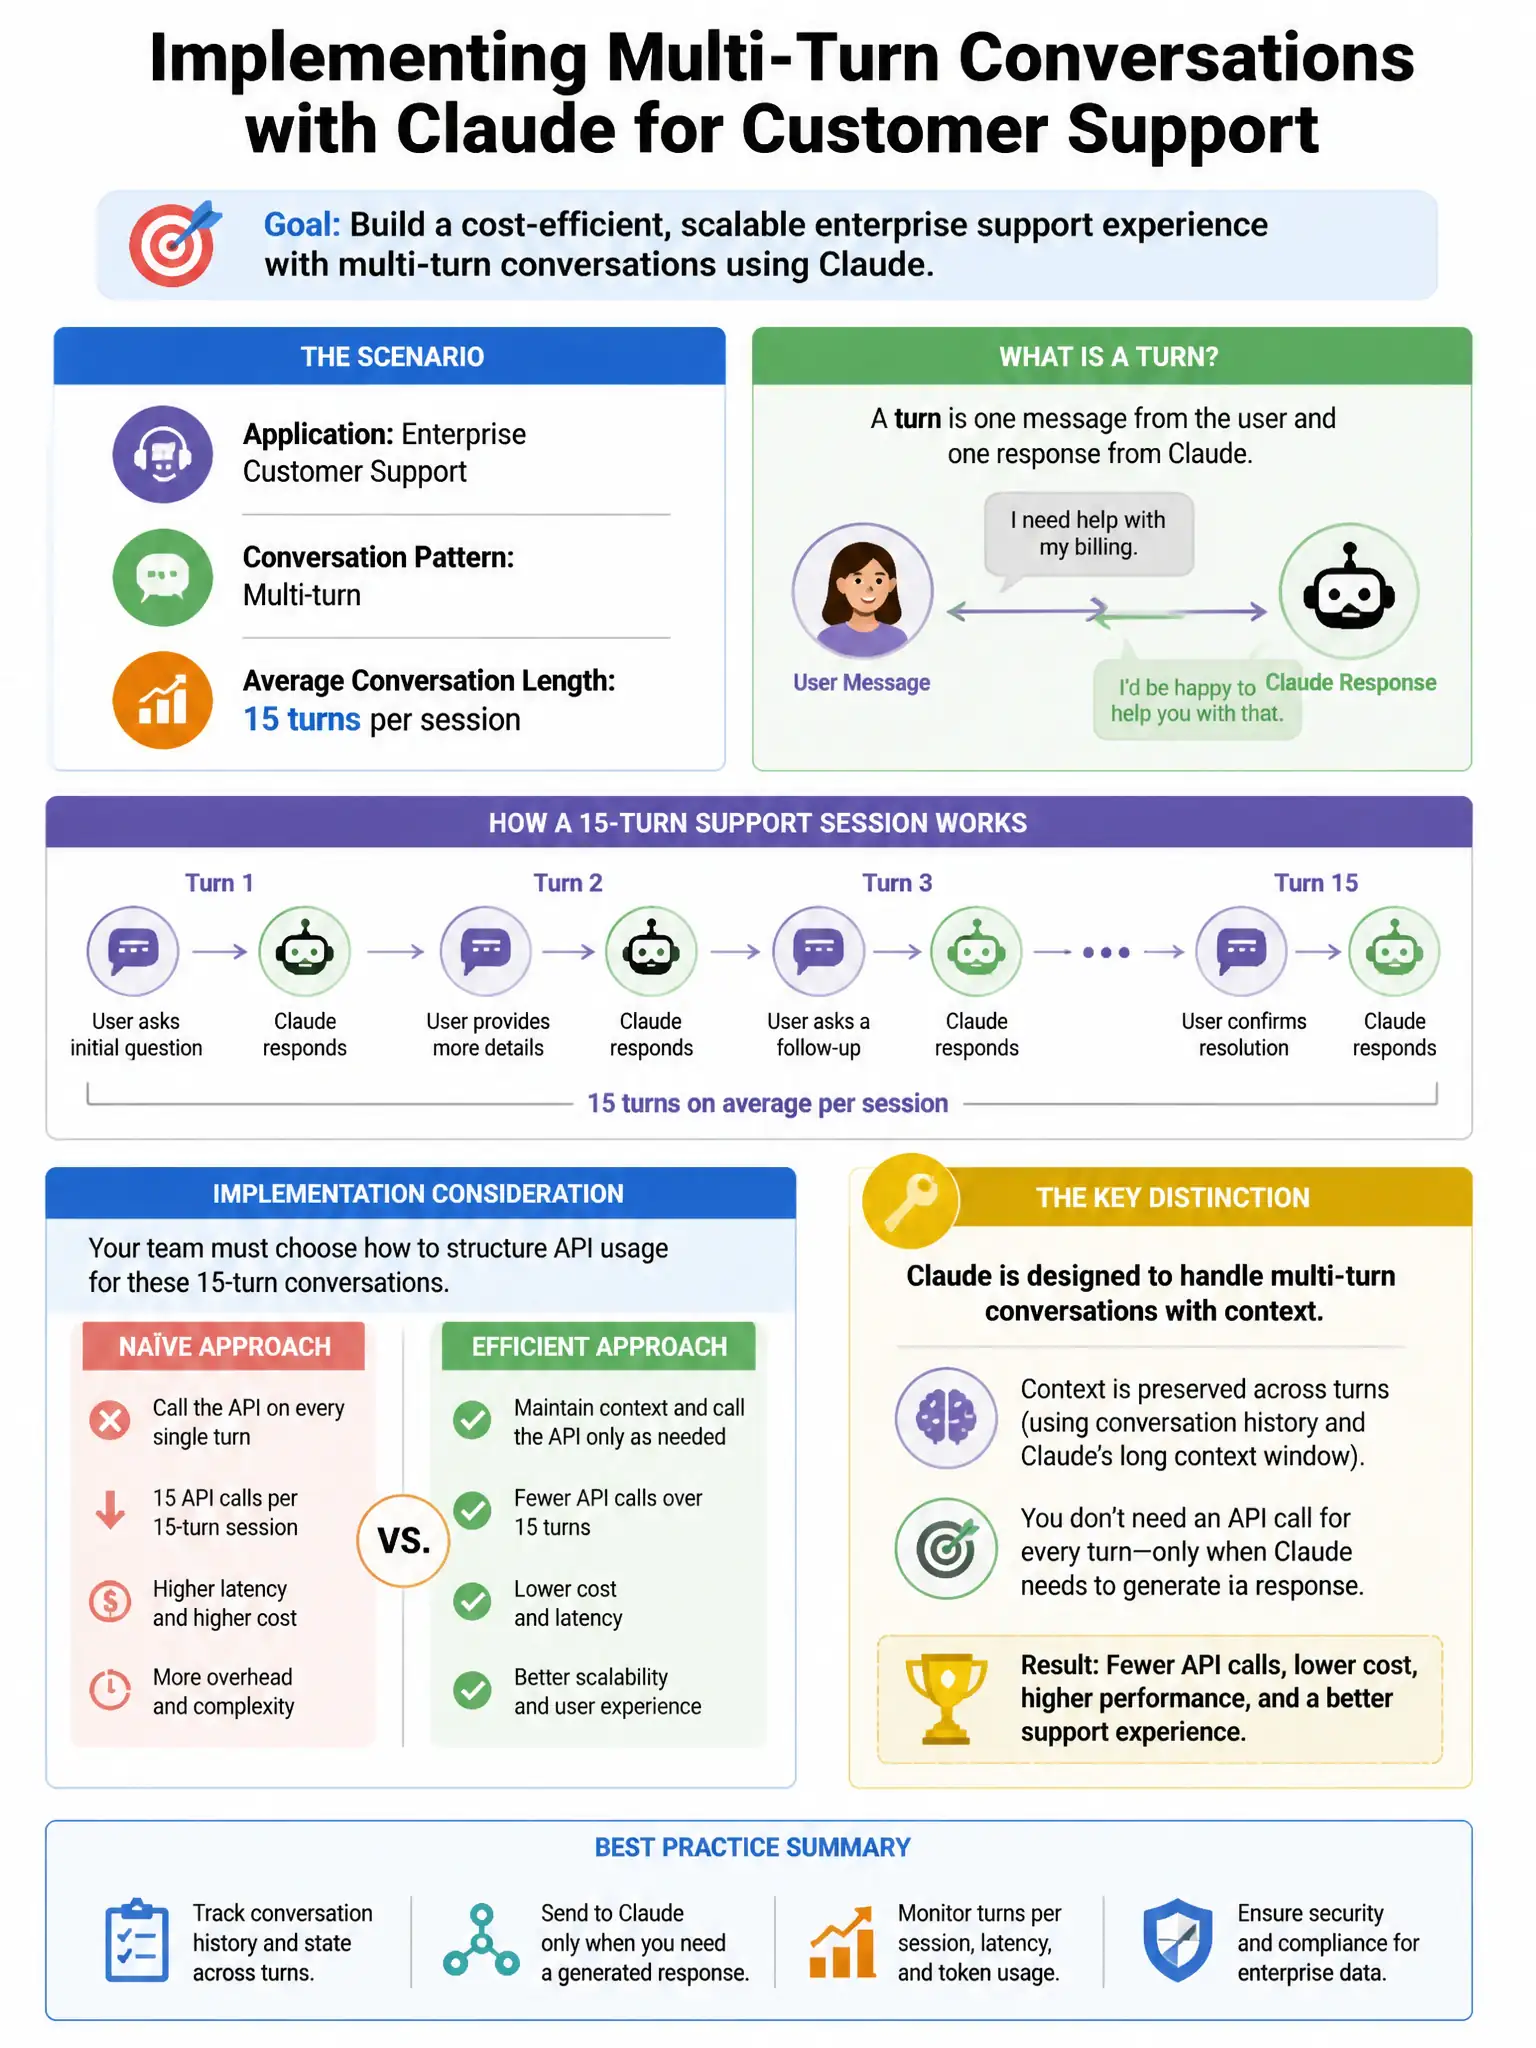
An enterprise platform needs to implement multi-turn conversation with Claude for a customer support application. Each support session averages 15 turns. The team's initial implementation re-sends the entire conversation history on every turn. At turn 15, the average input token count is 28,000 tokens. The platform serves 10,000 concurrent sessions. A senior engineer proposes storing conversation history server-side and implementing a turn-delta approach. However, the Claude API requires the full messages array. What is the correct optimization that reduces token costs without changing the conversational experience?
Select an answer to reveal the explanation.
Short Explanation
You want prompt caching on the conversation history prefix. In a multi-turn session, everything before the latest user message is identical across calls, so cache hits let you pay only for the new turn. That cuts redundant input processing without changing the conversation.
Full Explanation
Prompt caching on the conversation history prefix is the architecturally correct solution. For a multi-turn conversation, turns 1 through N-1 are identical in every API call within that session. By placing cache_control breakpoints at the end of the previous-turn content, all historical turns are served from cache, so you pay only for the new user message tokens as input, not for re-processing the entire conversation history. At turn 15 with 28,000 token histories, this eliminates about 26,000 tokens of redundant processing per turn. Cache hits are charged at about 10% of normal input token rates. The conversation summarization at turn 7 approach introduces a quality risk: the summary may omit details relevant to later turns, degrading resolution quality, and it requires an additional API call. The last-5-turn sliding window is too aggressive for support sessions that often reference earlier details, such as a customer saying that an account number was mentioned at the start, and it degrades resolution quality. The server-side compression approach that removes assistant reasoning preambles and filler phrases is fragile, computationally expensive, and the 30% savings claim is speculative; it also risks removing content that matters for coherence.