
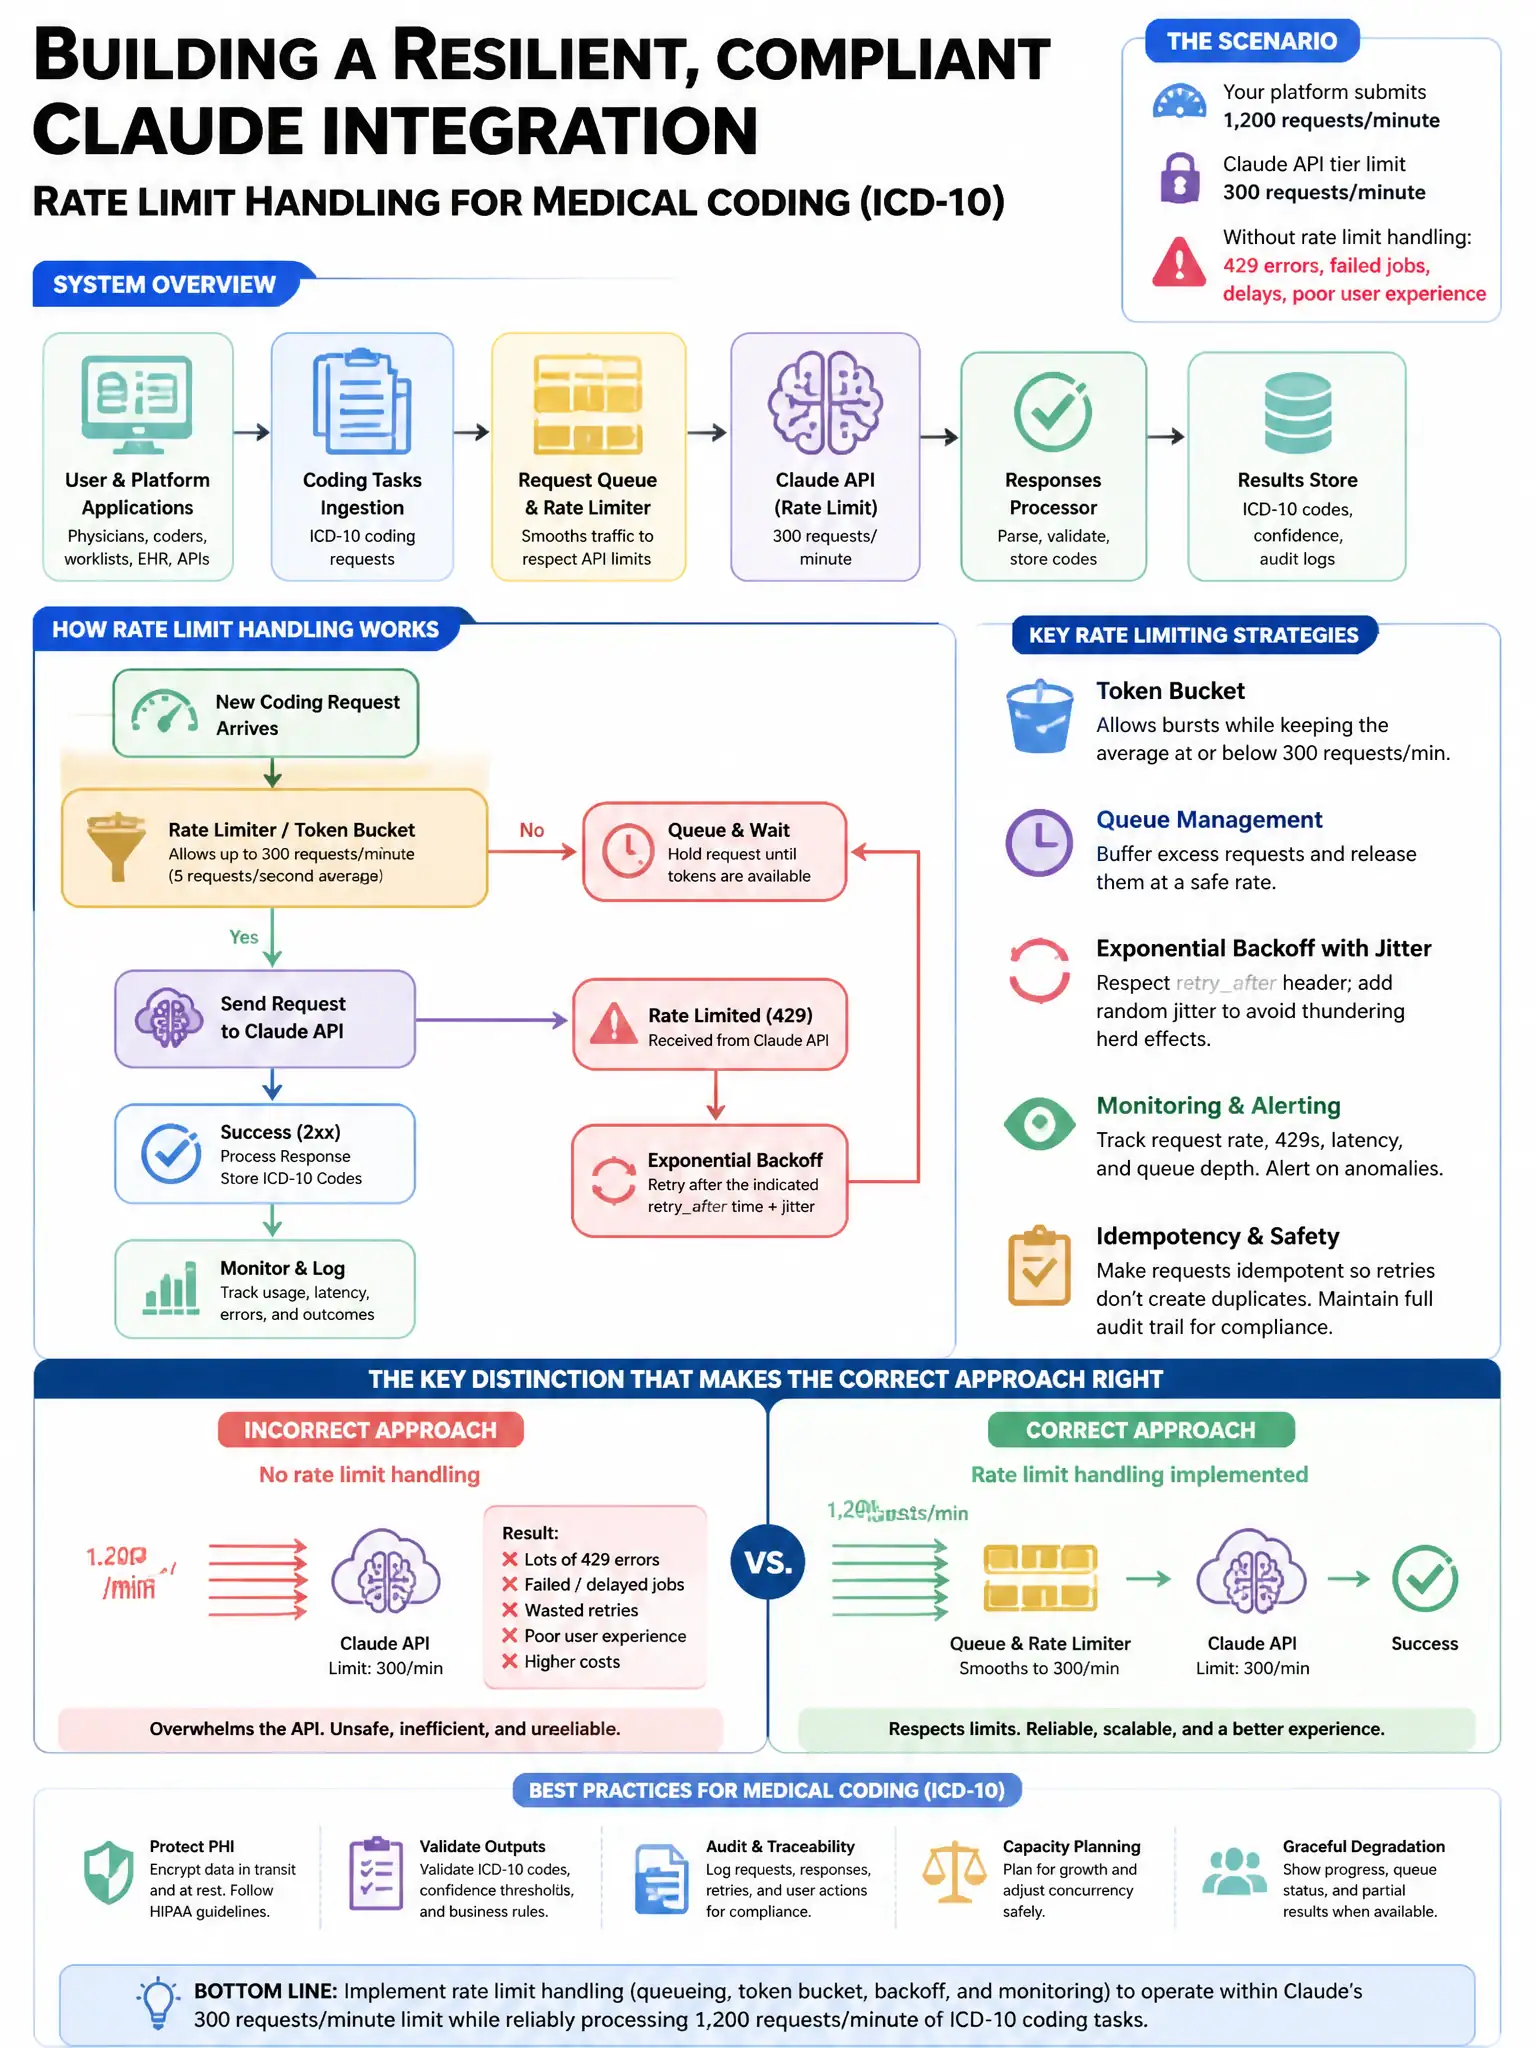
A platform must implement rate limit handling for a high-volume Claude integration processing medical coding (ICD-10) tasks. The system submits 1,200 requests/minute but the API tier allows 1,000 requests/minute and 100K tokens/minute. The engineering team implements token bucket rate limiting on their side with a 60-second refill window. During testing, they observe burst periods where 400 requests arrive within 10 seconds, exhausting the local token bucket and causing 429 errors that trigger unnecessary retries. Which rate limiting architecture prevents this pattern?
Select an answer to reveal the explanation.
Short Explanation
A leaky bucket smooths traffic at a steady rate, so bursts don't drain your whole budget in 10 seconds. You still keep the same average throughput while avoiding those 429 retries.
Full Explanation
The leaky bucket approach is architecturally correct for this problem. The core issue is that the token bucket allows bursts — a full bucket at 60-second intervals means 1,000 tokens are available simultaneously, enabling 400 requests to fire in 10 seconds. A leaky bucket enforces a constant output rate (1,000/60 ≈ 16.7 requests/second), preventing any burst from exhausting the budget. Requests are queued and drained at a fixed rate — exactly what a smoothing mechanism requires. The sliding-window approach with 10-second sub-window tracking is closer but more complex to implement correctly; it also allows some burst behavior within the 10-second window and requires accurate tracking of all requests in the sliding window across distributed instances. The more frequent token bucket refill approach partially addresses the problem but still allows micro-bursts within each 10-second window. The priority queue approach addresses request ordering but not rate limiting — it doesn't prevent the burst from exhausting the rate limit; it just determines which requests get submitted first when capacity is available.