
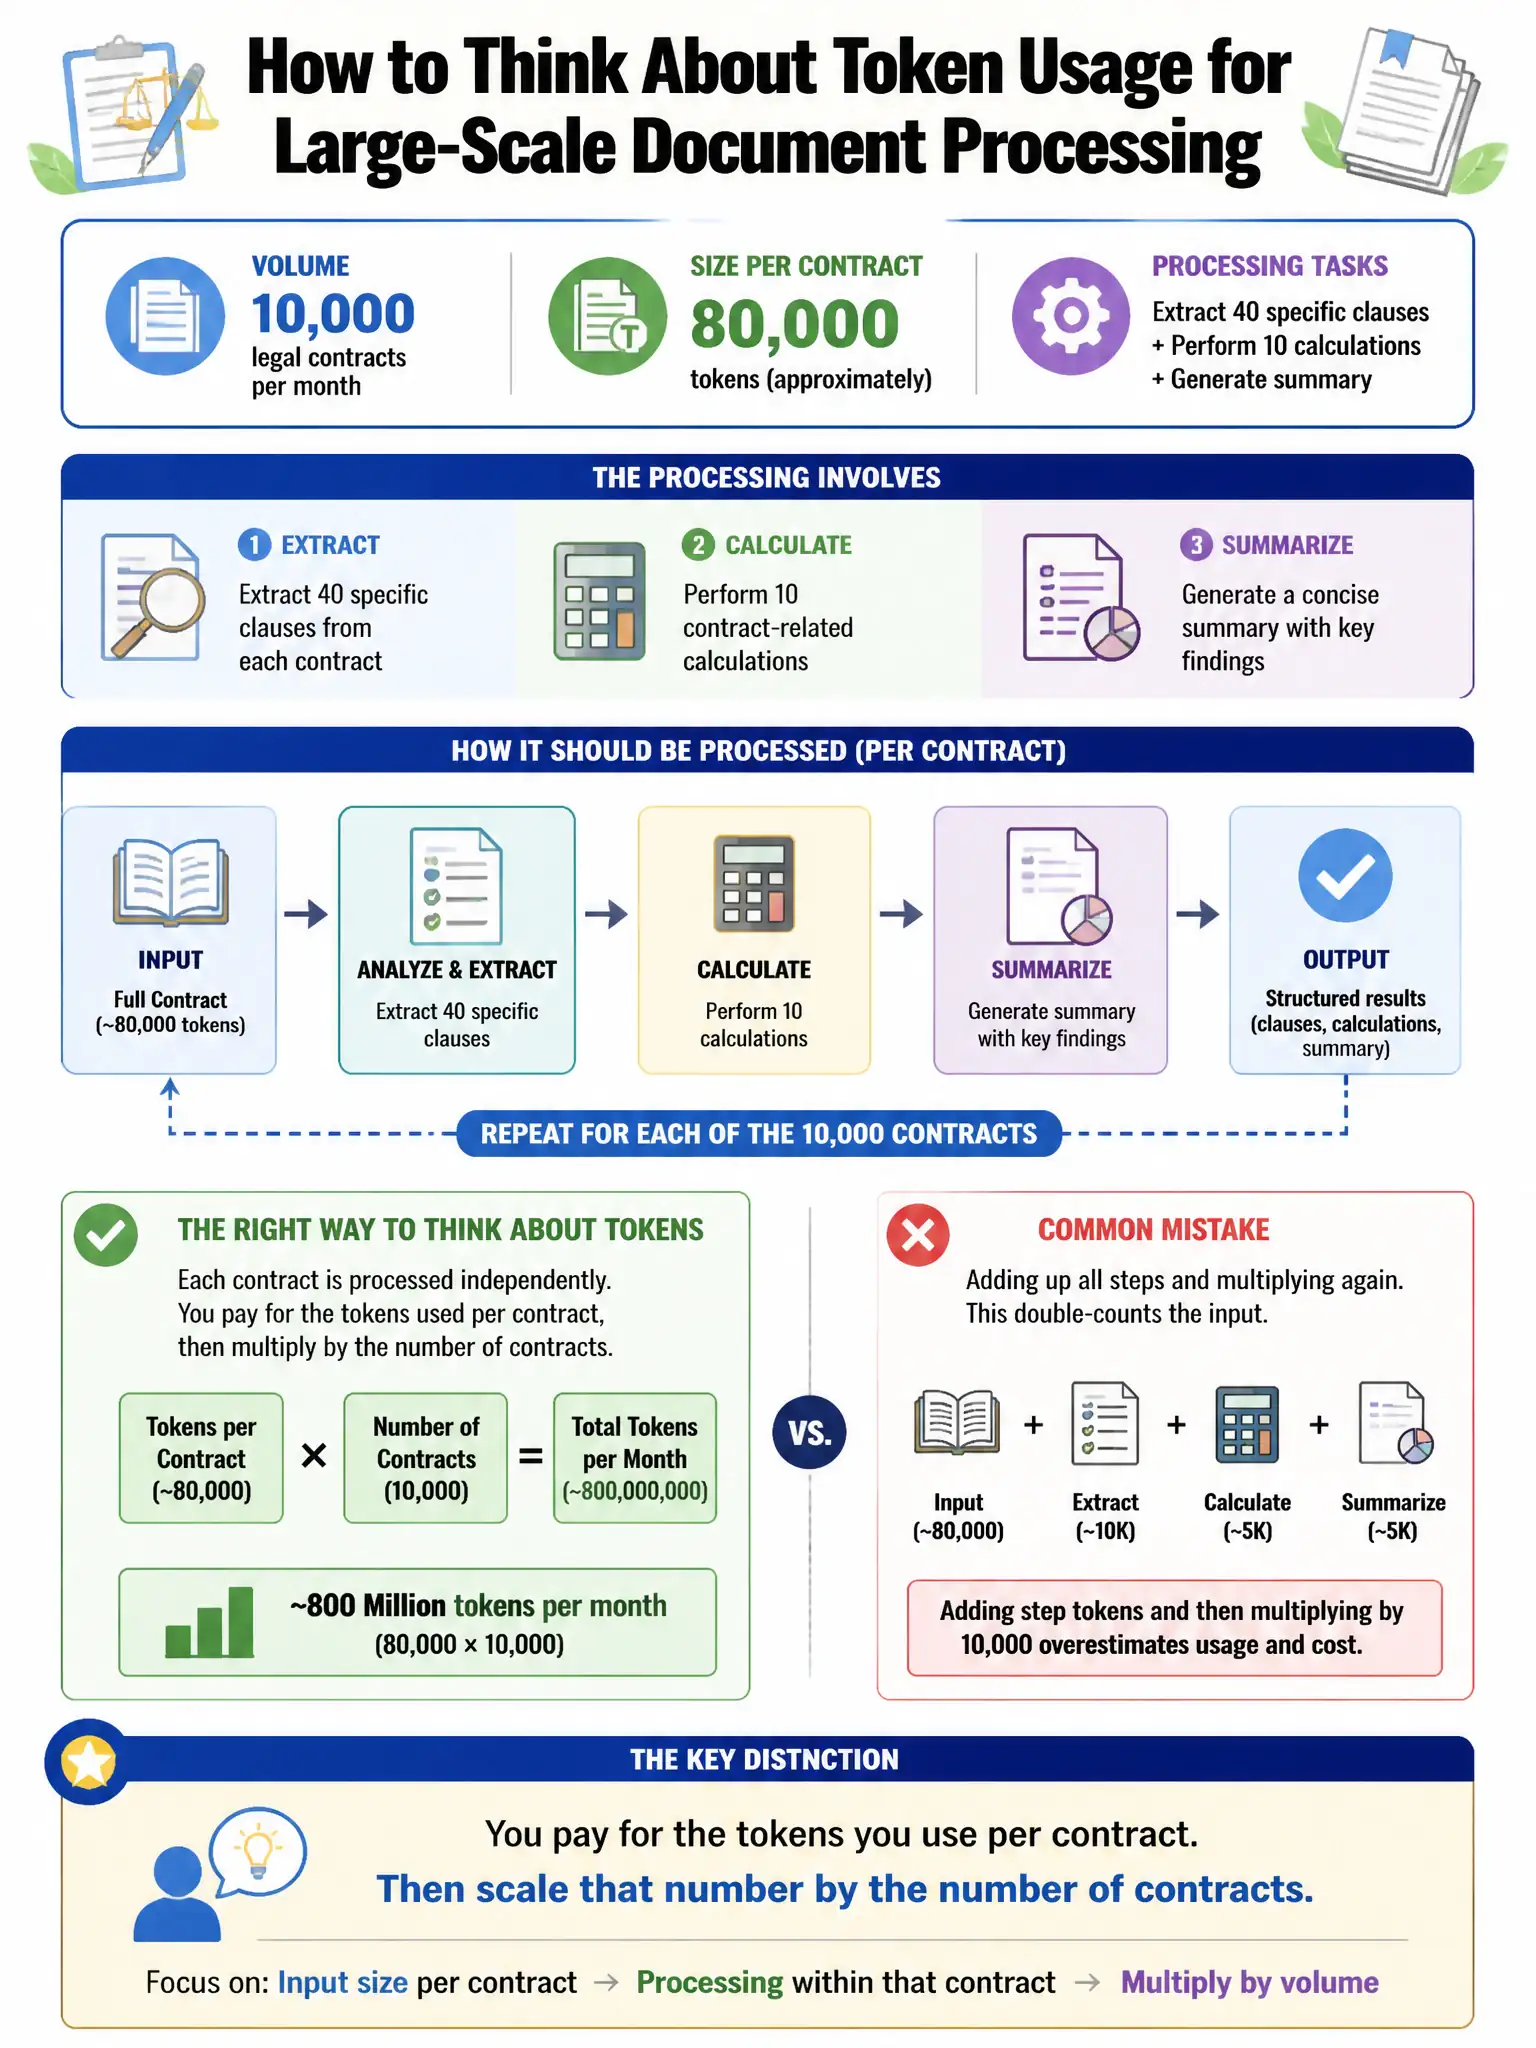
A financial services firm needs to process 10,000 legal contracts per month. Each contract is approximately 80,000 tokens. The processing involves: (1) extracting 40 specific clause types, (2) flagging regulatory non-compliance, and (3) generating a structured JSON summary. The firm's SLA requires 99.9% accuracy. Throughput is not time-critical — results are acceptable within 48 hours. The legal team reports that occasional hallucinations in clause extraction have caused $2M in downstream errors. Given these constraints, which model selection strategy is architecturally superior?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — when $2M hallucination errors and a 99.9% accuracy SLA are on the line, you need the highest-capability model plus a verification loop, not cost optimization. Running the full pipeline twice and comparing the JSON outputs catches stochastic errors that single-pass approaches miss. The 48-hour delivery window makes that dual-pass design practical.
Full Explanation
When $2M hallucination errors exist and 99.9% accuracy is the SLA, the architecturally superior strategy is the highest-capability model paired with a verification loop, not cost optimization. Using a top-tier model for the full pipeline and running each contract twice, then comparing the JSON outputs and escalating mismatches to human review, catches stochastic extraction errors that any single-pass approach misses. The 48-hour delivery window removes throughput pressure, making the dual-pass design feasible. The single-pass Claude 3.5 Sonnet approach to minimize API calls ignores verification. The Claude 3 Haiku extraction plus Claude 3 Opus summary routing introduces accuracy variance at the costly extraction stage. The Claude 3.5 Sonnet self-critique approach is flawed: self-critique by the same model is unreliable for factual extraction errors, because a model that hallucinates a clause is likely to validate its own hallucination.