
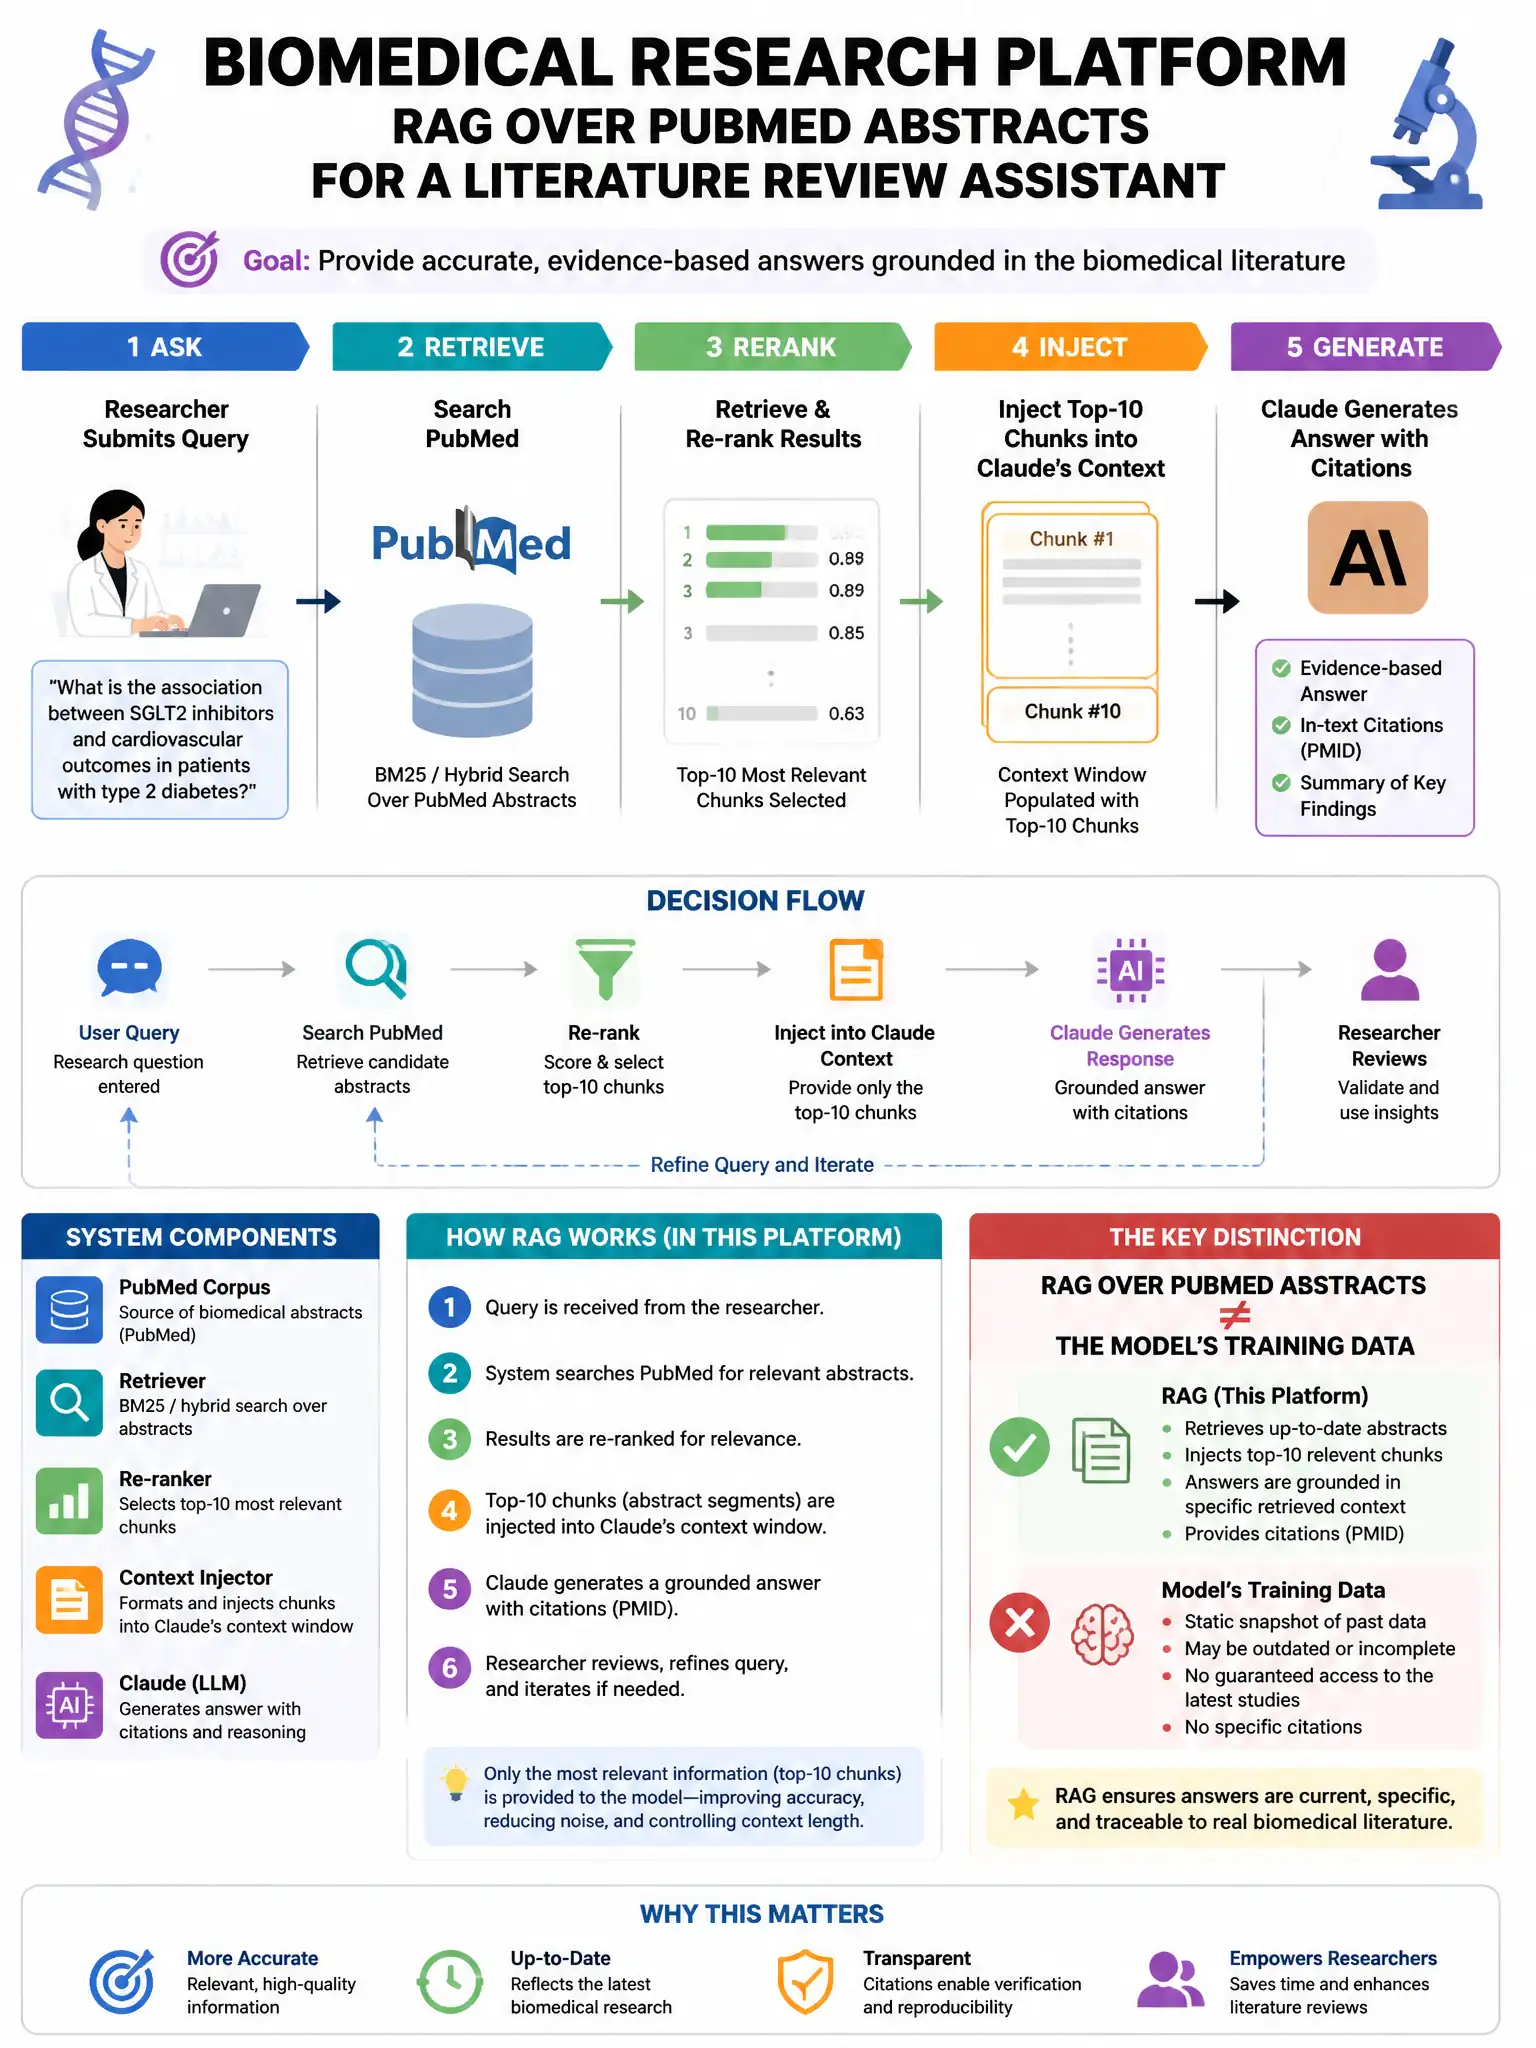
A biomedical research platform uses RAG over PubMed abstracts for a literature review assistant. The system retrieves top-10 chunks and injects them into Claude's context. Research scientists report that the assistant occasionally cites findings that are the opposite of what the retrieved paper says — for example, claiming a drug 'increases efficacy' when the abstract says it 'decreases adverse effects but does not affect efficacy.' What RAG architecture change most directly reduces citation hallucination?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you cut citation hallucination by making Claude quote the exact sentence before it claims anything. That pins every assertion to verbatim retrieved text, so a scientist can check it instantly and you don't get paraphrase drift like 'does not affect efficacy' turning into 'increases efficacy'.
Full Explanation
Citation hallucination in retrieval-augmented generation is most directly reduced by instructing Claude to quote the exact supporting sentence from the retrieved abstract before making any claim, then structuring the response to cite [Author, Year] with the verbatim quote as evidence. This grounds each assertion in specific retrieved text, making it immediately verifiable and preventing Claude from paraphrasing in ways that change meaning ('does not affect efficacy' becoming 'increases efficacy' is a paraphrasing error). The verbatim quote also enables users to spot when Claude has misinterpreted nuanced language. The approach that retrieves fewer chunks, such as top-3 instead of top-10, reduces context size but may exclude relevant papers, trading hallucination risk for recall quality — and doesn't address the paraphrasing problem in retrieved content. The approach that uses Claude to summarize each retrieved abstract before injection actually worsens the problem: summarization introduces another paraphrasing step that can alter meaning before the final synthesis call — the exact error described. The approach that implements a second-pass fact-check where a separate Claude instance is given the final answer and all retrieved abstracts and asked to flag any claim not directly supported by the retrieved text is a valid safety net but adds latency and cost, and the fact-checking instance may make the same interpretation error as the synthesis instance.