
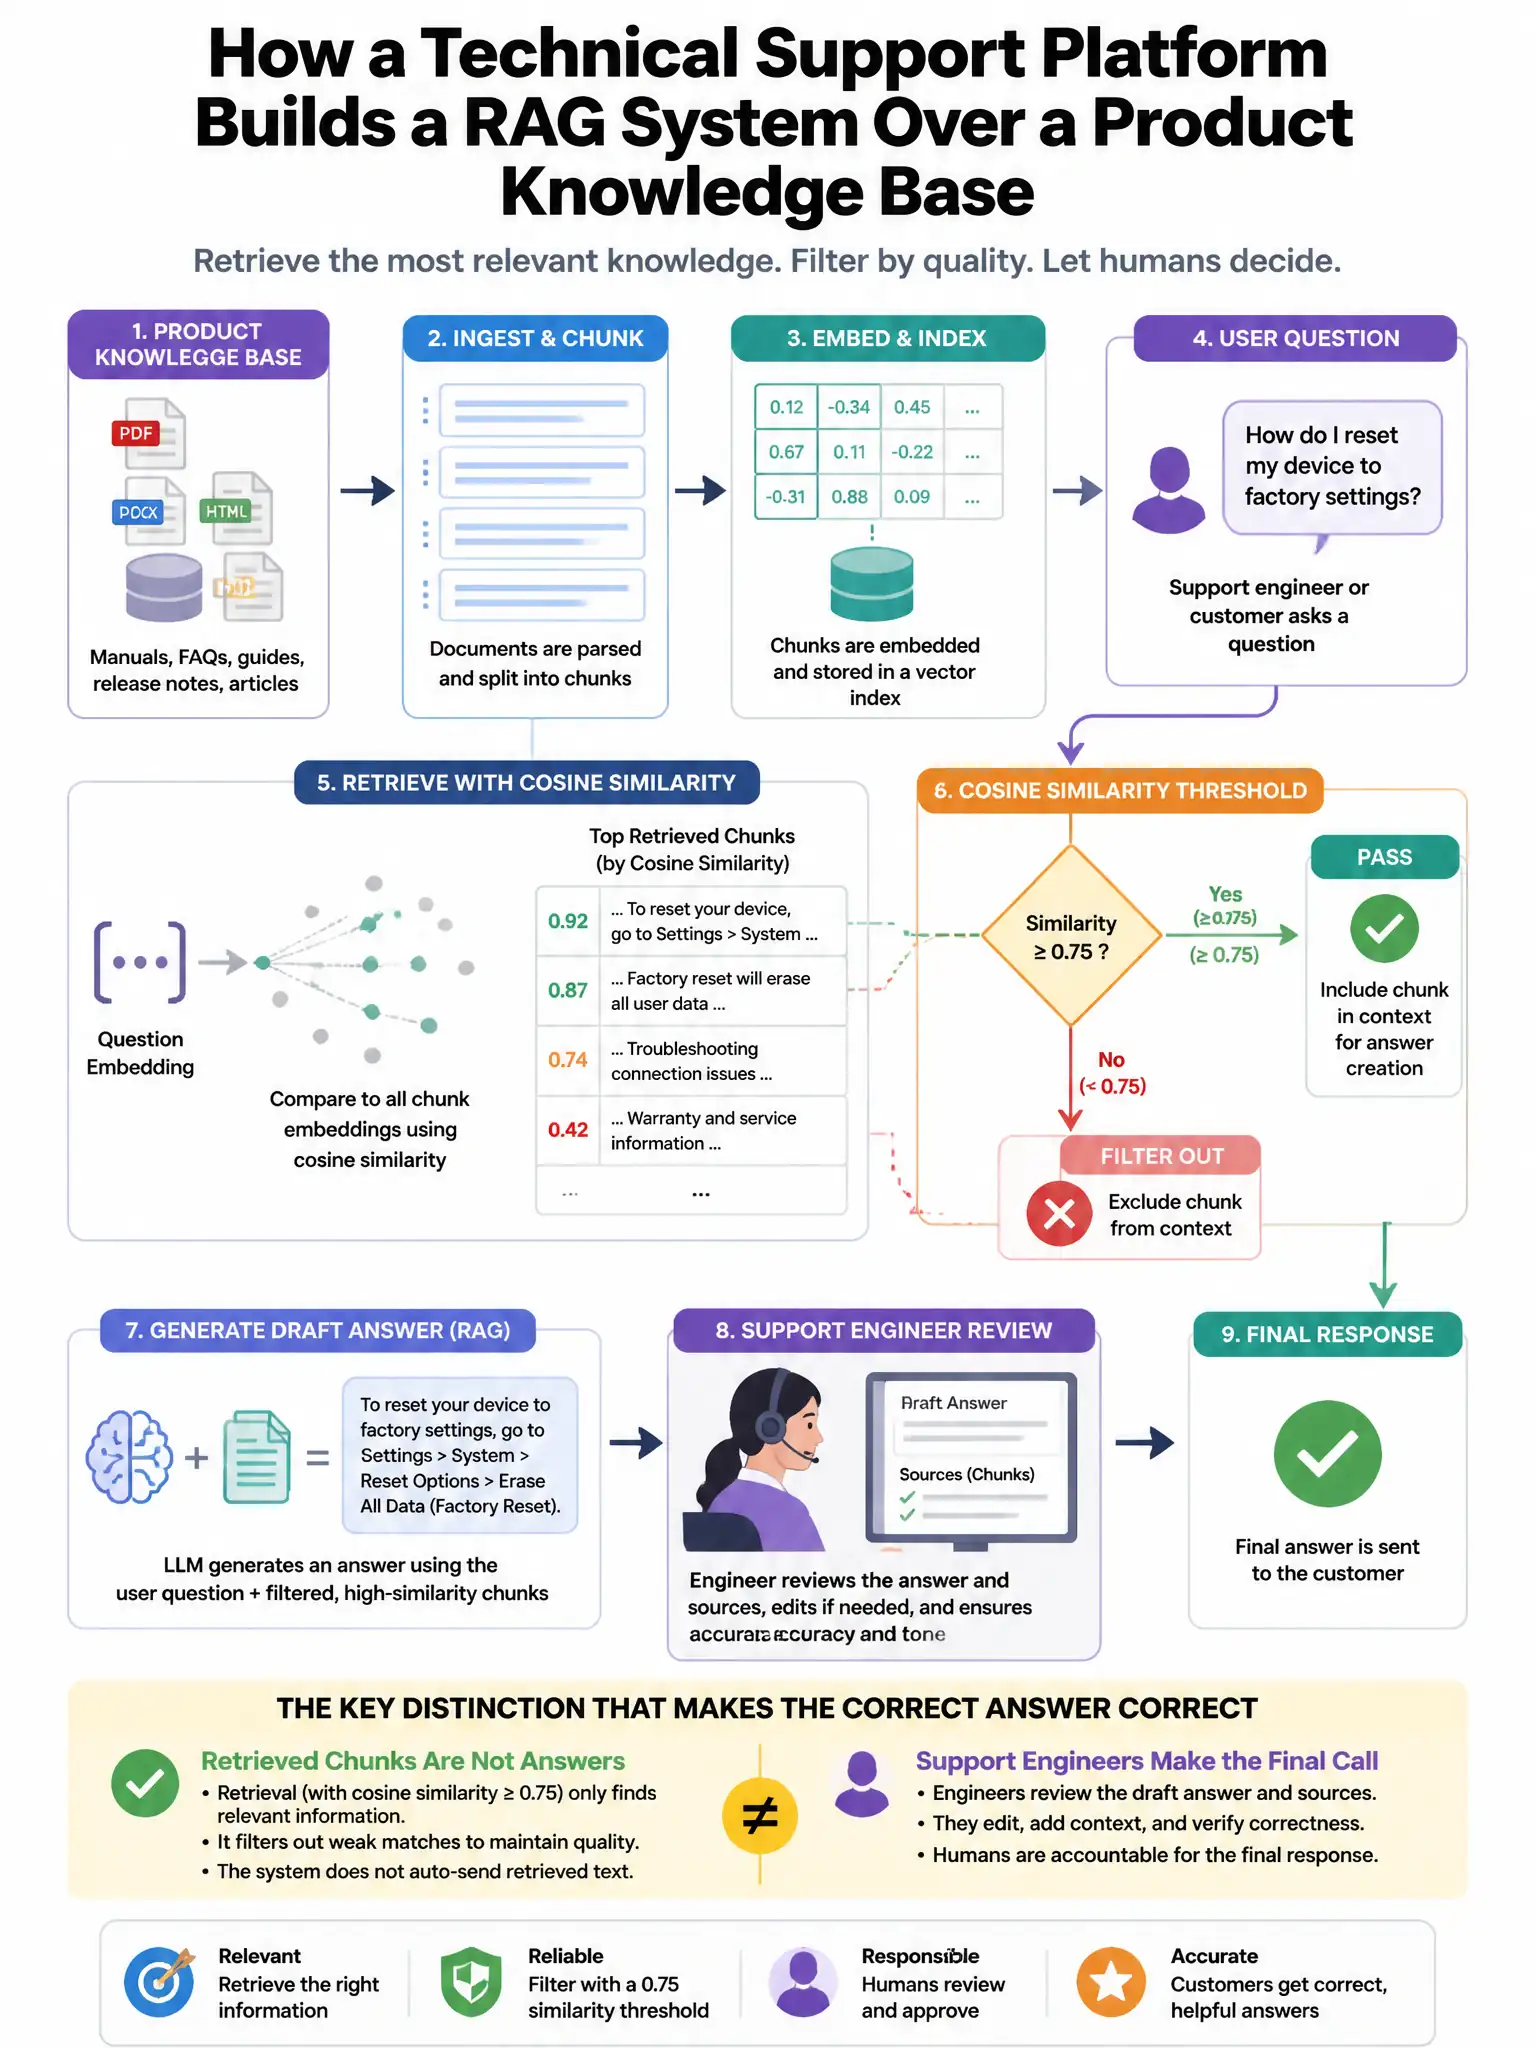
A technical support platform builds a RAG system over a product knowledge base. They use cosine similarity with a threshold of 0.75 to filter retrieved chunks. Support engineers report that the assistant sometimes refuses to answer valid questions, saying 'I don't have information about this topic' — even when the knowledge base contains the relevant article. Analysis shows the relevant article exists but scores 0.73 cosine similarity because the user's question uses different vocabulary than the article. What retrieval quality improvement addresses this without degrading precision?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — query expansion fixes vocabulary mismatch without lowering the bar. You rewrite the question into several synonymous formulations, retrieve for each, then union the hits before applying the 0.75 threshold. That raises recall while keeping precision intact.
Full Explanation
Query expansion addresses vocabulary mismatch (the semantic gap between question vocabulary and document vocabulary) without sacrificing precision. If the user asks 'how do I fix connection errors' but the article discusses 'resolving network timeout issues,' a single embedding may miss the match while multiple query formulations — 'fix connection errors,' 'troubleshoot network timeouts,' 'resolve connectivity problems' — increases the probability that one formulation retrieves the article above threshold. Claude can generate these query variants. The lower-threshold option trades precision for recall — retrieving more chunks means more irrelevant content in Claude's context, increasing hallucination risk and degrading answer quality. The Euclidean-distance option is not a solution to vocabulary mismatch; cosine similarity is the correct metric for high-dimensional embedding spaces. Euclidean distance doesn't address the embedding distance between different vocabulary expressing the same concept. The web-search fallback option is appropriate for knowledge gaps but not for retrieval failures where the knowledge exists internally — it trains users to expect external search for internal product questions.