
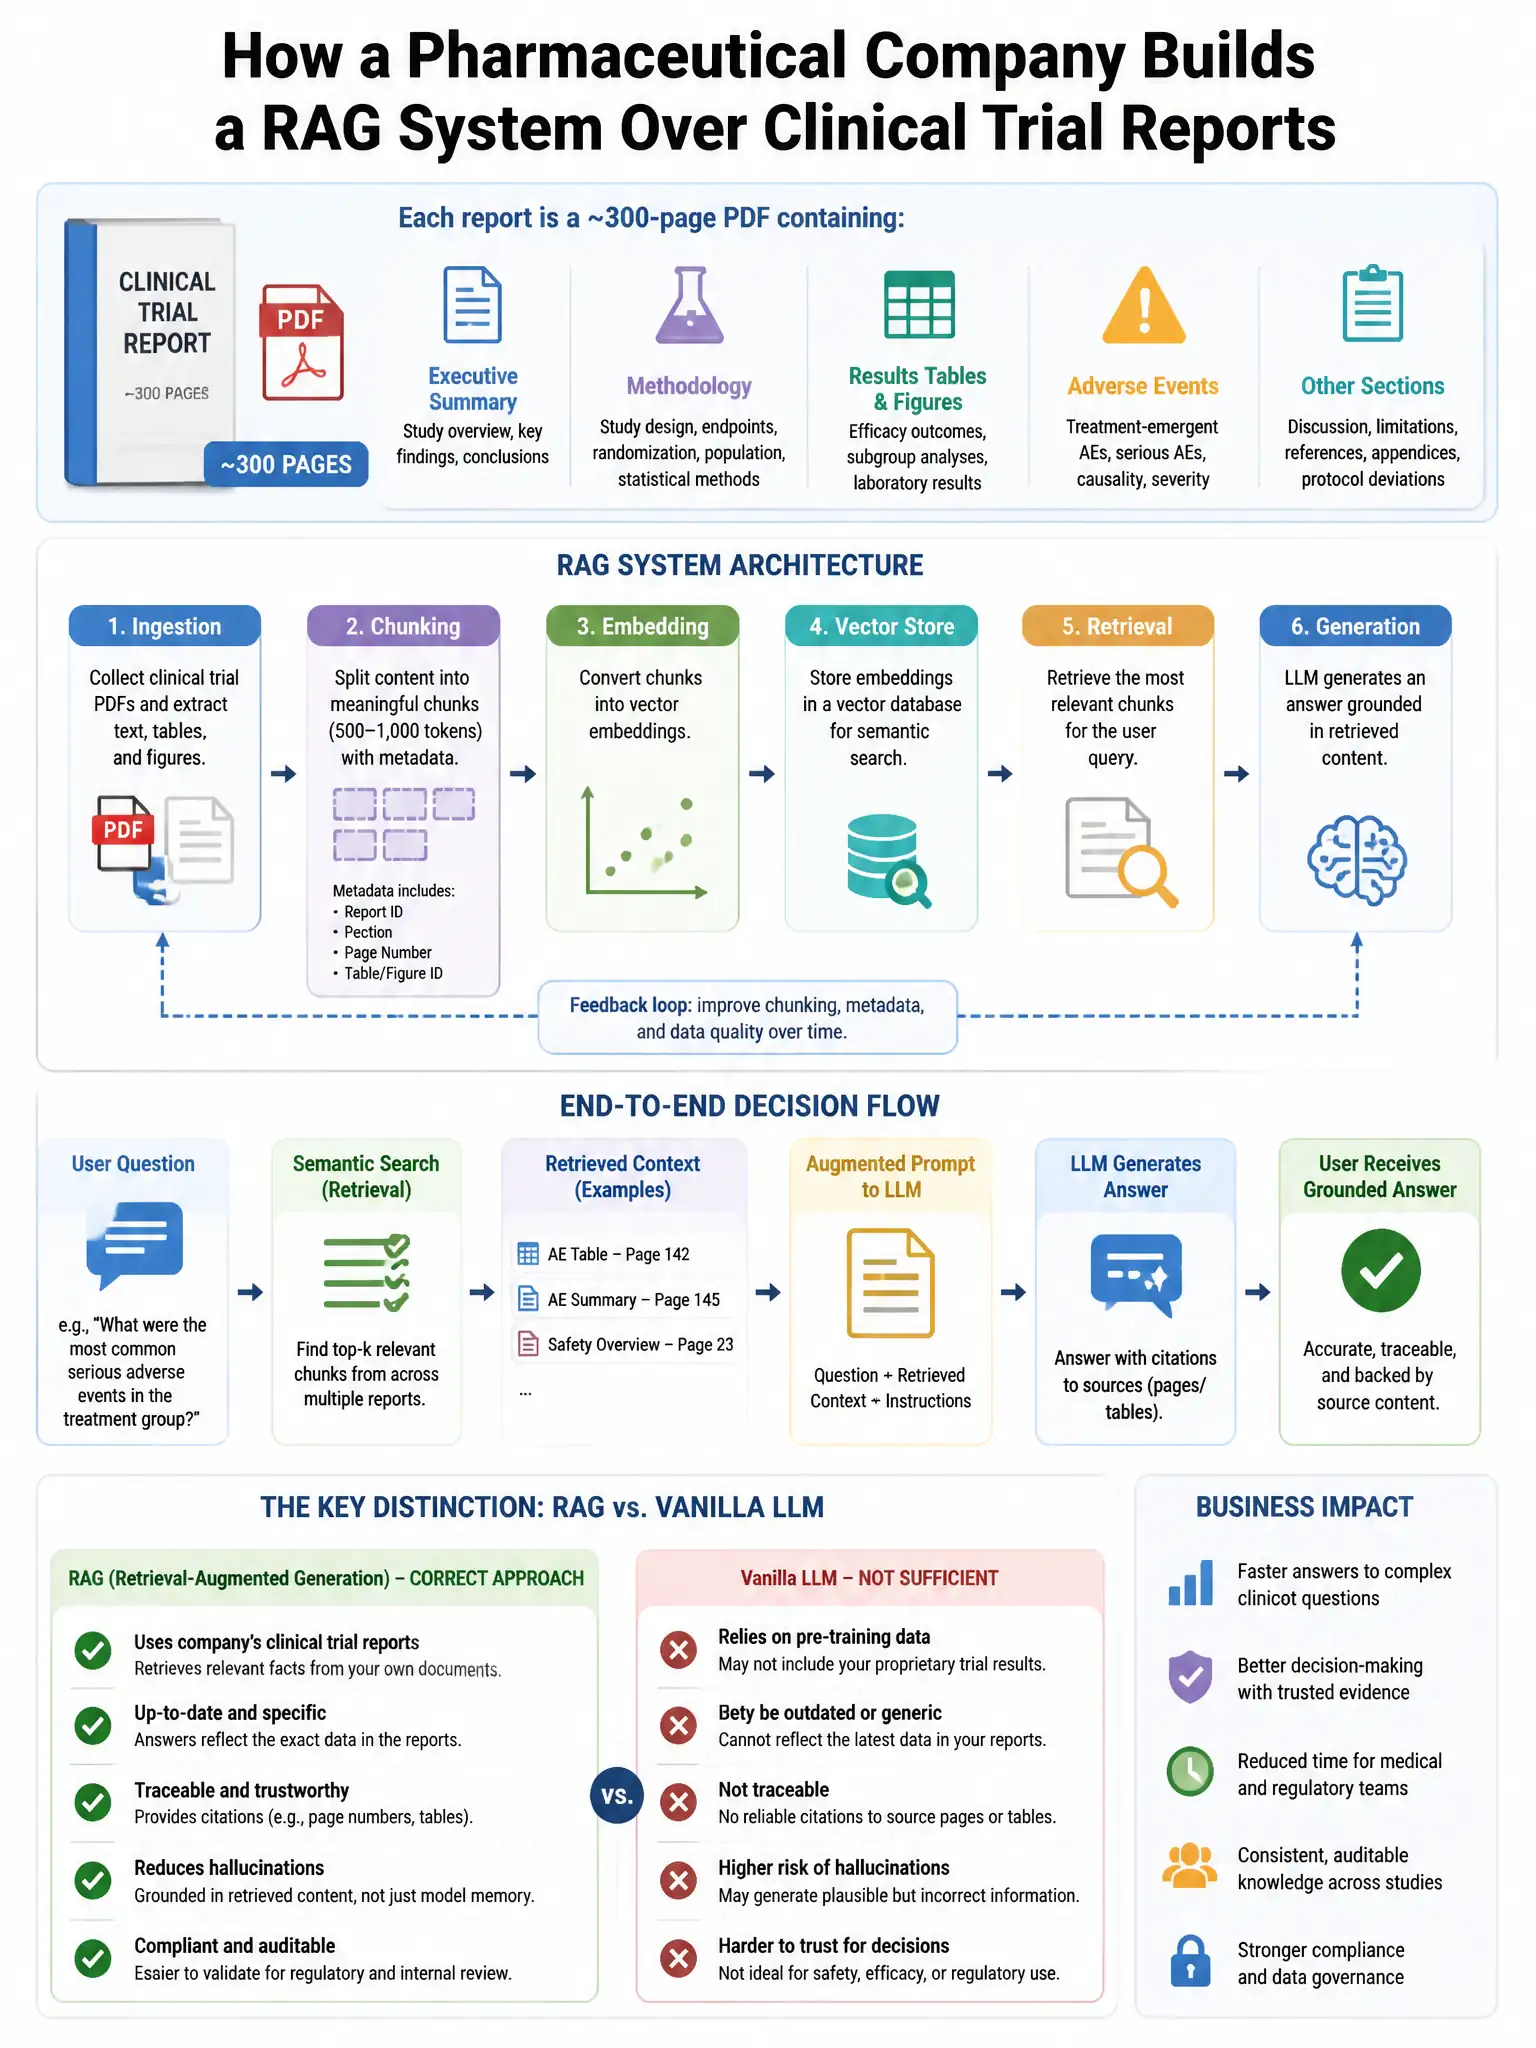
A pharmaceutical company builds a RAG system over clinical trial reports. Each report is a 300-page PDF containing executive summary, methodology, results tables, adverse events section, and regulatory submissions. The team uses fixed-size 512-token chunks. Retrieval quality for questions about adverse events is poor, while retrieval for executive summary questions is good. Investigation shows adverse events sections use highly structured tabular data that loses meaning when chunked at 512 tokens (tables are split mid-row). What document-aware chunking strategy resolves this?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal: you need structure-aware chunking that parses the PDF and cuts at real document boundaries. That keeps tables intact instead of splitting rows, while still letting paragraphs and headers chunk sensibly.
Full Explanation
Structure-aware chunking is the architecturally correct solution for heterogeneous documents. PDFs contain multiple content types with different semantic coherence requirements: paragraphs chunk naturally at sentence boundaries, tables must be kept intact because split tables are meaningless, and section headers provide natural document-level boundaries. The correct strategy parses PDFs to identify structural boundaries, including paragraphs, table boundaries, and section headers, then chunks at those semantic boundaries rather than fixed token counts, keeping tables intact as single chunks regardless of token count. Chunking at detected structural boundaries preserves content integrity: each table becomes one chunk even if it reaches 800 tokens, while each short paragraph becomes a smaller chunk. The larger fixed-size approach, such as increasing chunks to 2,048 tokens, is blunt: it might fit small tables but still splits large ones, and it creates unnecessarily large chunks for narrative text, degrading retrieval precision. The approach that extracts tables separately, converts them to natural language descriptions before chunking, and indexes them separately from narrative text loses the structured data format that Claude can reason over precisely; converting 'Adverse event: Nausea, Incidence: 23%, Severity: Grade 2' to natural language introduces approximation and loses queryability. The table-filtering approach eliminates adverse events data entirely, directly causing retrieval failures rather than fixing them.