
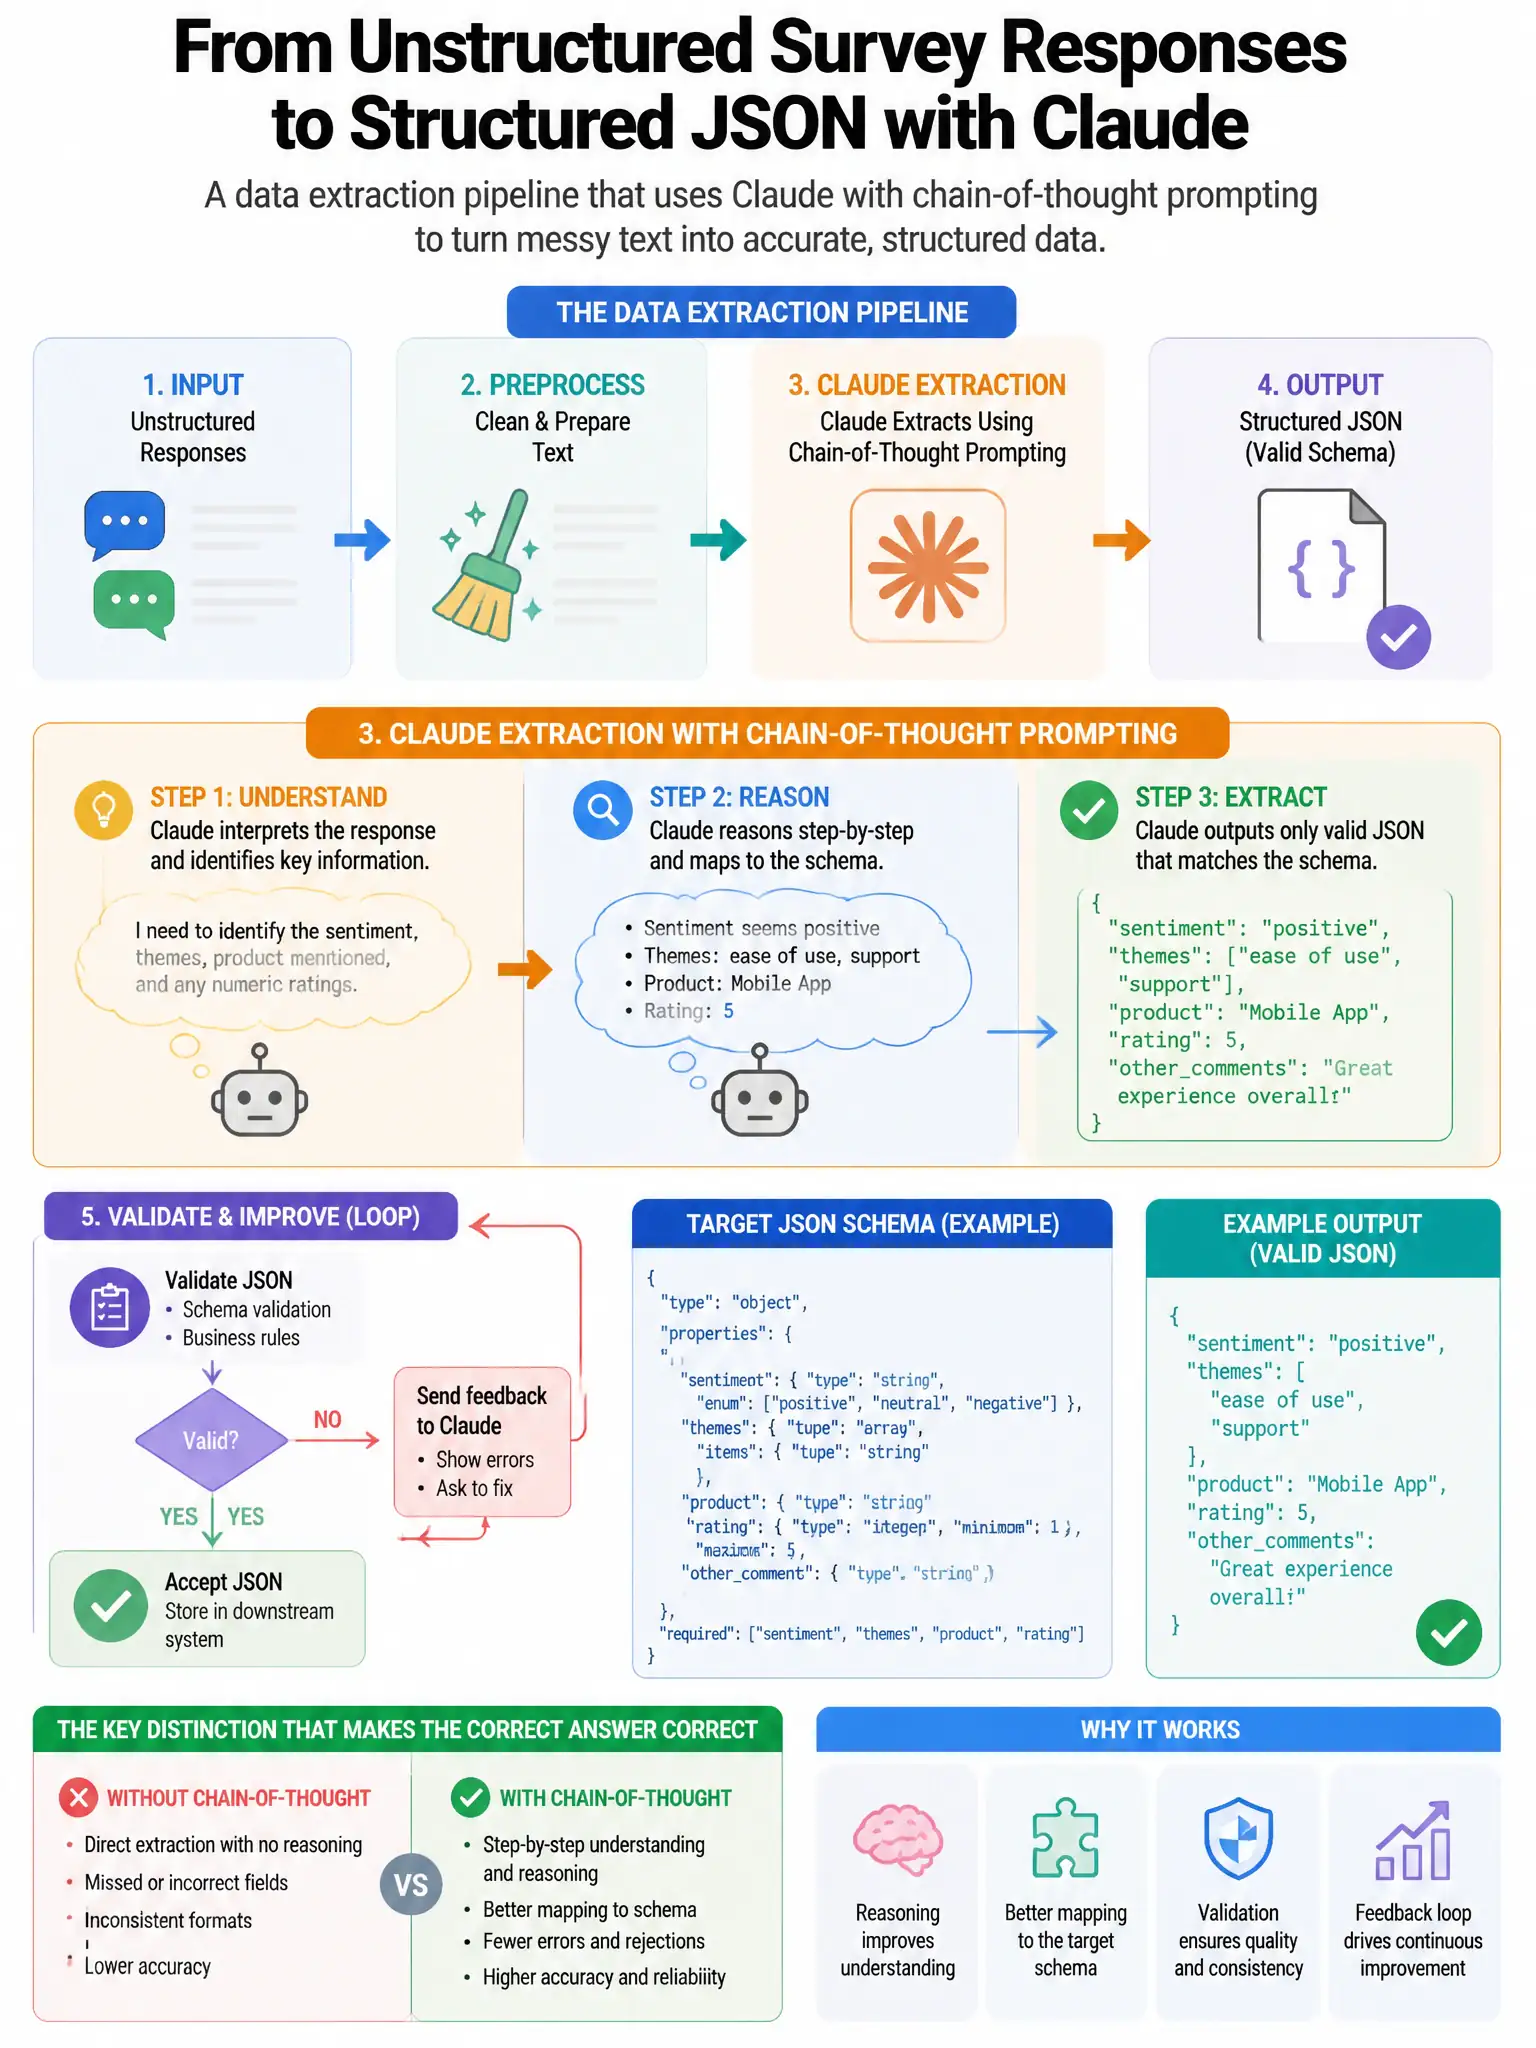
A data extraction pipeline uses Claude to convert unstructured survey responses into a structured JSON schema. The team adds chain-of-thought prompting to improve accuracy. They observe that adding 'Think step by step before responding' increases accuracy from 87% to 94% but also increases average response token length from 200 to 800 tokens, quadrupling output costs. What architectural pattern captures most of the accuracy gain while minimizing token cost?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — tell Claude to reason internally, then output only the final JSON. You get the accuracy boost without paying for verbose visible reasoning tokens. It keeps the output compact while still guiding the model through the extraction.
Full Explanation
Instructing Claude to reason internally and output only the final structured answer is the most direct solution: the reasoning guidance improves extraction accuracy without generating verbose visible reasoning tokens in the output. This technique exploits Claude's ability to use reasoning implicitly while constraining output format. The output remains compact JSON. The option to remove chain-of-thought and accept the 87% accuracy is wrong because it abandons a meaningful 7% accuracy gain for a cost optimization that the internal-reasoning instruction already solves. The option to use chain-of-thought in a two-pass architecture is wrong because it uses two API calls, increasing cost and latency rather than minimizing token cost. The option to use extended thinking with a separate reasoning block that can be excluded from billed output is wrong because it depends on a special reasoning block being available and reliably excluded from billed output; the scenario does not guarantee that, and it adds capability dependency and complexity when the simpler internal-reasoning instruction is sufficient for this moderate-complexity structured extraction.