
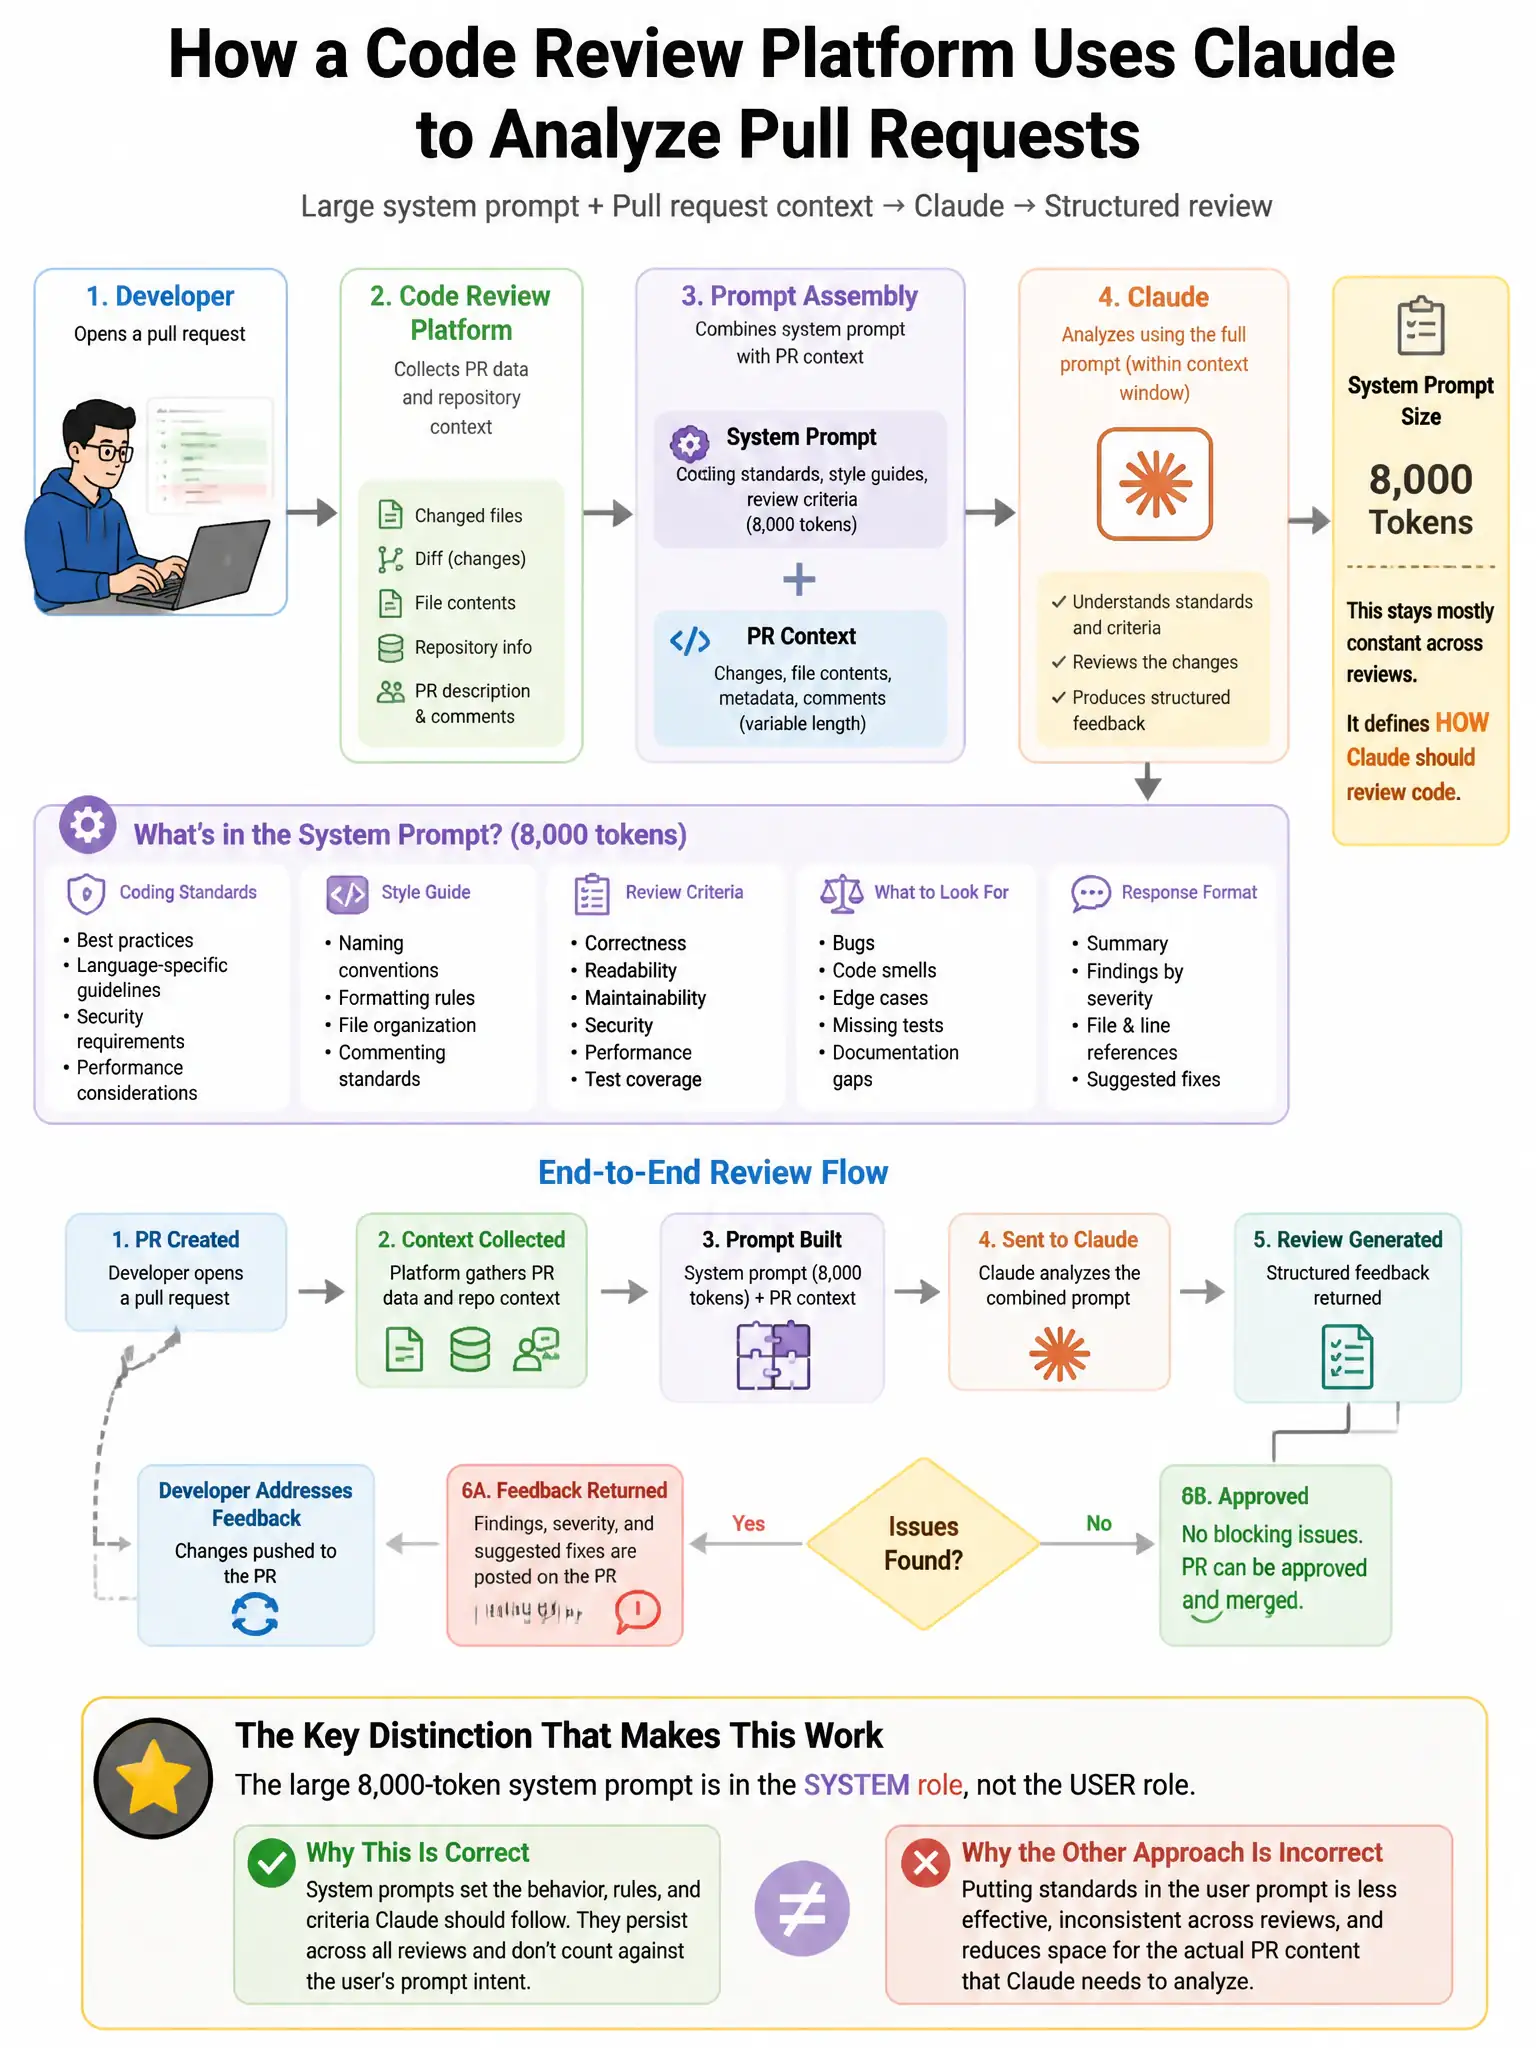
A code review platform uses Claude to analyze pull requests. Their system prompt defines coding standards, style guides, and review criteria (8,000 tokens). They implement prompt caching and observe that cache hit rates are only 40% despite high traffic. Investigation reveals that a timestamp and request ID are being prepended to the system prompt for audit logging purposes. What is the root cause and fix?
Select an answer to reveal the explanation.
Short Explanation
Prompt caching only works when the cached prefix stays byte-for-byte identical. A timestamp or request ID prepended to the system prompt changes every call, so the cache can't match. Move that audit metadata out of the prompt and keep the coding standards at the start.
Full Explanation
Prompt cache matching requires a byte-identical prefix up to the cache_control marker. A timestamp or request ID prepended to the system prompt makes every request's prefix unique, invalidating caching for those requests. The observed 40% hit rate likely reflects only the fraction of requests that coincidentally share the same timestamp second, which can happen in high-throughput scenarios. The fix is to keep audit metadata out of the prompt: put the request ID and timestamp in an HTTP header, a database log entry, or a separate audit trail so the prompt remains stable and cacheable. The claim that prompt caching requires the same API key on every request is incorrect because prompt caching is per-organization, not per-API-key. The claim that the system prompt is too long because cached prefixes above 4,000 tokens reduce hit rates is incorrect because Anthropic's cache supports prompts well beyond 8,000 tokens. The claim that a 40% hit rate is the theoretical maximum for text-based prompts is also incorrect; there is no such ceiling, and properly implemented caching should approach near-100% hit rates for stable system prompts under sustained load.