
A team is implementing MCP (Model Context Protocol) to expose internal tools to Claude agents. They need to expose a customer database query tool. What is the primary architectural benefit of MCP over custom tool definitions in the API request payload?
Select an answer to reveal the explanation.
Short Explanation
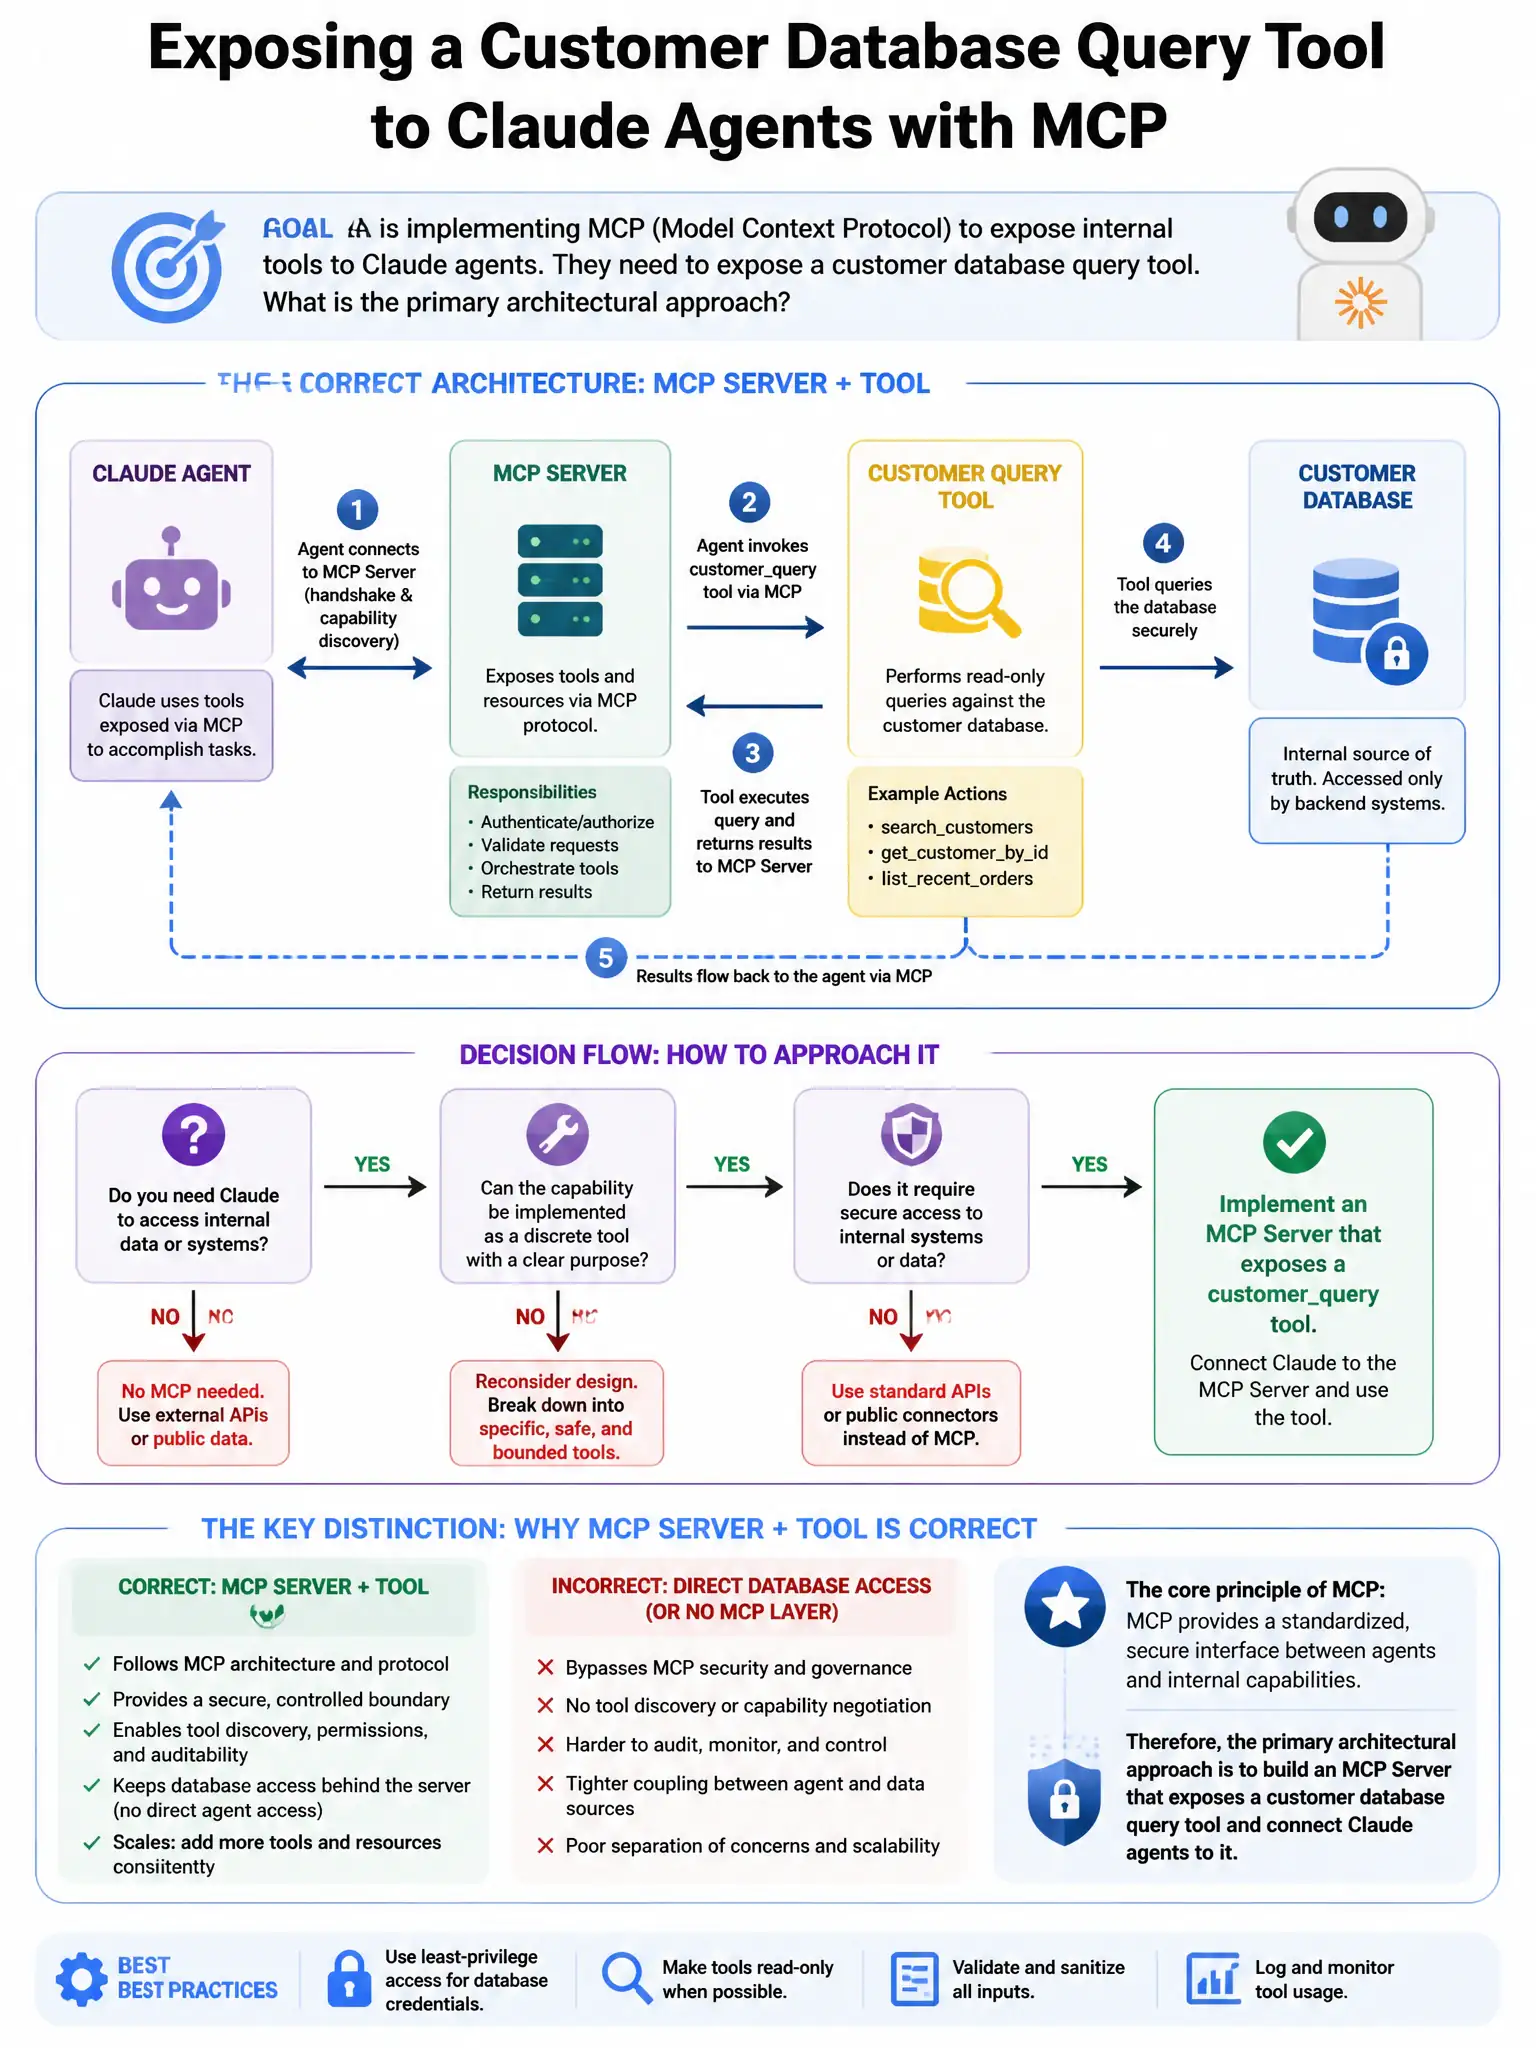
Here's the deal — MCP gives you a standard server-based way to define tools once and reuse them across agents and clients. You don't have to redefine tool schemas in every API call, which keeps tool implementation separate from tool consumption.
Full Explanation
MCP's primary architectural benefit is standardization and reuse: tools are defined once on an MCP server and can be discovered and used by any MCP-compatible client (Claude agents, Claude desktop, third-party clients) without re-implementing tool schemas in each API call. This creates a separation between tool implementation (MCP server) and tool consumption (agents), enabling a shared tool ecosystem. The claim that MCP tools execute faster because they bypass the token processing pipeline is incorrect — MCP tools don't execute faster; they're exposed over a protocol (stdio or HTTP) and go through the same API tool-calling mechanism. The claim that MCP automatically validates tool outputs against Claude's safety policies is incorrect — MCP does not provide automatic safety validation of tool outputs; that responsibility remains with the application layer. The claim that MCP is required by Anthropic for any tool that accesses external data sources, while custom tool definitions are only for in-memory computations, invents an Anthropic requirement that doesn't exist; custom API tool definitions are fully supported and commonly used in production.