
A production system uses Claude 3 Opus for complex reasoning tasks. The team wants to reduce costs by 60% without degrading output quality on their specific use case — generating structured JSON reports from unstructured sales data. Which approach should an architect recommend first?
Select an answer to reveal the explanation.
Short Explanation
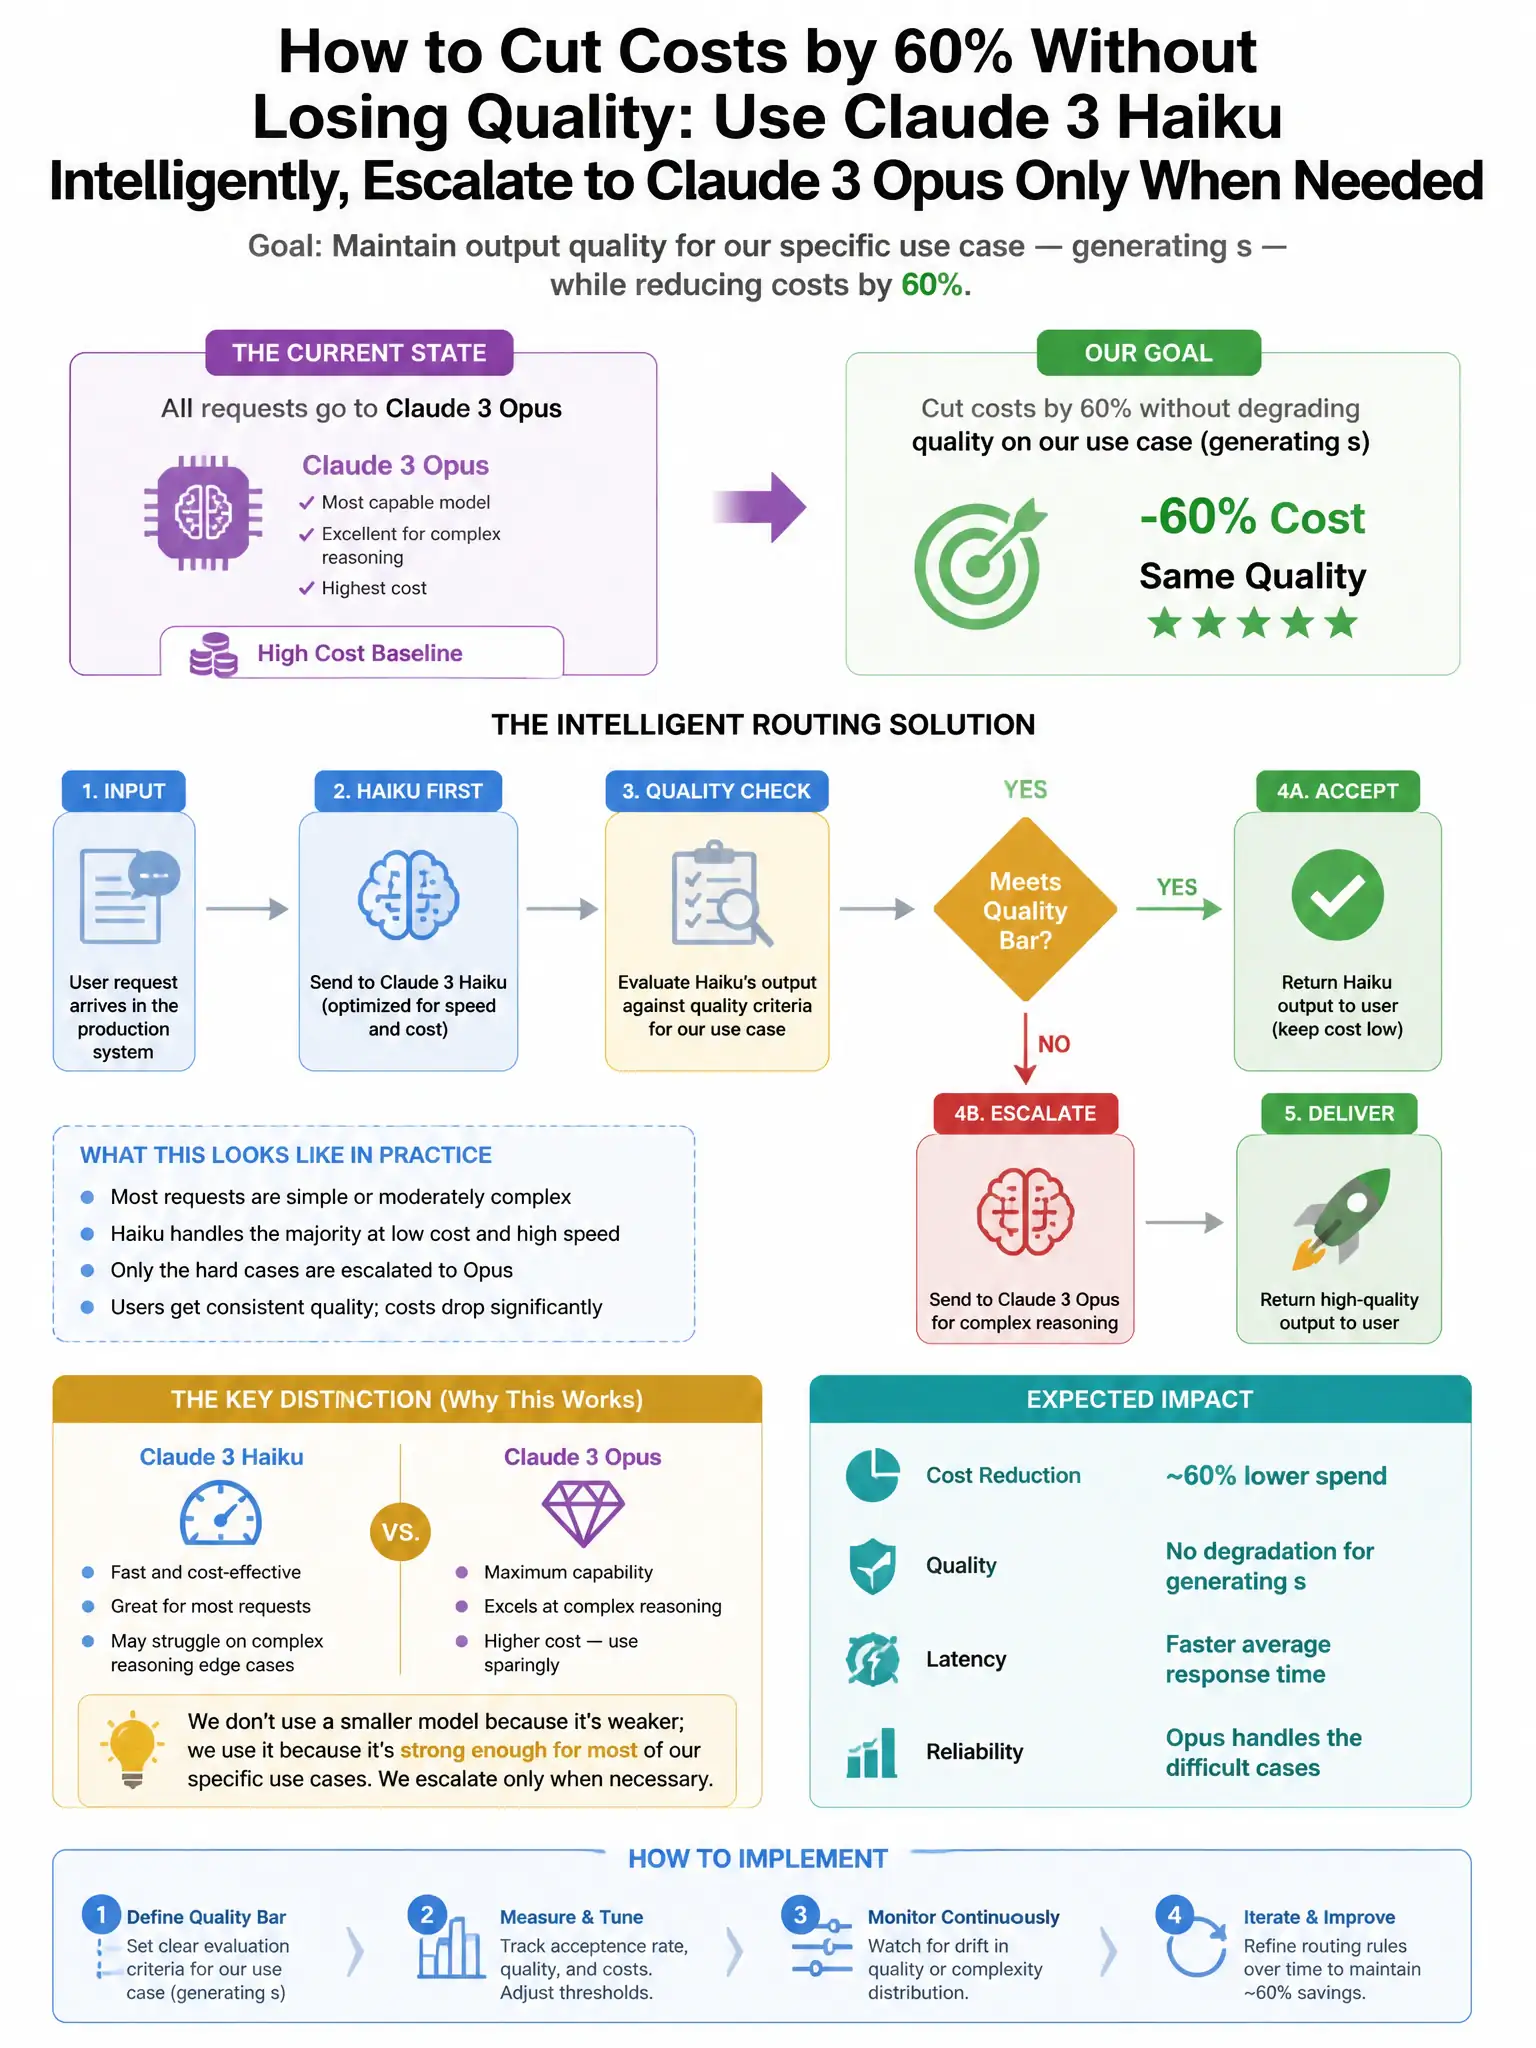
Here's the deal — before you downgrade a production model, you need proof it won’t hurt quality. Benchmark Claude 3.5 Sonnet against Claude 3 Opus on your real sales-data reports first, because it often matches Opus on structured extraction and costs less, but you must validate that on your dataset.
Full Explanation
Before making a model downgrade decision for generating structured JSON reports from unstructured sales data, an architect must establish ground truth on quality equivalence for the specific task. Claude 3.5 Sonnet often matches or exceeds Claude 3 Opus on structured extraction tasks due to its improved training, and costs significantly less, but this must be validated on the actual dataset, not assumed. Side-by-side benchmarking on representative samples quantifies the real quality delta and makes the business case defensible. The immediate switch to Claude 3 Sonnet skips validation and risks quality regression on a production system. Prompt caching on the system prompt and few-shot examples reduces input token costs while keeping Claude 3 Opus, but it typically does not deliver a 60% reduction if Opus remains the model; caching primarily helps with repeated system prompts. Output caching at the application layer helps only for identical inputs, providing no savings on novel sales data, which is the primary use case.