
A municipal rain-barrel newsletter job is scored by how much a generated summary overlaps a reference summary. Which metric family is that?
Select an answer to reveal the explanation.
Short Explanation
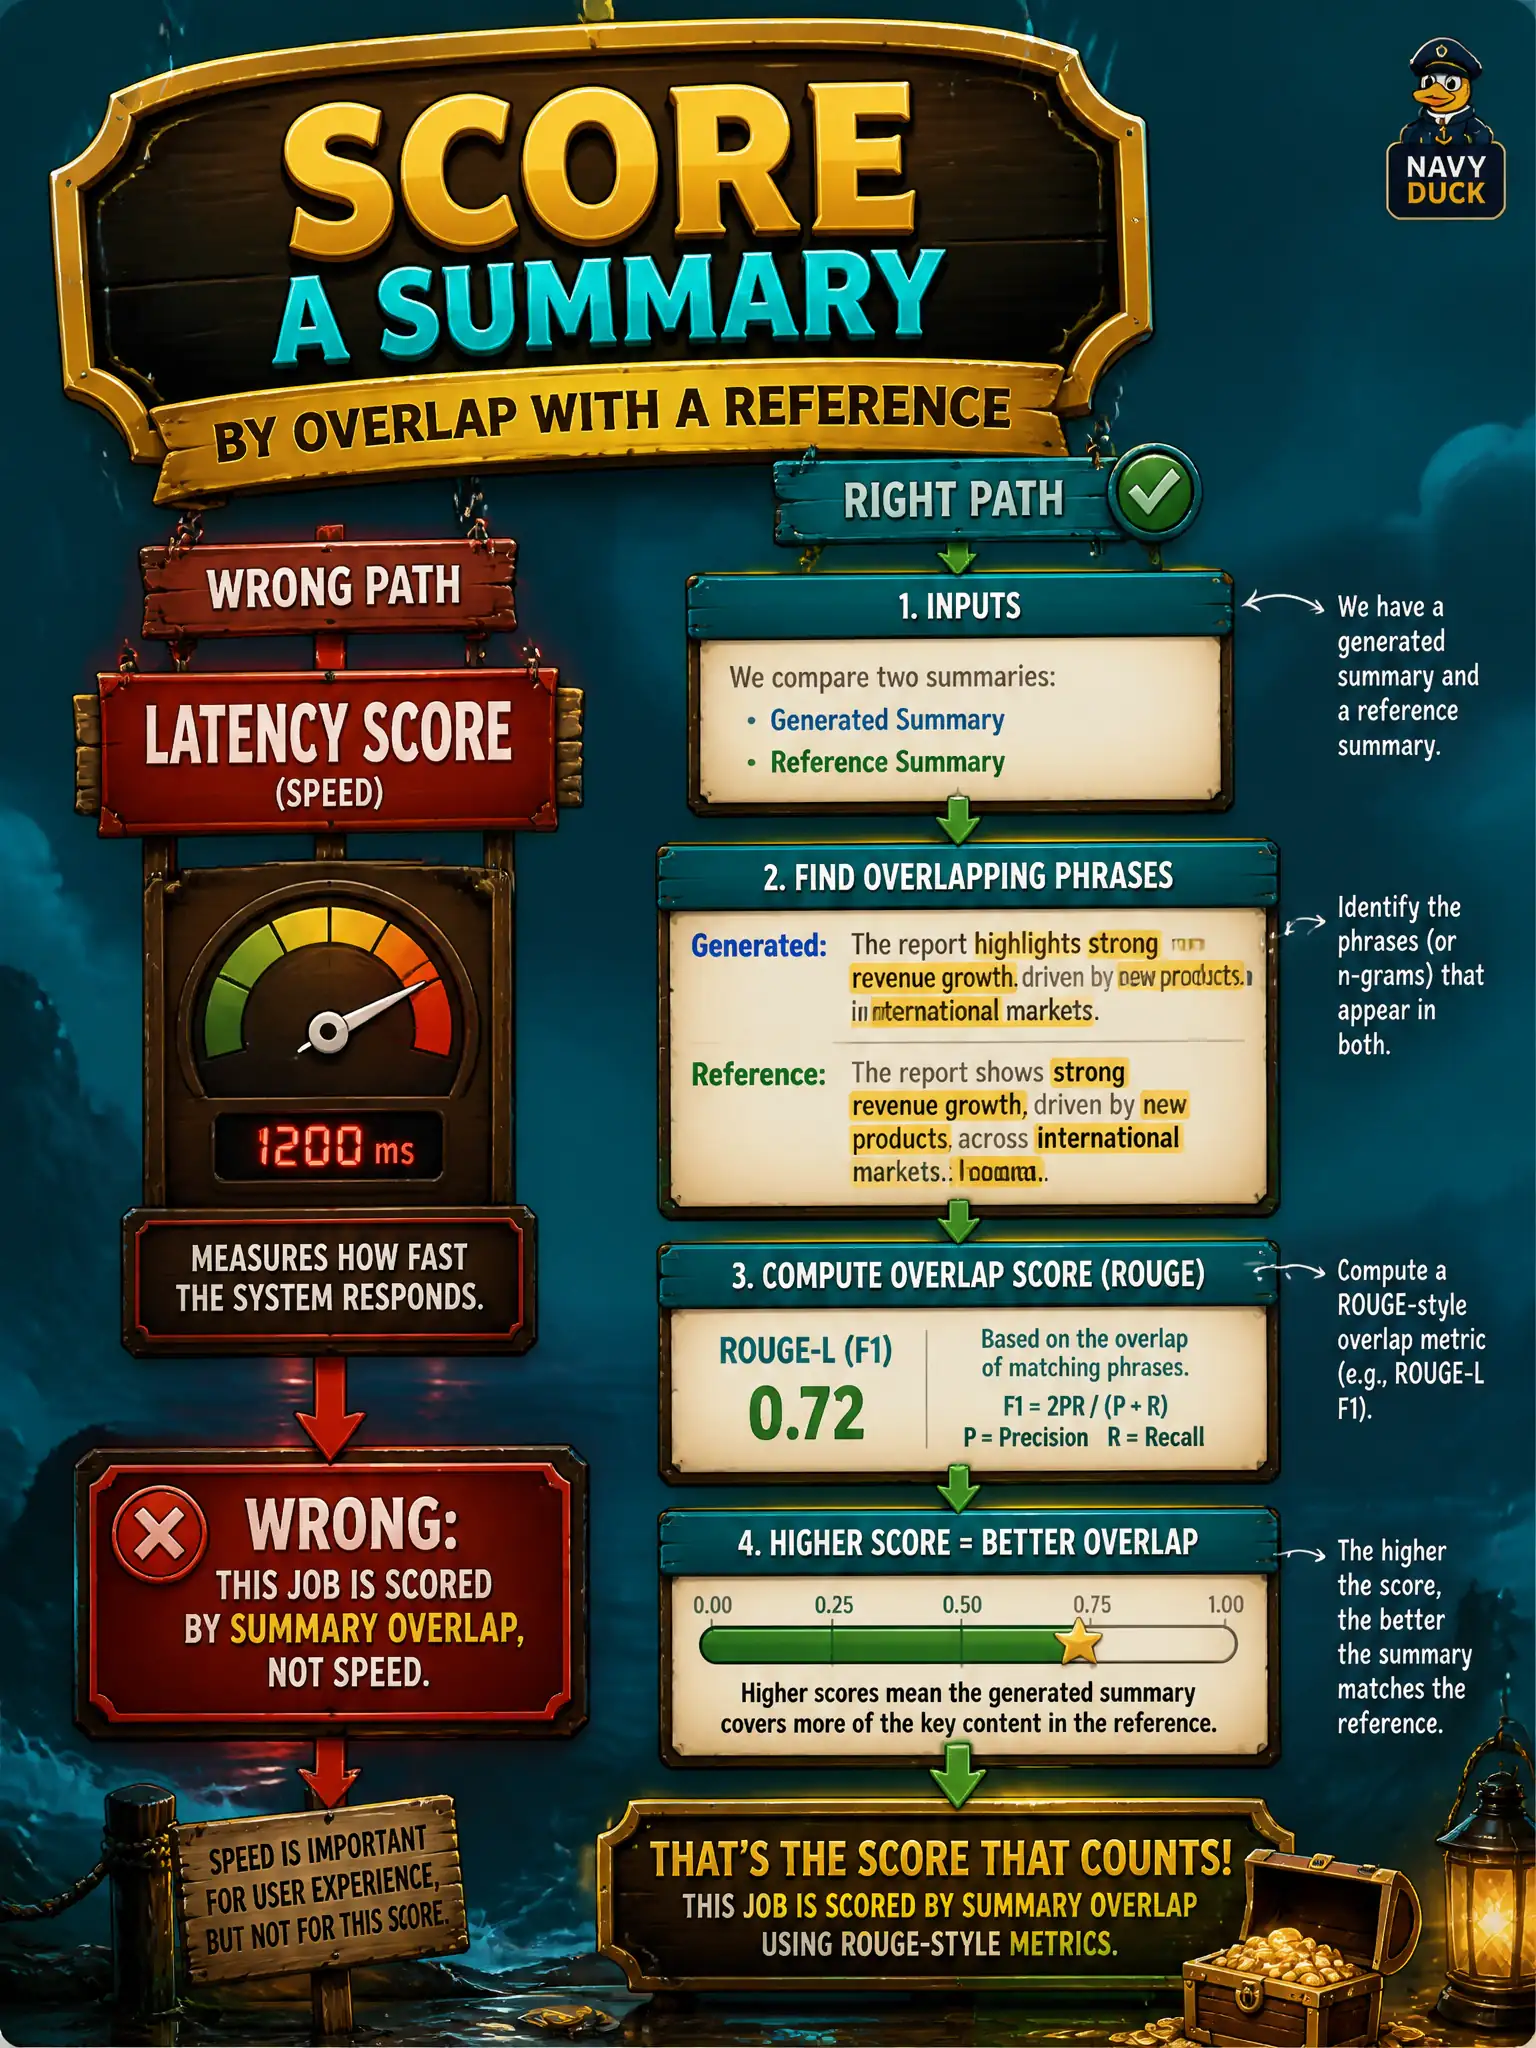
Think of scoring a rain-barrel summary by how much it overlaps a reference. That is a ROUGE-style overlap metric. BLEU is the usual translation name, and a guardrail or an endpoint is not a summary score.
Full Explanation
When a municipal rain-barrel newsletter summary is scored by how much it overlaps a reference summary, the metric family is ROUGE-style overlap. ROUGE looks at n-gram or subsequence overlap between candidate and reference text and is the conventional automatic score for summarization tasks. That framing fits a newsletter job where staff already have a gold summary and want a repeatable overlap signal across model or prompt changes.
BLEU is the classic automatic name for translation n-gram overlap; treating summarization as if it were translation mislabels the usual metric family even though both are overlap-based. A PII guardrail redacts or blocks sensitive identifiers; it does not score summary overlap. Provisioned throughput is a capacity and pricing construct for dedicated inference; it is not a text metric at all.
Exam caveat: ROUGE can look strong when the summary copies brochure wording yet still invents or omits facts—overlap is not faithfulness. Pair ROUGE with groundedness checks when civic content carries numbers or eligibility claims.
Operational check: freeze a small reference-summary set for the rain-barrel newsletter, score candidate outputs with the same ROUGE configuration each release, and spot-check a sample where overlap is high but a human reviewer still finds missing or invented details.