
The same wind ensemble wants a managed way to compare two Bedrock models on the same prompt set, with automatic scoring and an optional human pass. Which AWS feature is that?
Select an answer to reveal the explanation.
Short Explanation
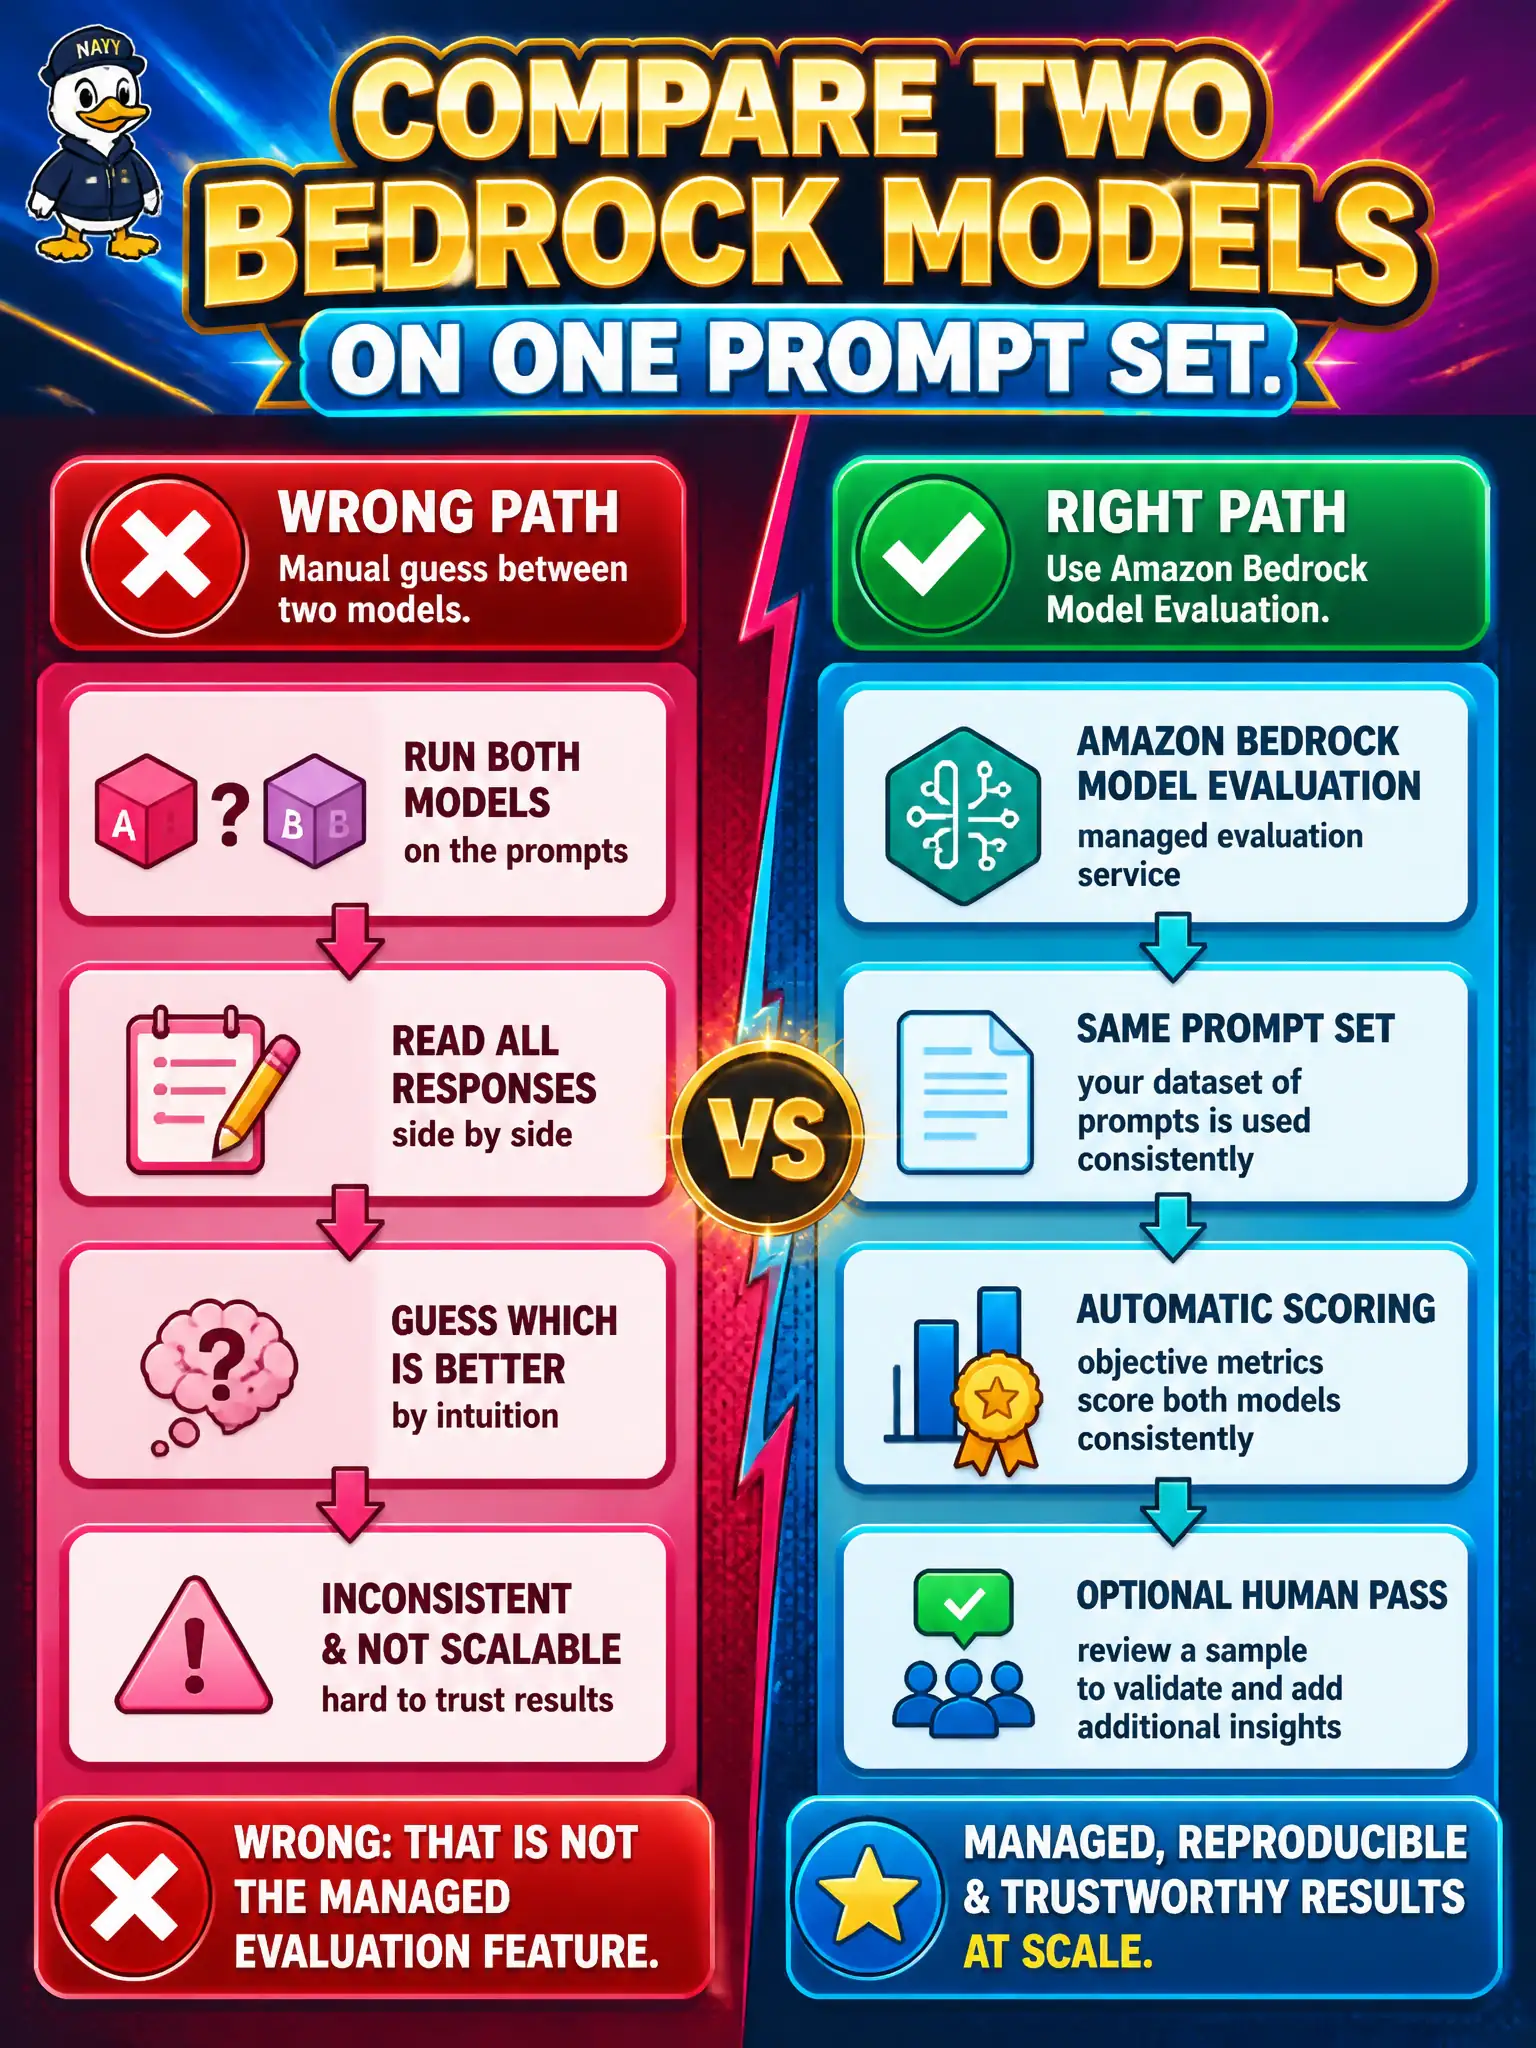
Think of lining up two Bedrock models on the same prompt set, with automatic scores and an optional human pass. That is Amazon Bedrock Model Evaluation. Prompt Management versions prompts. Quick and Transcribe do not run that bake-off.
Full Explanation
Amazon Bedrock Model Evaluation is the managed path for lining up two foundation models on the same prompt set, collecting automatic scores, and optionally adding a human review pass. That matches what the wind ensemble needs: a controlled bake-off without standing up a custom scoring pipeline or rewriting prompts for each candidate. The feature is purpose-built for model comparison under Bedrock, so automatic metrics and human judgments attach to the same evaluation job rather than living in separate spreadsheets.
Prompt Management is about storing and versioning prompts, not about running a model-versus-model comparison job. Version history helps reproducibility of prompts, but it does not produce automatic model scores or an optional human pass across two FMs. QuickSight-style charting (often abbreviated casually as “Quick” in distractors) visualizes data; it is not a Bedrock model evaluation job. Amazon Transcribe converts speech to text; it does not score two foundation models against a shared prompt set.
Exam caveat: do not confuse prompt versioning with model evaluation. Both improve quality workflows, but only Model Evaluation is the managed comparison surface for FMs on Bedrock.
Operational check: define the shared prompt set and scoring dimensions before you launch the job, then confirm that both candidate models receive identical inputs and that human review criteria are written down before anyone looks at side-by-side outputs.