
A volunteer lake-rescue service must exclude patient identifiers and unapproved photos from any customization set. What part of data preparation is that?
Select an answer to reveal the explanation.
Short Explanation
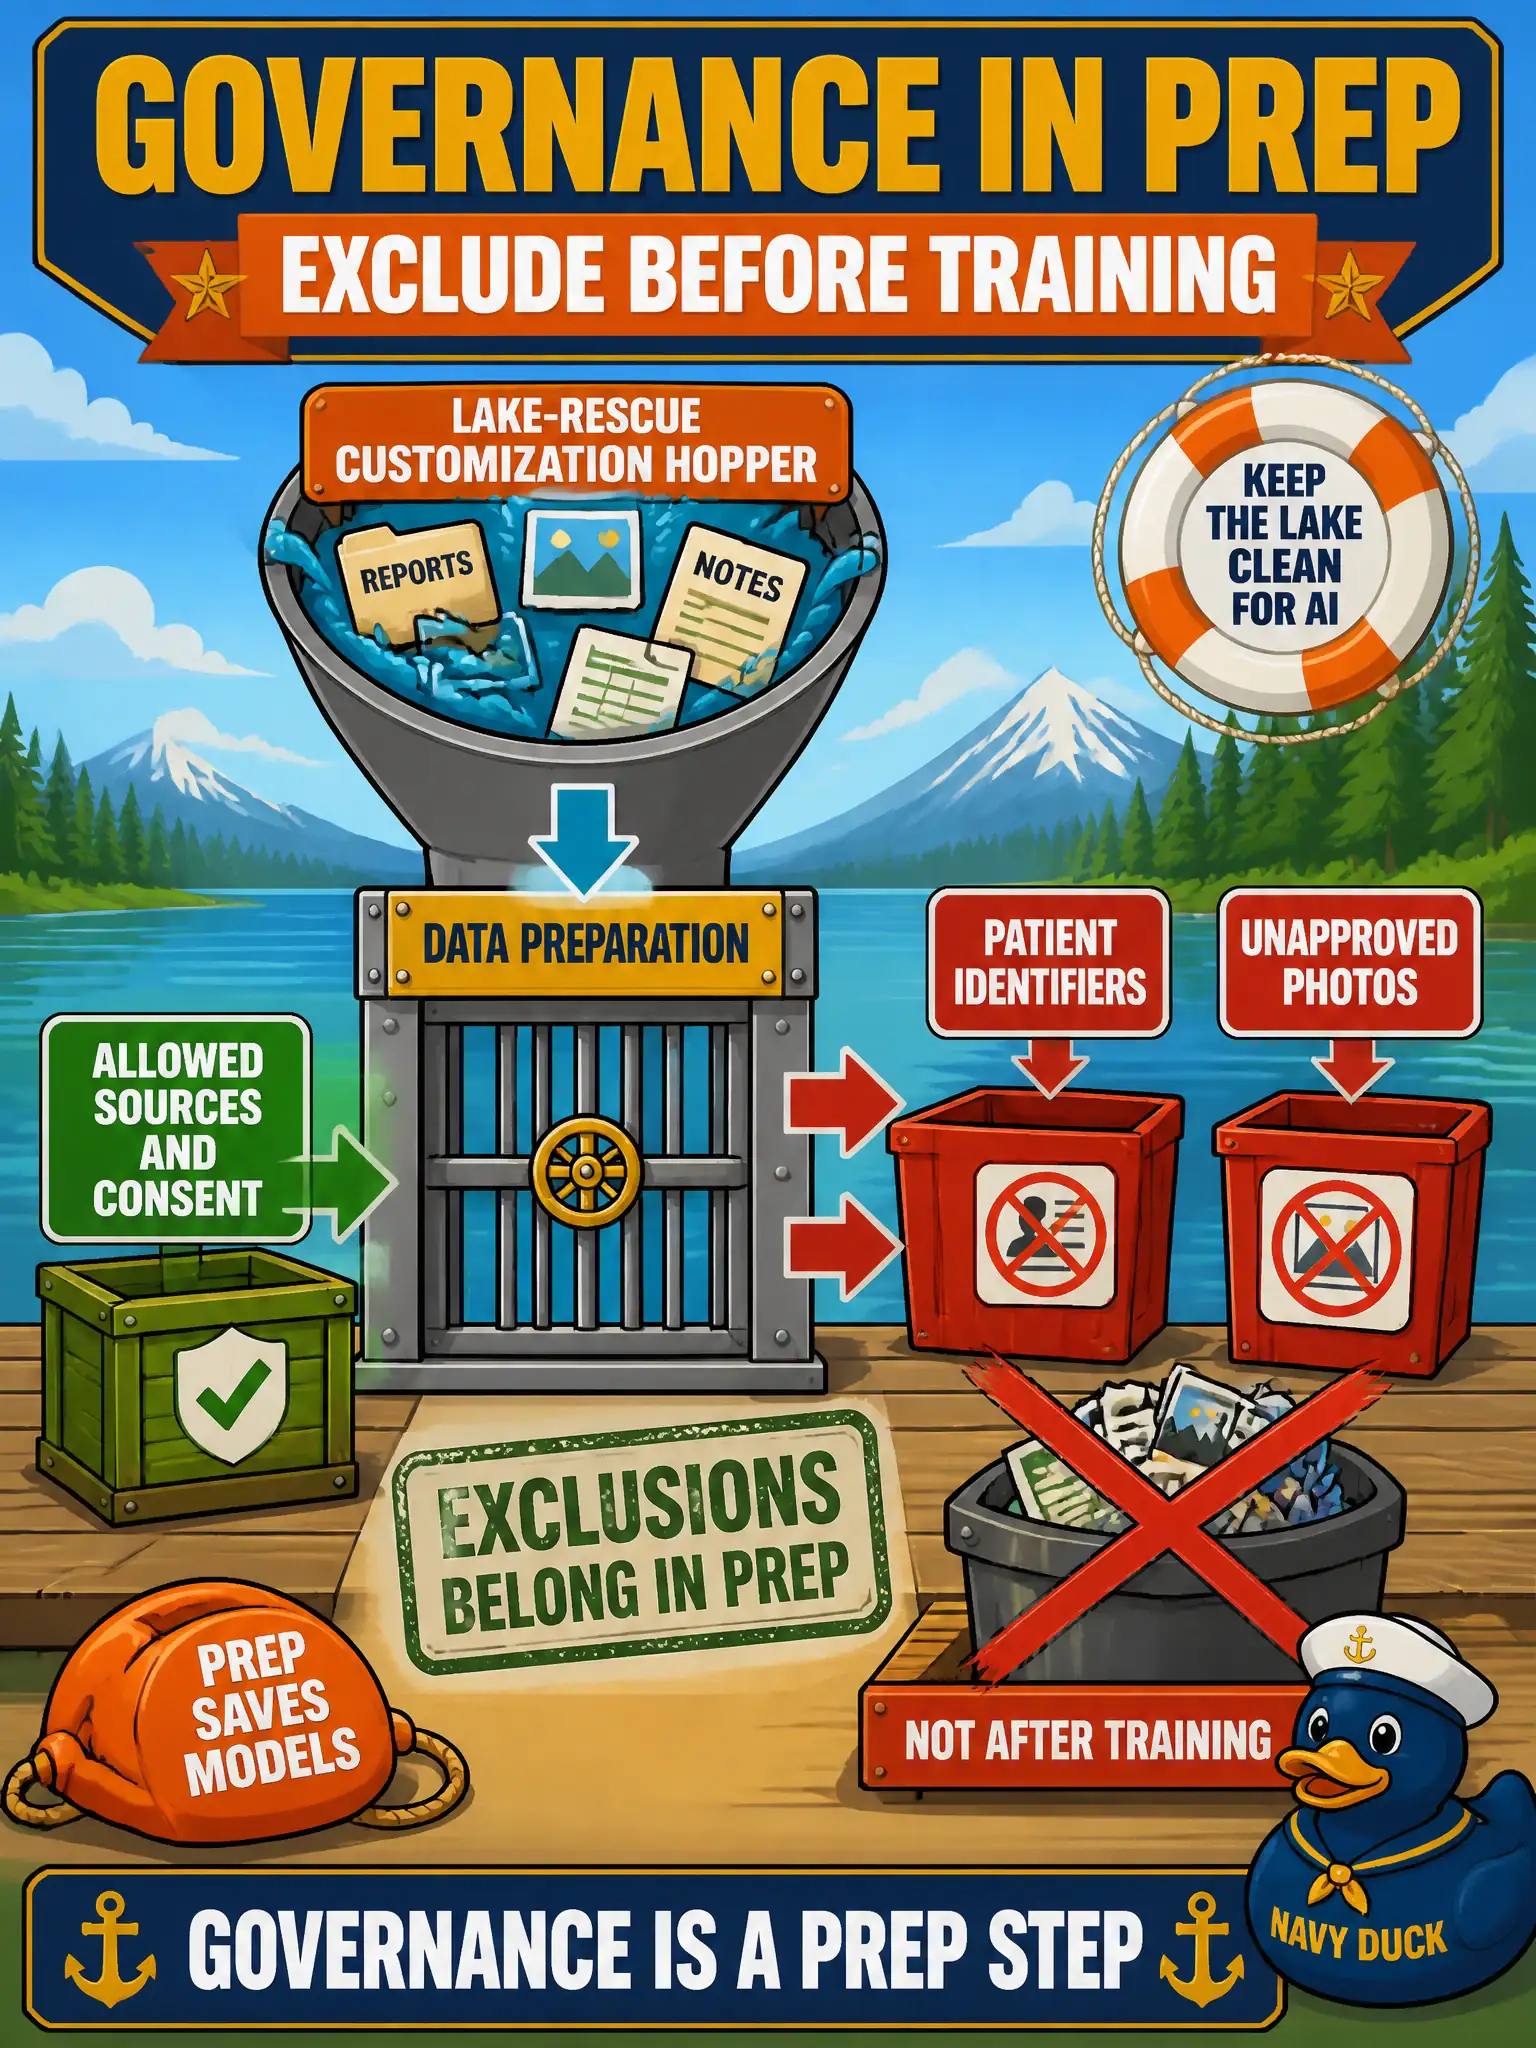
Think of keeping patient IDs and unapproved photos out of the customization set. That is governance in prep, not a later essay.
Full Explanation
Excluding patient identifiers and unapproved photos from a volunteer lake-rescue customization set is governance during data preparation: decide allowed sources, consent, and exclusions before any training job starts. Governance belongs in prep because once sensitive material enters the training set, removal is harder and leakage risk rises for later model behavior, checkpoints, and logs. Deferring the issue to a later security essay while leaving identifiers in today’s set violates the control timing the rescue service needs. Raising temperature does not remove identifiers from weights or from the dataset sitting on disk. Prompt caching is not a consent mechanism and does not document photo approvals for volunteers. Exam caveat: governance includes legal and policy constraints that can block an otherwise “high quality” dataset—exam items often test that prep includes permissions, not only cleaning or formatting. Operational check: run an automated PII and media-approval scan on the candidate set and block the customization job until exclusions and consent evidence are recorded in the prep ticket. Keep an exclusions log so future rescue seasons know which sources were barred and why.